orchestrata_ultimate.agents.volks.codedirector.implementation
Reference › orchestrata_ultimate › agents › volks › codedirector › implementation
implementation holds the helpers behind the CodeDirector's three implementation paths: skeleton, swarm and serial (volk calls them; review imports some of them). extract_design_docs reads the design documents from an implement packet. generate_skeleton_files creates the skeleton: _load_gen_skeleton_functions imports the real gen-skeleton API from the AST toolkit script and _generate_skeleton_from_contract builds files from a Mermaid class diagram. get_fan_out_decision asks a Prolog engine (shape _PrologFanOutGate) whether the file count justifies a swarm. execute_swarm_path runs SwarmCoordinator (coordinator), formats the shard results (_format_swarm_artifact) and build_swarm_response builds the reply packet. For the serial path, build_skeleton_prompt (with _read_skeleton_contents) or build_fallback_prompt builds the prompt and append_prompt_extras appends the original spec and monorepo sources. read_file_contents, scan_workspace and _slugify are small utilities.
At a glance
| Source | src/orchestrata_ultimate/agents/volks/codedirector/implementation.py |
| Lines of code | 591 |
| Classes | 1 |
| Functions | 16 |
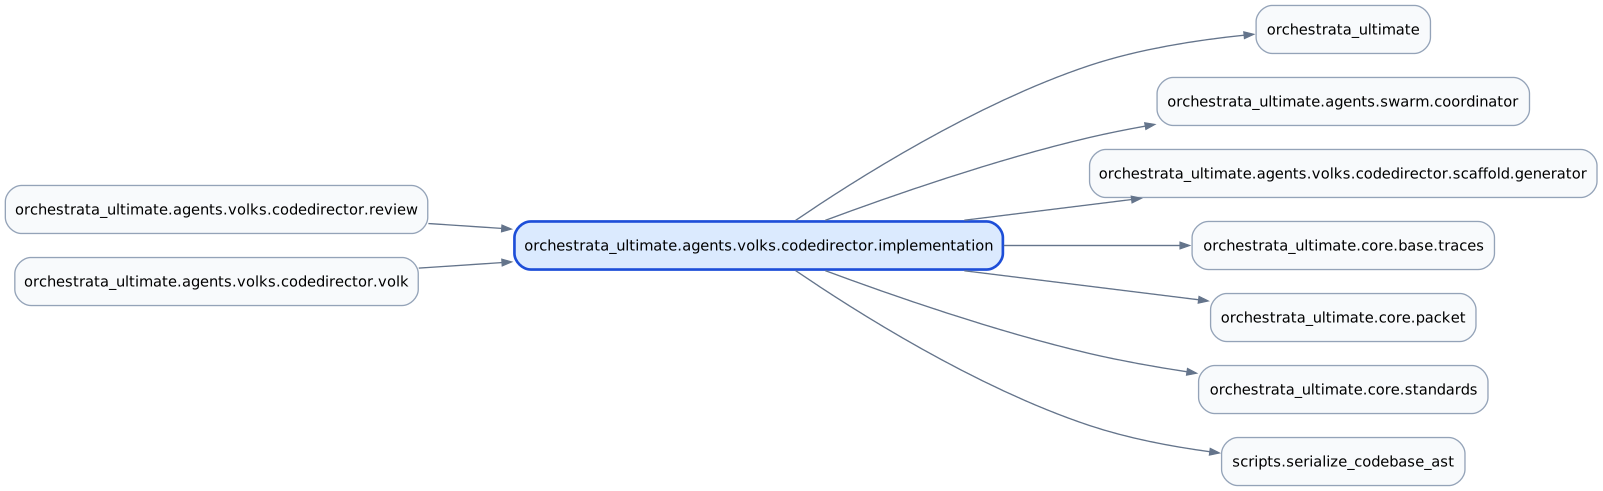
| Imports (internal) | orchestrata_ultimate, orchestrata_ultimate.agents.swarm.coordinator, orchestrata_ultimate.agents.volks.codedirector.scaffold.generator, orchestrata_ultimate.core.base.traces, orchestrata_ultimate.core.packet, orchestrata_ultimate.core.standards, scripts.serialize_codebase_ast |
| Imported by | orchestrata_ultimate.agents.volks.codedirector.review, orchestrata_ultimate.agents.volks.codedirector.volk |
| Tests that import it | tests/agents/volks/codedirector/test_implementation.py, tests/agents/volks/codedirector/test_volk.py, tests/agents/volks/codedirector/test_volk_extended.py, tests/generated_agents/test_volks_codedirector_implementation_generated.py, tests/generated_recovery/test_agents_volks_codedirector_implementation.py |
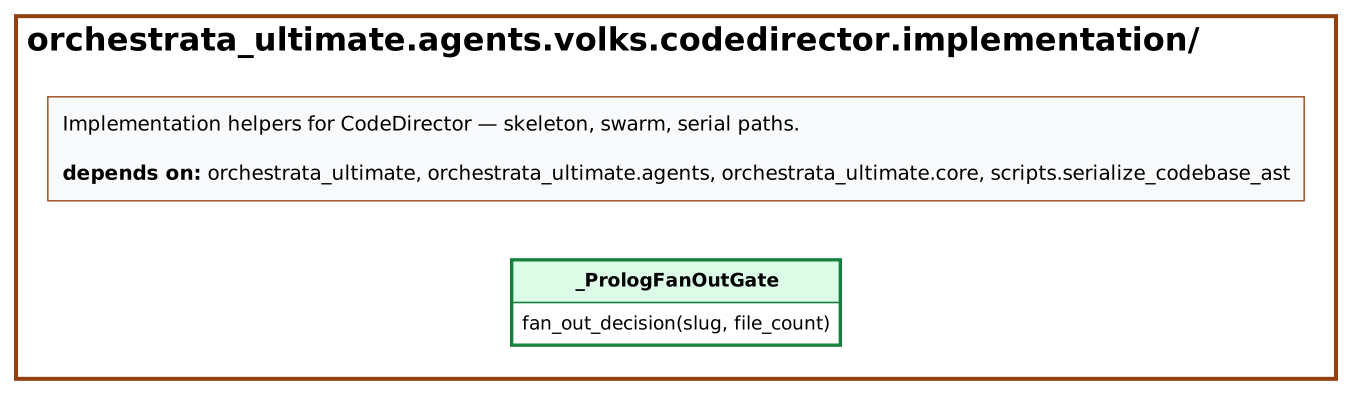
Class diagram
Dependency diagram
API
Classes
_PrologFanOutGate (protocol)
Bases: Protocol · Line 236
Structural shape required of a Prolog engine for fan-out queries.
| Method | Signature | Summary |
|---|---|---|
fan_out_decision |
fan_out_decision(slug: str, file_count: int) -> dict |
Functions
| Function | Signature | Summary |
|---|---|---|
_slugify |
_slugify(text: str) -> str |
Create a filesystem-safe slug from arbitrary text. |
_repo_root |
_repo_root() -> Path |
Return the repository root (the directory containing scripts/). |
_load_gen_skeleton_functions |
_load_gen_skeleton_functions() -> tuple | None |
Import the real gen-skeleton API from scripts/serialize_codebase_ast.py. |
_generate_skeleton_from_contract |
_generate_skeleton_from_contract(workspace: str, class_diagram: str, task_summary: str) -> list[str] |
Generate skeleton files from a Mermaid classDiagram contract. |
extract_design_docs traces |
extract_design_docs(packet: CXPPacket) -> dict[str, str] |
Extract design documents from an implement packet payload. |
generate_skeleton_files traces |
generate_skeleton_files(workspace: str, design_docs: dict[str, str], task_summary: str, env: Mapping[str, str] | None = None) -> list[str] |
Generate deterministic skeleton from design docs. |
get_fan_out_decision traces |
get_fan_out_decision(source_files: list, prolog: object, task_summary: str) -> dict |
Query Prolog governance for swarm fan-out decision. |
execute_swarm_path traces |
async execute_swarm_path(workspace: str, task_summary: str, api_spec: str, original_intent: str, skeleton_files: list[str], source_files: list[str]) -> tuple[list[str], str] |
Execute parallel swarm coding path. |
_format_swarm_artifact traces |
_format_swarm_artifact(shard_results: list) -> str |
Format swarm results into an artifact string. |
build_swarm_response |
build_swarm_response(packet: CXPPacket, files_created: list[str], task_summary: str, project_dir: str, shard_results_count: int, succeeded_count: int) -> CXPPacket |
Build response packet after swarm execution. |
build_skeleton_prompt traces |
build_skeleton_prompt(skeleton_files: list[str], workspace: str, task_summary: str) -> str |
Build aider prompt from skeleton files. |
_read_skeleton_contents traces |
_read_skeleton_contents(skeleton_files: list[str], workspace: str) -> list[str] |
Read Python source skeleton files into formatted blocks. |
build_fallback_prompt traces |
build_fallback_prompt(workspace: str, task_summary: str, requirements: str, architecture: str, file_tree: str, api_spec: str, class_diagram: str) -> str |
Build aider prompt without skeleton (full generation). |
append_prompt_extras traces |
append_prompt_extras(aider_prompt: str, original_intent: str, monorepo_src_section: str) -> str |
Append original spec, monorepo sources, and standards. |
read_file_contents traces |
read_file_contents(workspace: str, files: list) -> str |
Read file contents from workspace into a source listing. |
scan_workspace traces |
scan_workspace(workspace: str) -> list[str] |
Scan workspace for created files. |
Source
# mypy: ignore-errors
"""Implementation helpers for CodeDirector — skeleton, swarm, serial paths."""

import json
import logging
import os
import re
import sys
from collections.abc import Mapping
from pathlib import Path
from typing import Protocol, cast

from orchestrata_ultimate.agents.swarm.coordinator import SwarmCoordinator
from orchestrata_ultimate.agents.volks.codedirector.scaffold.generator import (
    generate_skeleton as generate_scaffold,
)
from orchestrata_ultimate.core.base.traces import traces
from orchestrata_ultimate.core.packet import CXPPacket, WorkStatus
from orchestrata_ultimate.core.standards import CODING_STANDARDS

_logger = logging.getLogger(__name__)


def _slugify(text: str) -> str:
    """Create a filesystem-safe slug from arbitrary text.

    Args:
        text: Input text (typically a task summary).

    Returns:
        Lower-case slug with non-alphanumerics collapsed to underscores.
    """
    slug = re.sub(r"[^\w\s-]", "", text).strip().lower()
    slug = re.sub(r"[-\s]+", "_", slug)
    return slug or "module"


def _repo_root() -> Path:
    """Return the repository root (the directory containing ``scripts/``)."""
    import orchestrata_ultimate

    return Path(orchestrata_ultimate.__file__).resolve().parent.parent.parent


def _load_gen_skeleton_functions() -> tuple | None:
    """Import the real gen-skeleton API from ``scripts/serialize_codebase_ast.py``.

    The script lives outside the package, so the repo root is temporarily
    added to ``sys.path`` for the import.  Returns ``None`` if the import
    fails (e.g., the script is missing), which triggers the scaffold fallback.

    Returns:
        ``(generate_skeleton_modules, gate0_construction_smoke)`` or ``None``.
    """
    try:
        repo_root = _repo_root()
    except Exception as exc:  # pragma: no cover - defensive
        _logger.warning("SKELETON_FLOW: cannot locate repo root: %s", exc)
        return None

    scripts_path = str(repo_root)
    if scripts_path not in sys.path:
        sys.path.insert(0, scripts_path)
    try:
        from scripts.serialize_codebase_ast import (
            gate0_construction_smoke,
            generate_skeleton_modules,
        )

        return generate_skeleton_modules, gate0_construction_smoke
    except Exception as exc:  # pragma: no cover - defensive
        _logger.warning("SKELETON_FLOW: cannot import gen-skeleton API: %s", exc)
        return None


def _generate_skeleton_from_contract(
    workspace: str,
    class_diagram: str,
    task_summary: str,
) -> list[str]:
    """Generate skeleton files from a Mermaid classDiagram contract.

    Uses the real build-factory generator, writes one file per namespace
    (or a single default module), keeps the companion ``.leafmap.json`` next
    to each generated file, and runs Gate 0 construction smoke.  Any failure
    returns an empty list so the caller falls back to the scaffold generator.

    Args:
        workspace: Project workspace directory.
        class_diagram: Mermaid classDiagram source.
        task_summary: Short task description.

    Returns:
        List of generated ``.py`` file paths, or ``[]`` on failure.
    """
    loaded = _load_gen_skeleton_functions()
    if loaded is None:
        return []
    generate_skeleton_modules, gate0_construction_smoke = loaded

    try:
        modules = generate_skeleton_modules(class_diagram)
    except Exception as exc:
        _logger.warning("SKELETON_FLOW: contract parse failed: %s", exc)
        return []

    if not modules:
        return []

    created: list[str] = []
    workspace_path = Path(workspace)
    base_slug = _slugify(task_summary)

    for namespace, (code, _trace_map, leafmap) in modules.items():
        if namespace:
            rel_path = namespace.replace(".", "/") + ".py"
        else:
            rel_path = f"{base_slug}.py"

        dest_path = workspace_path / rel_path
        dest_path.parent.mkdir(parents=True, exist_ok=True)
        dest_path.write_text(code, encoding="utf-8")

        leafmap_path = Path(str(dest_path) + ".leafmap.json")
        leafmap_path.write_text(
            json.dumps(leafmap, indent=2) + "\n",
            encoding="utf-8",
        )

        failures, _skip_warnings = gate0_construction_smoke(code, str(dest_path))
        if failures:
            _logger.warning(
                "SKELETON_FLOW: Gate 0 failed for %s: %s",
                rel_path,
                "; ".join(failures),
            )
            # Remove failed artifacts AND every module already written in
            # this loop — a multi-namespace contract failing Gate 0 on
            # module k>1 previously left modules 1..k-1 orphaned in the
            # workspace next to the scaffold fallback's own output (review
            # finding, 2026-07-14).
            try:
                dest_path.unlink(missing_ok=True)
                leafmap_path.unlink(missing_ok=True)
                for earlier in created:
                    Path(earlier).unlink(missing_ok=True)
                    Path(earlier + ".leafmap.json").unlink(missing_ok=True)
            except OSError:
                pass
            return []

        created.append(str(dest_path))

    print(
        f"  [U:Cd] SKELETON_FLOW: generated {len(created)} file(s) from contract",
        flush=True,
    )
    return created


@traces(
    spec="029",
    story="Design Doc Extraction",
    reqs=["REQ-029-013", "REQ-029-014", "REQ-029-015"],
)
def extract_design_docs(packet: CXPPacket) -> dict[str, str]:
    """Extract design documents from an implement packet payload.

    Args:
        packet: CXP packet with architecture payload.

    Returns:
        Dict with file_tree, api_spec, requirements, architecture,
        class_diagram keys.
    """
    payload = packet.payload
    return {
        "file_tree": payload.get("file_tree", ""),
        "api_spec": payload.get("api_spec", ""),
        "requirements": payload.get("requirements", ""),
        "architecture": payload.get("architecture", ""),
        "class_diagram": payload.get("class_diagram", ""),
    }


@traces(
    spec="029",
    story="Skeleton Generation",
    reqs=["REQ-029-016", "REQ-029-017"],
)
def generate_skeleton_files(
    workspace: str,
    design_docs: dict[str, str],
    task_summary: str,
    env: Mapping[str, str] | None = None,
) -> list[str]:
    """Generate deterministic skeleton from design docs.

    Args:
        workspace: Project workspace directory.
        design_docs: Dict with file_tree, api_spec, etc.
        task_summary: Short description of the task.
        env: Optional environment mapping (defaults to ``os.environ``).

    Returns:
        List of generated skeleton file paths.
    """
    effective_env = env if env is not None else os.environ
    file_tree = design_docs.get("file_tree", "")
    api_spec = design_docs.get("api_spec", "")
    if not (file_tree and api_spec):
        print(
            "  [U:Cd] No design docs — skipping skeleton",
            flush=True,
        )
        return []

    print("  [U:Cd] Generating skeleton from design...", flush=True)

    if effective_env.get("ORCHESTRATA_SKELETON_FLOW", "") == "1":
        class_diagram = design_docs.get("class_diagram", "")
        if class_diagram and "classDiagram" in class_diagram:
            gen_files = _generate_skeleton_from_contract(
                workspace, class_diagram, task_summary
            )
            if gen_files:
                return gen_files
            _logger.warning(
                "SKELETON_FLOW: gen-skeleton failed or produced nothing; "
                "falling back to scaffold generator"
            )

    return generate_scaffold(workspace, design_docs, task_summary)


class _PrologFanOutGate(Protocol):
    """Structural shape required of a Prolog engine for fan-out queries."""

    def fan_out_decision(self, slug: str, file_count: int) -> dict: ...


@traces(
    spec="029",
    story="Fan-Out Decision",
    reqs=["REQ-029-037", "REQ-029-038", "REQ-029-039", "REQ-029-040"],
)
def get_fan_out_decision(
    source_files: list,
    prolog: object,
    task_summary: str,
) -> dict:
    """Query Prolog governance for swarm fan-out decision.

    Falls back to Python heuristic if Prolog unavailable.

    Args:
        source_files: List of source file paths to shard.
        prolog: Prolog engine instance or None.
        task_summary: Task summary for project slug.

    Returns:
        Dict with allowed, strategy, max_shards, reason.
    """
    file_count = len(source_files)
    if prolog and hasattr(prolog, "fan_out_decision"):
        slug = task_summary[:50].replace(" ", "-").lower()
        # cast: hasattr() proved the method exists; `object` is the honest
        # param type since callers pass an untyped `_prolog` attribute.
        return cast(_PrologFanOutGate, prolog).fan_out_decision(slug, file_count)
    return {
        "allowed": file_count >= 2,
        "strategy": "parallel" if file_count >= 2 else "serial",
        "max_shards": min(file_count, 10),
        "reason": "python fallback (no prolog gate)",
    }


@traces(
    spec="029",
    story="Swarm Execution",
    reqs=["REQ-029-042", "REQ-029-043"],
)
async def execute_swarm_path(
    workspace: str,
    task_summary: str,
    api_spec: str,
    original_intent: str,
    skeleton_files: list[str],
    source_files: list[str],
) -> tuple[list[str], str]:
    """Execute parallel swarm coding path.

    Args:
        workspace: Project workspace directory.
        task_summary: Short task description.
        api_spec: API specification text.
        original_intent: Original user intent.
        skeleton_files: All skeleton file paths.
        source_files: Source-only file paths.

    Returns:
        Tuple of (files_created, swarm_artifact_text).
    """
    print(
        f"  [U:Cd] Swarm mode: {len(source_files)} source files",
        flush=True,
    )
    coordinator = SwarmCoordinator(
        workspace=workspace,
        task_summary=task_summary,
        api_spec=api_spec,
        original_intent=original_intent,
    )
    shard_results, all_files = await coordinator.execute_swarm(
        skeleton_files=skeleton_files,
    )
    artifact = _format_swarm_artifact(shard_results)
    return all_files, artifact


@traces(spec="029", reqs=["REQ-029-044"])
def _format_swarm_artifact(shard_results: list) -> str:
    """Format swarm results into an artifact string.

    Args:
        shard_results: List of shard result objects.

    Returns:
        Formatted artifact text.
    """
    succeeded = sum(1 for r in shard_results if r.success)
    failed = [r for r in shard_results if not r.success]
    text = f"=== SWARM RESULTS ===\nShards: {succeeded}/{len(shard_results)} OK\n"
    if failed:
        text += "Failed:\n" + "\n".join(f"  - {r.file_path}: {r.error}" for r in failed)
    return text


def build_swarm_response(
    packet: CXPPacket,
    files_created: list[str],
    task_summary: str,
    project_dir: str,
    shard_results_count: int,
    succeeded_count: int,
) -> CXPPacket:
    """Build response packet after swarm execution.

    Args:
        packet: Original implement packet.
        files_created: List of created file paths.
        task_summary: Short task description.
        project_dir: Project directory path.
        shard_results_count: Total shard count.
        succeeded_count: Successful shard count.

    Returns:
        CXP packet for HUMAN with swarm results.
    """
    return CXPPacket(
        from_agent="U:Cd",
        to_agent="HUMAN",
        thread_id=packet.thread_id,
        subject="implementation_ready",
        payload={
            "files_created": files_created,
            "task_summary": task_summary,
            "project_dir": project_dir,
            "swarm": True,
            "shards_ok": succeeded_count,
            "shards_total": shard_results_count,
        },
        work_status=WorkStatus.IN_PROGRESS,
    )


@traces(
    spec="029",
    story="Skeleton Prompt Construction",
    reqs=["REQ-029-047", "REQ-029-048"],
)
def build_skeleton_prompt(
    skeleton_files: list[str],
    workspace: str,
    task_summary: str,
) -> str:
    """Build aider prompt from skeleton files.

    Args:
        skeleton_files: List of skeleton file paths.
        workspace: Project workspace directory.
        task_summary: Short task description.

    Returns:
        Aider prompt string with skeleton file contents.
    """
    file_contents = _read_skeleton_contents(skeleton_files, workspace)
    has_gen_skeleton_leaves = any(
        "# IMPLEMENT:" in content for content in file_contents
    )

    leaf_rules = ""
    if has_gen_skeleton_leaves:
        leaf_rules = (
            "This skeleton was generated by the build-factory generator. "
            "Fill ONLY the `# IMPLEMENT:` leaves.\n"
            "- Do NOT change signatures, base classes, decorators, or imports.\n"
            "- Do NOT modify any non-leaf code (pattern boilerplate, try/except shells, "
            "wiring, __init__ bodies, etc.).\n"
            "- Output the COMPLETE file for every modified file.\n"
        )

    return (
        f"Task: {task_summary}\n\n"
        "The project skeleton has been generated with correct "
        "file structure, imports, class definitions, and method "
        "signatures. Your job is to IMPLEMENT the method bodies.\n\n"
        "RULES:\n"
        "- Do NOT create new files — only modify the existing ones.\n"
        "- Do NOT change imports, class names, or method signatures.\n"
        "- Replace NotImplementedError with real implementation.\n"
        "- Keep the try/except shells — fill in the try block body.\n"
        "- Output complete files using FILE: path format.\n"
        + leaf_rules
        + "\nSKELETON FILES TO IMPLEMENT:\n\n"
        + "\n\n".join(file_contents)
    )


@traces(spec="029", reqs=["REQ-029-047"])
def _read_skeleton_contents(
    skeleton_files: list[str],
    workspace: str,
) -> list[str]:
    """Read Python source skeleton files into formatted blocks.

    Args:
        skeleton_files: List of skeleton file paths.
        workspace: Project workspace directory.

    Returns:
        List of formatted file content strings.
    """
    file_contents = []
    for fpath in skeleton_files:
        if not fpath.endswith(".py"):
            continue
        if os.path.basename(fpath).startswith("test_"):
            continue
        try:
            with open(fpath) as f:
                content = f.read()
            rel = os.path.relpath(fpath, workspace)
            file_contents.append(f"FILE: {rel}\n```python\n{content}\n```")
        except OSError as exc:
            _logger.debug("read file %s: %s", fpath, exc)
    return file_contents


@traces(
    spec="029",
    story="Fallback Prompt Construction",
    reqs=["REQ-029-049"],
)
def build_fallback_prompt(
    workspace: str,
    task_summary: str,
    requirements: str,
    architecture: str,
    file_tree: str,
    api_spec: str,
    class_diagram: str,
) -> str:
    """Build aider prompt without skeleton (full generation).

    Args:
        workspace: Project workspace directory.
        task_summary: Short task description.
        requirements: Requirements text.
        architecture: Architecture text.
        file_tree: File tree text.
        api_spec: API specification text.
        class_diagram: Class diagram text.

    Returns:
        Aider prompt string for full generation.
    """
    prompt = (
        f"Create the following project in {workspace}:\n"
        f"{task_summary}\n\nRequirements:\n{requirements}"
    )
    if architecture:
        prompt += (
            f"\n\nArchitecture:\n{architecture}\n"
            f"File Tree:\n{file_tree}\n"
            f"API Spec:\n{api_spec}"
        )
        if class_diagram:
            prompt += f"\n\nClass Diagram:\n{class_diagram}"
    return prompt


@traces(
    spec="029",
    story="Prompt Extras",
    reqs=["REQ-029-050", "REQ-029-051", "REQ-029-052"],
)
def append_prompt_extras(
    aider_prompt: str,
    original_intent: str,
    monorepo_src_section: str,
) -> str:
    """Append original spec, monorepo sources, and standards.

    Args:
        aider_prompt: Base prompt to extend.
        original_intent: Original user intent text.
        monorepo_src_section: Monorepo API source text.

    Returns:
        Extended prompt with all extras appended.
    """
    if original_intent:
        aider_prompt += (
            "\n\nORIGINAL SPEC (implement these exact signatures):\n" + original_intent
        )
    if monorepo_src_section:
        aider_prompt += "\n\nCRITICAL — EXISTING API SOURCES:\n" + monorepo_src_section
    aider_prompt += f"\n\n{CODING_STANDARDS}"
    return aider_prompt


@traces(
    spec="029",
    story="File Content Reading",
    reqs=["REQ-029-075"],
)
def read_file_contents(workspace: str, files: list) -> str:
    """Read file contents from workspace into a source listing.

    Args:
        workspace: Project workspace directory.
        files: List of relative file paths.

    Returns:
        Concatenated source listing string.
    """
    listing = ""
    for f in files:
        filepath = os.path.join(workspace, f)
        if not os.path.exists(filepath):
            continue
        try:
            with open(filepath, encoding="utf-8") as fh:
                listing += f"\n=== {f} ===\n{fh.read()}\n"
        except Exception:
            listing += f"\n=== {f} ===\n(could not read)\n"
    return listing


@traces(
    spec="029",
    story="Workspace Scanning",
    reqs=["REQ-029-073", "REQ-029-074"],
)
def scan_workspace(workspace: str) -> list[str]:
    """Scan workspace for created files.

    Args:
        workspace: Project workspace directory.

    Returns:
        Sorted list of relative file paths.
    """
    files: list[str] = []
    if not os.path.exists(workspace):
        return files
    skip_dirs = {"__pycache__"}
    for root, dirs, filenames in os.walk(workspace):
        dirs[:] = [
            d
            for d in dirs
            if not d.startswith(".")
            and d not in skip_dirs
            and not d.startswith("Module:")
        ]
        for f in filenames:
            if not f.startswith("."):
                rel = os.path.relpath(os.path.join(root, f), workspace)
                files.append(rel)
    return sorted(files)