orchestrata_ultimate.memory.token_counter
Reference › orchestrata_ultimate › memory › token_counter
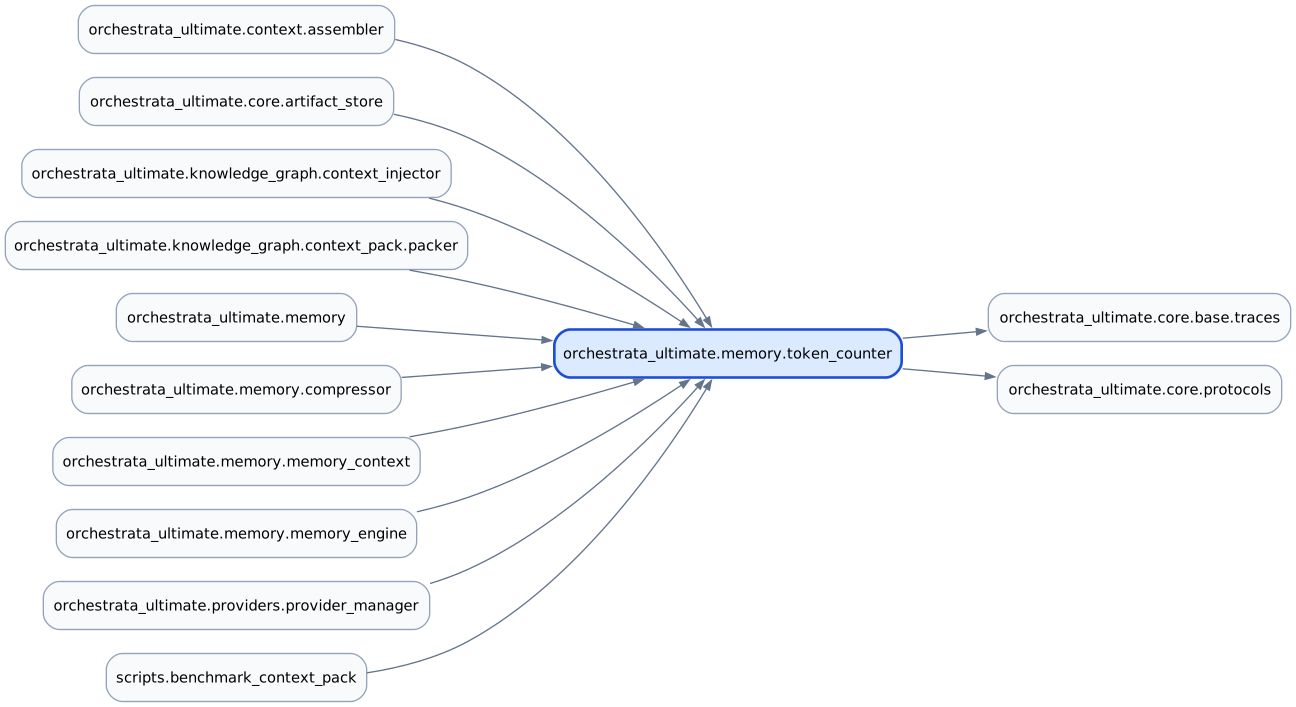
Token counting behind a small protocol, TokenCounterProtocol from core.protocols. The module is shared well beyond memory: the compressor, memory_context, the context assembler, the provider manager, the artifact store and the context-pack packer all import it.
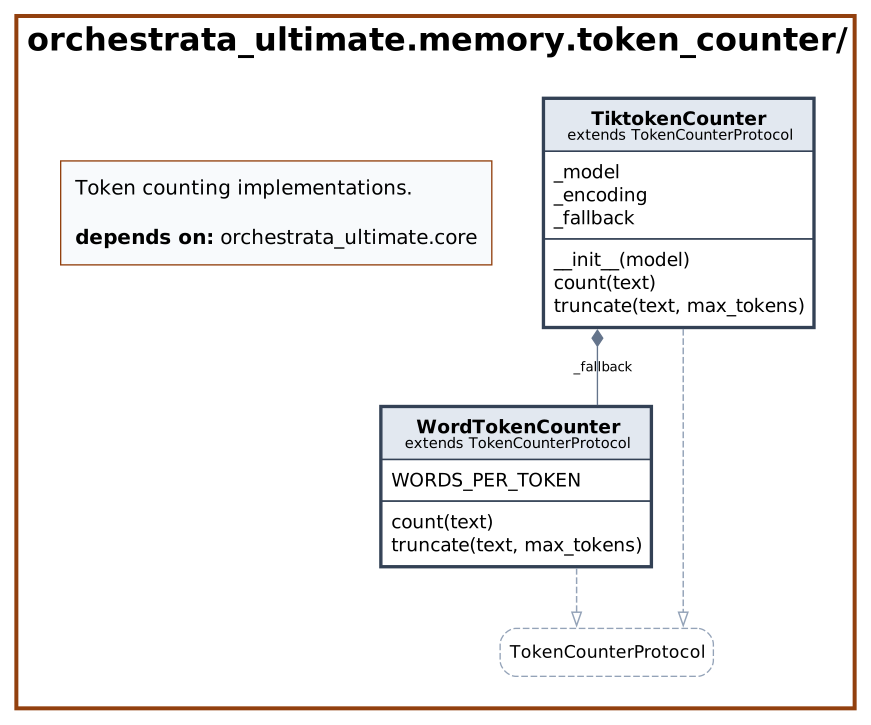
WordTokenCounter approximates one token as 0.75 words: count returns the rounded-up word count divided by 0.75 (at least 1 for non-empty text, 0 for empty), and truncate keeps the first max_tokens * 0.75 words. TiktokenCounter uses the optional tiktoken library for a given model (default gpt-4o): if the library is missing or the model is unknown it falls back to a WordTokenCounter, and truncate cuts on token boundaries. get_token_counter(provider) returns a TiktokenCounter for openai and deepseek and the word counter for any other value, including None.
At a glance
| Source | src/orchestrata_ultimate/memory/token_counter.py |
| Lines of code | 95 |
| Classes | 2 |
| Functions | 1 |
| Imports (internal) | orchestrata_ultimate.core.base.traces, orchestrata_ultimate.core.protocols |
| Imported by | orchestrata_ultimate.context.assembler, orchestrata_ultimate.core.artifact_store, orchestrata_ultimate.knowledge_graph.context_injector, orchestrata_ultimate.knowledge_graph.context_pack.packer, orchestrata_ultimate.memory, orchestrata_ultimate.memory.compressor, orchestrata_ultimate.memory.memory_context, orchestrata_ultimate.memory.memory_engine, orchestrata_ultimate.providers.provider_manager, scripts.benchmark_context_pack |
| Tests that import it | tests/context/providers/test_trimming.py, tests/core/test_protocols.py, tests/generated_recovery/test_memory_token_counter.py, tests/knowledge_graph/context_pack/test_packer.py, tests/knowledge_graph/test_context_pack_performance.py, tests/memory/test_token_counter.py, tests/test_memory.py |
Class diagram
Dependency diagram
API
Classes
WordTokenCounter (protocol)
Bases: TokenCounterProtocol · Decorators: traces(spec='010', story='US-003', reqs=['REQ-010-041']) · Line 15
Fallback token counter using word-based approximation.
| Method | Signature | Summary |
|---|---|---|
count |
count(text: str) -> int |
Count tokens using word-based approximation. |
truncate |
truncate(text: str, max_tokens: int) -> str |
Truncate text to fit within max_tokens. |
TiktokenCounter (protocol)
Bases: TokenCounterProtocol · Decorators: traces(spec='010', story='US-003', reqs=['REQ-010-041']) · Line 42
Token counter using tiktoken (for OpenAI models).
| Method | Signature | Summary |
|---|---|---|
__init__ |
__init__(model: str = 'gpt-4o') |
|
count |
count(text: str) -> int |
Count tokens using tiktoken encoding. |
truncate |
truncate(text: str, max_tokens: int) -> str |
Truncate text to fit within max_tokens. |
Functions
| Function | Signature | Summary |
|---|---|---|
get_token_counter traces |
get_token_counter(provider: str | None = None) -> TokenCounterProtocol |
Get the appropriate token counter for a provider. |
Source
# mypy: ignore-errors
"""Token counting implementations.

SPEC-010 FR-011/FR-012: Provider-aware token counting.
Shared between Memory Engine (SPEC-010) and Provider Manager (SPEC-011).
"""

import math

from orchestrata_ultimate.core.base.traces import traces
from orchestrata_ultimate.core.protocols import TokenCounterProtocol


@traces(spec="010", story="US-003", reqs=["REQ-010-041"])
class WordTokenCounter(TokenCounterProtocol):
    """Fallback token counter using word-based approximation.

    Approximation: 1 token ≈ 0.75 words (empirically validated for English text).
    """

    WORDS_PER_TOKEN = 0.75

    def count(self, text: str) -> int:
        """Count tokens using word-based approximation."""
        if not text:
            return 0
        word_count = len(text.split())
        return max(1, math.ceil(word_count / self.WORDS_PER_TOKEN))

    def truncate(self, text: str, max_tokens: int) -> str:
        """Truncate text to fit within max_tokens."""
        if max_tokens <= 0:
            return ""
        if self.count(text) <= max_tokens:
            return text
        max_words = int(max_tokens * self.WORDS_PER_TOKEN)
        words = text.split()
        return " ".join(words[:max_words])


@traces(spec="010", story="US-003", reqs=["REQ-010-041"])
class TiktokenCounter(TokenCounterProtocol):
    """Token counter using tiktoken (for OpenAI models).

    Falls back to WordTokenCounter if tiktoken is not installed.
    """

    def __init__(self, model: str = "gpt-4o"):
        self._model = model
        self._encoding = None
        self._fallback = WordTokenCounter()
        try:
            # Optional dep (declared under [project.optional-dependencies]
            # "tokenizer"): not installed in every env — falls back to
            # WordTokenCounter below when absent. See pyproject.toml.
            import tiktoken  # pyright: ignore[reportMissingImports]

            self._encoding = tiktoken.encoding_for_model(model)
        except ImportError, KeyError:
            self._encoding = None

    def count(self, text: str) -> int:
        """Count tokens using tiktoken encoding."""
        if not text:
            return 0
        if self._encoding is None:
            return self._fallback.count(text)
        return len(self._encoding.encode(text))

    def truncate(self, text: str, max_tokens: int) -> str:
        """Truncate text to fit within max_tokens."""
        if max_tokens <= 0:
            return ""
        if self._encoding is None:
            return self._fallback.truncate(text, max_tokens)
        tokens = self._encoding.encode(text)
        if len(tokens) <= max_tokens:
            return text
        return self._encoding.decode(tokens[:max_tokens])


@traces(spec="010", story="US-003", reqs=["REQ-010-041"])
def get_token_counter(provider: str | None = None) -> TokenCounterProtocol:
    """Get the appropriate token counter for a provider.

    Args:
        provider: Provider name (e.g., "openai", "anthropic", "deepseek").
                  None returns the word-based fallback.

    Returns:
        TokenCounterProtocol implementation.
    """
    if provider in ("openai", "deepseek"):
        return TiktokenCounter()
    return WordTokenCounter()