scripts.benchmark_context_pack
Reference › scripts › benchmark_context_pack
The performance benchmark for the SPEC-106 context-pack selector and packer. It uses the graph factory from graph_factory and the graph package from core.graph. A human runs it, and tests/scripts/test_benchmark_context_pack.py imports it. See also context_pack, the tool being timed.
Invocation: main takes a subcommand. seed syncs the current repository's AST into the graph (_run_seed), so there is something to select from. run benchmarks analyze_request, selection and packing latency (_run_benchmark). With no arguments it prints usage and returns 1; an unknown subcommand is an error. Both subcommands build their graph driver from the environment (_driver_from_env). Latencies are summarized with _percentile over the sorted timings.
At a glance
| Source | scripts/benchmark_context_pack.py |
| Lines of code | 319 |
| Classes | 0 |
| Functions | 5 |
| Imports (internal) | orchestrata_ultimate.core.graph, orchestrata_ultimate.core.graph_factory, orchestrata_ultimate.knowledge_graph.context_injector, orchestrata_ultimate.knowledge_graph.context_pack, orchestrata_ultimate.memory.token_counter |
| Imported by | none |
| Tests that import it | tests/scripts/test_benchmark_context_pack.py |
Class diagram
No classes; see Functions.
Dependency diagram
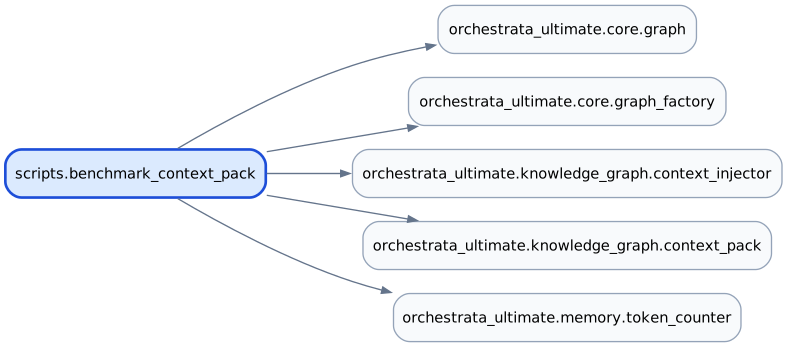
API
Functions
| Function | Signature | Summary |
|---|---|---|
_driver_from_env |
_driver_from_env(env: Mapping[str, str] | None = None) |
Build a graph driver from env vars (no hardcoded defaults). |
_percentile |
_percentile(sorted_times: list[float], p: float) -> float |
Return the p-th percentile of a sorted list of durations (seconds). |
_run_seed |
_run_seed(argv: list[str] | None = None) -> int |
Seed Neo4j from the current repo's AST JSON. |
_run_benchmark |
_run_benchmark(argv: list[str] | None = None, *, env: Mapping[str, str] | None = None) -> int |
Run the selector/packer benchmark and print results. |
main |
main(argv: list[str] | None = None) -> int |
Source
#!/usr/bin/env python3
"""Performance benchmark for SPEC-106 context-pack selector + packer.

Measures end-to-end latency of ``analyze_request`` + ``select`` + ``pack``
against a live graph graph and reports p50/p95/p99. Used to verify
SPEC-106 REQ-106-044 (selection+packing p50 < 500ms at repo scale).

Examples
--------
    # Benchmark against an already-synced project graph
    python scripts/benchmark_context_pack.py run refactor "context/assembler.py" --iterations 20

    # Seed the graph from the current repo first, then benchmark
    python scripts/benchmark_context_pack.py seed
    python scripts/benchmark_context_pack.py run refactor "context/assembler.py" --iterations 50

    # JSON output for CI dashboards
    python scripts/benchmark_context_pack.py run test "context/assembler.py" --iterations 20 --json
"""

from __future__ import annotations

import argparse
import json
import statistics
import sys
import time
from collections.abc import Mapping
from pathlib import Path
from typing import Any

_repo_src = Path(__file__).resolve().parent.parent / "src"
if str(_repo_src) not in sys.path:
    sys.path.insert(0, str(_repo_src))


from orchestrata_ultimate.core.graph import BoltSyncRepository  # noqa: E402
from orchestrata_ultimate.core.graph_factory import (  # noqa: E402
    NO_AUTH,
    create_graph,
    resolve_uri,
)
from orchestrata_ultimate.knowledge_graph.context_injector import TaskType  # noqa: E402
from orchestrata_ultimate.knowledge_graph.context_pack import (  # noqa: E402
    analyze_request,
    pack,
    render,
    select,
)
from orchestrata_ultimate.memory.token_counter import get_token_counter  # noqa: E402

DEFAULT_PROJECT = "orchestrata-ultimate"
DEFAULT_BUDGET = 4000
DEFAULT_ITERATIONS = 20


def _driver_from_env(env: Mapping[str, str] | None = None):
    """Build a graph driver from env vars (no hardcoded defaults).

    The docstring's promise is now true. This read NEO4J_URI/USERNAME/PASSWORD
    with three inline defaults (`bolt://localhost:7687`, `neo4j`, ``) — those
    keys were retired with the Neo4j containers on 2026-07-27, and nothing has
    ever listened on localhost, so the fallback could only ever produce a
    connection-refused that reads like an outage. resolve_uri() raises and
    names the missing key instead.
    """
    return create_graph(uri=resolve_uri(env=env), auth=NO_AUTH)


def _percentile(sorted_times: list[float], p: float) -> float:
    """Return the p-th percentile of a sorted list of durations (seconds)."""
    if not sorted_times:
        return 0.0
    idx = int(len(sorted_times) * p / 100)
    idx = min(idx, len(sorted_times) - 1)
    return sorted_times[idx]


def _run_seed(argv: list[str] | None = None) -> int:
    """Seed Neo4j from the current repo's AST JSON."""
    parser = argparse.ArgumentParser(
        prog="benchmark_context_pack seed",
        description="Sync the current repo into the graph for benchmarking.",
    )
    parser.add_argument(
        "--ast",
        default="plans/ast-ultimate.json",
        help="Path to the serialized AST JSON.",
    )
    parser.add_argument(
        "--project",
        default=DEFAULT_PROJECT,
        help="Project id to sync under.",
    )
    args = parser.parse_args(argv)

    ast_path = Path(args.ast)
    if not ast_path.exists():
        print(f"ERROR: AST file not found: {ast_path}", file=sys.stderr)
        print("Run: uv run ast-sync", file=sys.stderr)
        return 1

    import importlib.util

    sync_path = (
        Path(__file__).resolve().parent.parent
        / "src"
        / "orchestrata_ultimate"
        / "knowledge_graph"
        / "sync.py"
    )
    spec = importlib.util.spec_from_file_location(
        "orchestrata_ultimate.knowledge_graph.sync", sync_path
    )
    if spec is None or spec.loader is None:
        print(f"ERROR: Cannot load sync module from {sync_path}", file=sys.stderr)
        return 1
    mod = importlib.util.module_from_spec(spec)
    spec.loader.exec_module(mod)
    GraphSyncer = mod.GraphSyncer

    with ast_path.open(encoding="utf-8") as fh:
        ast_data = json.load(fh)

    driver = _driver_from_env()
    syncer = GraphSyncer(uri=resolve_uri(), username="", password="")
    syncer.connect()
    try:
        syncer.full_sync(ast_data, args.project)
        print(f"Seeded project '{args.project}' into the graph.")
        return 0
    finally:
        syncer.close()
        driver.close()


def _run_benchmark(
    argv: list[str] | None = None,
    *,
    env: Mapping[str, str] | None = None,
) -> int:
    """Run the selector/packer benchmark and print results.

    Args:
        argv: CLI args for the ``run`` subcommand.
        env: Environment seam forwarded to :func:`_driver_from_env` (tests
            point the driver at a dead address without mutating process env).
    """
    parser = argparse.ArgumentParser(
        prog="benchmark_context_pack run",
        description="Benchmark context_pack analyze_request + select + pack latency.",
    )
    parser.add_argument(
        "task_type",
        choices=[t.value for t in TaskType],
        help="Task type driving the selection template.",
    )
    parser.add_argument(
        "target",
        help="Free-text target (module, class, or description) for entity linking.",
    )
    parser.add_argument(
        "--iterations",
        type=int,
        default=DEFAULT_ITERATIONS,
        help="Number of benchmark iterations.",
    )
    parser.add_argument(
        "--budget",
        type=int,
        default=DEFAULT_BUDGET,
        help="Token budget passed to the packer.",
    )
    parser.add_argument(
        "--project",
        default=DEFAULT_PROJECT,
        help="Project id used for project-scoped lookups.",
    )
    parser.add_argument(
        "--json",
        action="store_true",
        help="Emit machine-readable JSON instead of human text.",
    )
    parser.add_argument(
        "--max-p50-ms",
        type=float,
        default=500.0,
        help="Fail if p50 latency exceeds this many milliseconds.",
    )
    args = parser.parse_args(argv)

    if args.iterations < 1:
        # times[] would be empty: statistics.mean([]) raises and times[0]
        # IndexErrors — an unhandled crash on a legal-parse input.
        parser.error("--iterations must be >= 1")

    driver = _driver_from_env(env)
    try:
        driver.verify_connectivity()
    except Exception as exc:
        print(f"ERROR: Cannot connect to the graph: {exc}", file=sys.stderr)
        return 1

    repo = BoltSyncRepository(driver=driver)
    task_type = TaskType(args.task_type)
    counter = get_token_counter()

    # Warm-up iteration: prime caches and connection pools.
    try:
        frame = analyze_request(
            args.target,
            repo=repo,
            task_type=task_type,
            budget=args.budget,
            requester="benchmark",
        )
        subgraph = select(frame, repo)
        context_pack = pack(subgraph, frame, counter=counter)
        _ = render(context_pack)
    except Exception as exc:
        print(f"ERROR: Warm-up failed: {exc}", file=sys.stderr)
        return 1

    times: list[float] = []
    node_counts: list[int] = []
    section_counts: list[int] = []
    spent_tokens: list[int] = []

    for i in range(args.iterations):
        start = time.perf_counter()
        frame = analyze_request(
            args.target,
            repo=repo,
            task_type=task_type,
            budget=args.budget,
            requester="benchmark",
        )
        subgraph = select(frame, repo)
        context_pack = pack(subgraph, frame, counter=counter)
        _ = render(context_pack)
        elapsed = time.perf_counter() - start
        times.append(elapsed)
        node_counts.append(len(subgraph.nodes))
        section_counts.append(len(context_pack.sections))
        spent_tokens.append(context_pack.spent)

    driver.close()

    times.sort()
    p50 = _percentile(times, 50)
    p95 = _percentile(times, 95)
    p99 = _percentile(times, 99)

    result: dict[str, Any] = {
        "operation": "context_pack_analyze_select_pack",
        "task_type": args.task_type,
        "target": args.target,
        "project": args.project,
        "iterations": args.iterations,
        "budget": args.budget,
        "mean_ms": statistics.mean(times) * 1000,
        "min_ms": times[0] * 1000,
        "max_ms": times[-1] * 1000,
        "p50_ms": p50 * 1000,
        "p95_ms": p95 * 1000,
        "p99_ms": p99 * 1000,
        "nodes_selected_mean": statistics.mean(node_counts),
        "sections_packed_mean": statistics.mean(section_counts),
        "spent_tokens_mean": statistics.mean(spent_tokens),
        "p50_under_budget_ms": args.max_p50_ms,
        "p50_passed": p50 * 1000 <= args.max_p50_ms,
    }

    if args.json:
        print(json.dumps(result, indent=2))
    else:
        print("Benchmark: context_pack analyze+select+pack")
        print(f"  Task: {args.task_type} / Target: {args.target}")
        print(f"  Iterations: {args.iterations}")
        print(f"  Mean:  {result['mean_ms']:.2f}ms")
        print(f"  Min:   {result['min_ms']:.2f}ms")
        print(f"  Max:   {result['max_ms']:.2f}ms")
        print(f"  p50:   {result['p50_ms']:.2f}ms")
        print(f"  p95:   {result['p95_ms']:.2f}ms")
        print(f"  p99:   {result['p99_ms']:.2f}ms")
        print(f"  Nodes selected (mean): {result['nodes_selected_mean']:.1f}")
        print(f"  Sections packed (mean): {result['sections_packed_mean']:.1f}")
        print(f"  Spent tokens (mean): {result['spent_tokens_mean']:.1f}")
        status = "PASS" if result["p50_passed"] else "FAIL"
        print(f"  p50 budget {args.max_p50_ms}ms: {status}")

    return 0 if result["p50_passed"] else 2


def main(argv: list[str] | None = None) -> int:
    if argv is None:
        argv = sys.argv[1:]
    if not argv or argv[0] in ("-h", "--help"):
        print(
            "usage: benchmark_context_pack {seed|run} ...\n\n"
            "  seed  Sync the current repo AST into the graph.\n"
            "  run   Benchmark context_pack analyze_request + select + pack latency.\n\n"
            "Run 'benchmark_context_pack seed --help' or "
            "'benchmark_context_pack run --help' for details.",
            file=sys.stderr,
        )
        return 1 if not argv else 0
    command = argv[0]
    rest = argv[1:]
    if command == "seed":
        return _run_seed(rest)
    if command == "run":
        return _run_benchmark(rest)
    print(f"ERROR: Unknown command: {command}", file=sys.stderr)
    return 1


if __name__ == "__main__":
    sys.exit(main())