orchestrata_ultimate.memory.compressor
Reference › orchestrata_ultimate › memory › compressor
ContextCompressor squeezes a set of memory entries into a token budget by extraction, not by generation, so what is folded back into an agent prompt stays within the context window. The MemoryEngine calls it from summarize. It takes any token counter from token_counter and defaults to the word-based one.
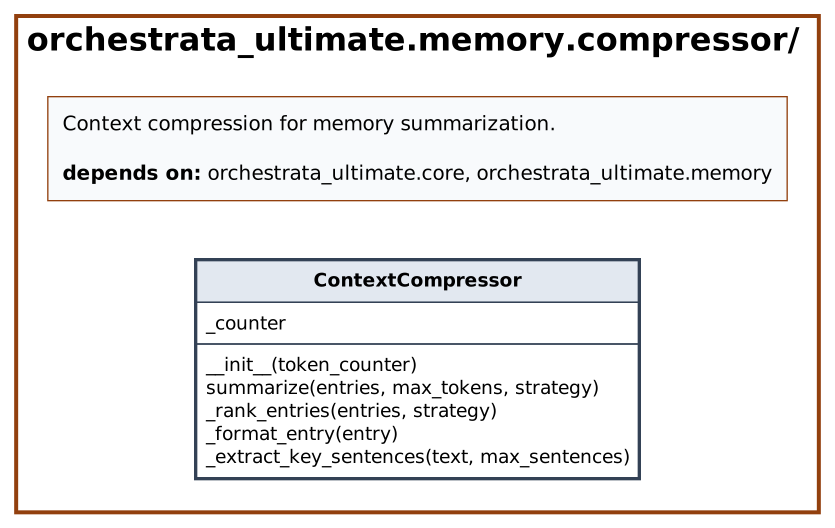
summarize(entries, max_tokens, strategy) returns a MemorySummary with the joined content, token count, number of sources, their keys and the strategy. An empty input gives an empty summary. _rank_entries orders entries by strategy: RECENCY by creation time, IMPORTANCE by the importance metadata value, and otherwise by relevance score and then time. Entries are formatted by _format_entry as their tags in brackets followed by the content, and added in rank order until the budget is reached. The entry that crosses the budget is truncated to the remaining tokens only if more than 20 remain, and the loop then stops. _extract_key_sentences picks the longest sentences, doubling the score of sentences containing words such as decision or result; summarize does not call it.
At a glance
| Source | src/orchestrata_ultimate/memory/compressor.py |
| Lines of code | 138 |
| Classes | 1 |
| Functions | 0 |
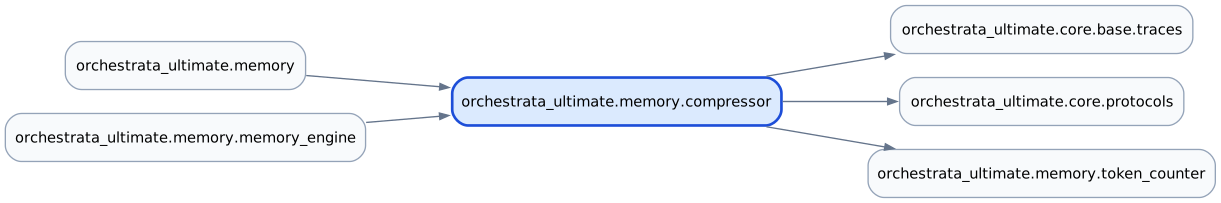
| Imports (internal) | orchestrata_ultimate.core.base.traces, orchestrata_ultimate.core.protocols, orchestrata_ultimate.memory.token_counter |
| Imported by | orchestrata_ultimate.memory, orchestrata_ultimate.memory.memory_engine |
| Tests that import it | tests/memory/test_compressor.py, tests/memory/test_compressor_extended.py, tests/test_memory.py |
Class diagram
Dependency diagram
API
Classes
ContextCompressor
Decorators: traces(spec='010', story='US-005', reqs=['REQ-010-021', 'REQ-010-022', 'REQ-010-023']) · Line 21
Extractive context compression for memory summarization.
| Method | Signature | Summary |
|---|---|---|
__init__ |
__init__(token_counter: TokenCounterProtocol | None = None) |
|
summarize |
summarize(entries: list[MemoryEntry], max_tokens: int = 2048, strategy: SummarizationStrategy = SummarizationStrategy.RELEVANCE) -> MemorySummary |
Compress entries into a token-bounded summary. |
_rank_entries |
_rank_entries(entries: list[MemoryEntry], strategy: SummarizationStrategy) -> list[MemoryEntry] |
Rank entries by the given strategy. |
_format_entry |
_format_entry(entry: MemoryEntry) -> str |
Format a single entry for inclusion in the summary. |
_extract_key_sentences |
_extract_key_sentences(text: str, max_sentences: int = 3) -> str |
Extract the most informative sentences from text. |
Source
"""Context compression for memory summarization.

SPEC-010 FR-005/FR-012: Token-aware extractive summarization.
P1 uses extractive summarization (key sentence extraction + truncation).
LLM-based summarization deferred to P2.
"""

import re

from orchestrata_ultimate.core.base.traces import traces
from orchestrata_ultimate.core.protocols import (
    MemoryEntry,
    MemorySummary,
    SummarizationStrategy,
    TokenCounterProtocol,
)
from orchestrata_ultimate.memory.token_counter import WordTokenCounter


@traces(spec="010", story="US-005", reqs=["REQ-010-021", "REQ-010-022", "REQ-010-023"])
class ContextCompressor:
    """Extractive context compression for memory summarization.

    Selects and truncates memories to fit within a token budget,
    preserving key information based on the chosen strategy.
    """

    @traces(spec="010", story="US-010-001", reqs=["REQ-010-037"])
    @traces(spec="017", story="US-010-001", reqs=["REQ-017-041"])
    def __init__(self, token_counter: TokenCounterProtocol | None = None):
        self._counter = token_counter or WordTokenCounter()

    @traces(spec="010", story="US-010-001", reqs=["REQ-010-038"])
    @traces(spec="017", story="US-010-001", reqs=["REQ-017-042"])
    def summarize(
        self,
        entries: list[MemoryEntry],
        max_tokens: int = 2048,
        strategy: SummarizationStrategy = SummarizationStrategy.RELEVANCE,
    ) -> MemorySummary:
        """Compress entries into a token-bounded summary.

        Args:
            entries: Memory entries to summarize.
            max_tokens: Maximum tokens for the summary.
            strategy: Ranking strategy for entry selection.

        Returns:
            MemorySummary with compressed content and source references.
        """
        if not entries:
            return MemorySummary(
                content="",
                token_count=0,
                source_count=0,
                strategy=strategy,
            )

        ranked = self._rank_entries(entries, strategy)
        selected_content: list[str] = []
        selected_keys: list[str] = []
        tokens_used = 0

        for entry in ranked:
            entry_text = self._format_entry(entry)
            entry_tokens = self._counter.count(entry_text)
            if tokens_used + entry_tokens > max_tokens:
                remaining = max_tokens - tokens_used
                if remaining > 20:
                    truncated = self._counter.truncate(entry_text, remaining)
                    selected_content.append(truncated)
                    selected_keys.append(entry.key)
                    tokens_used += self._counter.count(truncated)
                break
            selected_content.append(entry_text)
            selected_keys.append(entry.key)
            tokens_used += entry_tokens

        content = "\n\n".join(selected_content)
        return MemorySummary(
            content=content,
            token_count=tokens_used,
            source_count=len(selected_keys),
            source_keys=selected_keys,
            strategy=strategy,
        )

    @traces(spec="010", story="US-010-001", reqs=["REQ-010-039"])
    @traces(spec="017", story="US-010-001", reqs=["REQ-017-043"])
    def _rank_entries(
        self, entries: list[MemoryEntry], strategy: SummarizationStrategy
    ) -> list[MemoryEntry]:
        """Rank entries by the given strategy."""
        if strategy == SummarizationStrategy.RECENCY:
            return sorted(entries, key=lambda e: e.created_at, reverse=True)
        elif strategy == SummarizationStrategy.IMPORTANCE:
            return sorted(
                entries,
                key=lambda e: e.metadata.get("importance", 0),
                reverse=True,
            )
        else:
            return sorted(
                entries,
                key=lambda e: (e.relevance_score or 0.0, e.created_at.timestamp()),
                reverse=True,
            )

    @traces(spec="010", story="US-010-001", reqs=["REQ-010-040"])
    @traces(spec="017", story="US-010-001", reqs=["REQ-017-044"])
    def _format_entry(self, entry: MemoryEntry) -> str:
        """Format a single entry for inclusion in the summary."""
        parts = []
        if entry.tags:
            parts.append(f"[{', '.join(entry.tags)}]")
        parts.append(entry.content)
        return " ".join(parts)

    @traces(spec="010", story="US-010-001", reqs=["REQ-010-041"])
    @traces(spec="017", story="US-010-001", reqs=["REQ-017-045"])
    def _extract_key_sentences(self, text: str, max_sentences: int = 3) -> str:
        """Extract the most informative sentences from text."""
        sentences = re.split(r"(?<=[.!?])\s+", text)
        if len(sentences) <= max_sentences:
            return text
        scored = []
        for s in sentences:
            words = s.split()
            score = len(words)
            if any(
                w in s.lower()
                for w in ["decision", "conclusion", "result", "important"]
            ):
                score *= 2
            scored.append((score, s))
        scored.sort(reverse=True)
        selected = [s for _, s in scored[:max_sentences]]
        return " ".join(selected)