orchestrata_ultimate.kernel.pipeline_cli
Reference › orchestrata_ultimate › kernel › pipeline_cli
The interactive REPL for the pipeline, a human-facing way to push an intent through the volks by hand. It imports the PipelineRunner and the knowledge-graph query engine, and no other module imports it. It is the same intent path that cli_main and the gateway use, driven from a prompt.
main prints a banner, builds and boots a PipelineRunner unless one is passed in, prints print_help, and loops on an orchestrata> prompt. End of input or Ctrl-C shuts the runner down with a reason. _dispatch_command maps the first word to a handler and returns the active thread id and a quit flag:
intent(_cmd_intent) callssubmit_intent, makes the returned thread the active one and prints the last human-bound reply with_print_human_response, which handles clarification and QA-complete replies.respond(_cmd_respond, with_parse_respond_args) callsrespondon a given or active thread.status,reviewandapprovecall the runner's status, volk review and approval methods;approveruns the Prolog completion gate described on pipeline_escalation.packetslists the packets on a thread, andlogprints the session log.provenanceopens a graph client and calls the query engine'srun_provenanceto print the intent, the volks that executed and the artifacts of a run. It is read-only and prints a message when the graph is unavailable instead of crashing the REPL.quitorexitshuts the runner down; an unknown word prints a hint to typehelp.
At a glance
| Source | src/orchestrata_ultimate/kernel/pipeline_cli.py |
| Lines of code | 311 |
| Classes | 0 |
| Functions | 14 |
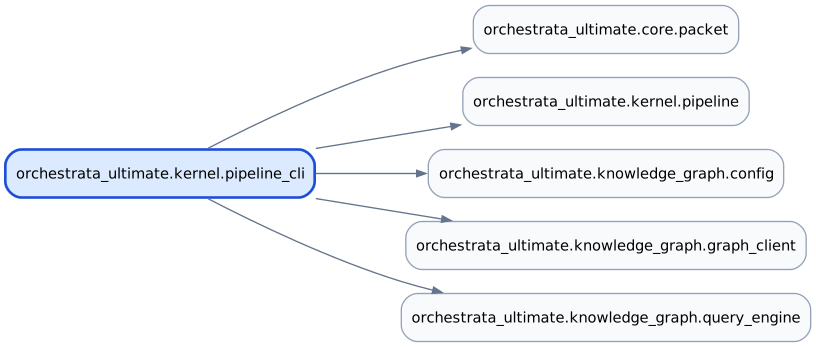
| Imports (internal) | orchestrata_ultimate.core.packet, orchestrata_ultimate.kernel.pipeline, orchestrata_ultimate.knowledge_graph.config, orchestrata_ultimate.knowledge_graph.graph_client, orchestrata_ultimate.knowledge_graph.query_engine |
| Imported by | none |
| Tests that import it | tests/kernel/test_pipeline_cli.py, tests/kernel/test_pipeline_cli_expanded.py, tests/kernel/test_pipeline_cli_more.py, tests/knowledge_graph/test_artifact_provenance_sync.py |
Class diagram
No classes; see Functions.
Dependency diagram
API
Functions
| Function | Signature | Summary |
|---|---|---|
print_help |
print_help() -> None |
|
_print_human_response |
_print_human_response(msg: CXPPacket | None, *, include_clarification: bool = False, verbose_qa: bool = False) -> None |
Print a volk's human-facing response message. |
_print_qa_complete |
_print_qa_complete(msg: CXPPacket, *, verbose: bool = False) -> None |
Print a qa_complete message, optionally with test details. |
_cmd_intent |
_cmd_intent(kernel: PipelineRunner, args: str, active_thread: str | None) -> str | None |
Handle the intent command. |
_parse_respond_args |
_parse_respond_args(args: str, active_thread: str | None) -> tuple[str | None, str | None] |
Parse respond [thread_id] "<text>" args. |
_cmd_respond |
_cmd_respond(kernel: PipelineRunner, args: str, active_thread: str | None) -> None |
Handle the respond command. |
_cmd_status |
_cmd_status(kernel: PipelineRunner, active_thread: str | None) -> None |
Handle the status command. |
_cmd_review |
_cmd_review(kernel: PipelineRunner, args: str) -> None |
Handle the review command. |
_cmd_approve |
_cmd_approve(kernel: PipelineRunner, args: str, active_thread: str | None) -> None |
Handle the approve command. |
_cmd_packets |
_cmd_packets(kernel: PipelineRunner, args: str, active_thread: str | None) -> None |
Handle the packets command. |
_cmd_provenance |
_cmd_provenance(args: str, active_thread: str | None) -> None |
Handle the provenance command — show a run's semantic provenance. |
_cmd_log |
_cmd_log(kernel: PipelineRunner) -> None |
Handle the log command. |
_dispatch_command |
_dispatch_command(kernel: PipelineRunner, cmd: str, args: str, active_thread: str | None) -> tuple[str | None, bool] |
Dispatch a single REPL command. |
main |
main(kernel: PipelineRunner | None = None) -> None |
Source
# mypy: ignore-errors
"""Orchestrata Pipeline — REPL-based CLI.

Production version using PipelineRunner from orchestrata_ultimate.kernel.pipeline.
"""

import re
from typing import TYPE_CHECKING

from orchestrata_ultimate.kernel.pipeline import PipelineRunner

if TYPE_CHECKING:
    from orchestrata_ultimate.core.packet import CXPPacket


def print_help() -> None:
    print("""
Orchestrata Spike CLI — Commands:
  intent "<text>"              Submit an intent to the system
  respond <thread_id> "<text>" Respond to a volk's questions
  status                       Show all volk statuses
  review <volk>                Review a volk's output (e.g., review U:Cd)
  approve <thread_id>          Approve work on a thread
  packets <thread_id>          Show CXP packet flow for a thread
  provenance <thread_id>       Show a run's semantic provenance (intent → volks → artifacts)
  log                          Show full postman message log
  help                         Show this help
  quit                         Exit
""")


def _print_human_response(
    msg: CXPPacket | None,
    *,
    include_clarification: bool = False,
    verbose_qa: bool = False,
) -> None:
    """Print a volk's human-facing response message.

    Args:
        msg: The CXP message to display (may be None).
        include_clarification: Print ``clarification`` subjects as plain text.
        verbose_qa: Include test file list / output for ``qa_complete``.
    """
    if not msg:
        return

    if include_clarification and msg.subject == "clarification":
        print(f"\n[{msg.from_agent}]:")
        print(msg.payload.get("text", "(no text)"))
    elif msg.subject == "implementation_ready":
        files = msg.payload.get("files_created", [])
        print(f"\n[{msg.from_agent}] Implementation ready!")
        print(f"  Files created: {len(files)}")
        for f in files:
            print(f"    - {f}")
    elif msg.subject == "qa_complete":
        _print_qa_complete(msg, verbose=verbose_qa)
    elif include_clarification:
        print(f"\n[{msg.from_agent}] ({msg.subject}):")
        print(msg.payload.get("text", str(msg.payload)))
    else:
        print(f"\n[{msg.from_agent}]:")
        print(msg.payload.get("text", "(no text)"))


def _print_qa_complete(msg: CXPPacket, *, verbose: bool = False) -> None:
    """Print a ``qa_complete`` message, optionally with test details."""
    test_passed = msg.payload.get("test_passed", False)
    status = "PASSED" if test_passed else "FAILED"
    print(f"\n[{msg.from_agent}] QA Review Complete — Tests {status}")
    if not verbose:
        return
    test_files = msg.payload.get("test_files", [])
    test_output = msg.payload.get("test_output", "")
    print(f"  Test files generated: {len(test_files)}")
    for f in test_files:
        print(f"    - {f}")
    if not test_passed:
        print(f"\n  Test output:\n{test_output[:500]}")


def _cmd_intent(
    kernel: PipelineRunner, args: str, active_thread: str | None
) -> str | None:
    """Handle the ``intent`` command. Returns the (possibly new) active thread."""
    text = args.strip().strip('"').strip("'")
    if not text:
        print('  Usage: intent "<your intent>"')
        return active_thread
    print(f'\n[Intent] "{text}"')
    thread_id = kernel.submit_intent(text)
    if thread_id:
        active_thread = thread_id
        print(f"\n[Thread {thread_id}] Intent submitted")
        # G85: same display logic as respond
        _print_human_response(kernel.get_last_human_message())
    print()
    return active_thread


def _parse_respond_args(
    args: str, active_thread: str | None
) -> tuple[str | None, str | None]:
    """Parse ``respond [thread_id] "<text>"`` args.

    Returns ``(thread_id, text)`` or ``(None, None)`` if no thread can be
    resolved.
    """
    stripped = args.strip()
    if re.match(r"[0-9a-f]{8}-", stripped):
        resp_parts = stripped.split(None, 1)
        thread_id = resp_parts[0]
        text = (
            resp_parts[1].strip().strip('"').strip("'") if len(resp_parts) > 1 else ""
        )
        return thread_id, text
    if active_thread:
        return active_thread, stripped.strip('"').strip("'")
    return None, None


def _cmd_respond(kernel: PipelineRunner, args: str, active_thread: str | None) -> None:
    """Handle the ``respond`` command."""
    thread_id, text = _parse_respond_args(args, active_thread)
    if thread_id is None or text is None:
        print('  Usage: respond <thread_id> "<text>"')
        return

    print(f'\n[Respond] Thread {thread_id}: "{text}"')
    kernel.respond(thread_id, text)
    _print_human_response(
        kernel.get_last_human_message(), include_clarification=True, verbose_qa=True
    )
    print()


def _cmd_status(kernel: PipelineRunner, active_thread: str | None) -> None:
    """Handle the ``status`` command."""
    print("\n[System Status]")
    for line in kernel.get_status():
        print(line)
    if active_thread:
        print(f"\n  Active thread: {active_thread}")
    print()


def _cmd_review(kernel: PipelineRunner, args: str) -> None:
    """Handle the ``review`` command."""
    volk_alias = args.strip()
    if not volk_alias:
        print("  Usage: review <volk> (e.g., review U:Cd)")
        return
    print(f"\n[Review {volk_alias}]")
    print(kernel.review_volk(volk_alias))
    print()


def _cmd_approve(kernel: PipelineRunner, args: str, active_thread: str | None) -> None:
    """Handle the ``approve`` command."""
    thread_id = args.strip() or active_thread
    if not thread_id:
        print("  Usage: approve <thread_id>")
        return
    print(f"\n[Approve] Thread {thread_id}")
    if not kernel.approve(thread_id):
        print("  ✗ Approval blocked — volk must continue")
    print()


def _cmd_packets(kernel: PipelineRunner, args: str, active_thread: str | None) -> None:
    """Handle the ``packets`` command."""
    thread_id = args.strip() or active_thread
    if not thread_id:
        print("  Usage: packets <thread_id>")
        return
    packets = kernel.postman.get_thread_packets(thread_id)
    print(f"\n[Packets] Thread {thread_id} — {len(packets)} packets:")
    for p in packets:
        print(f"  {p}")
    print()


def _cmd_provenance(args: str, active_thread: str | None) -> None:
    """Handle the ``provenance`` command — show a run's semantic provenance.

    Consumes ``QueryEngine.run_provenance`` (async) over the knowledge graph to
    report what a run did: the originating intent, the volks that executed, and
    the artifacts they produced. Read-only and best-effort — prints a clear
    message if the graph is unavailable.
    """
    import asyncio

    from orchestrata_ultimate.knowledge_graph.config import GraphClientConfig
    from orchestrata_ultimate.knowledge_graph.graph_client import GraphClient
    from orchestrata_ultimate.knowledge_graph.query_engine import QueryEngine

    thread_id = args.strip() or active_thread
    if not thread_id:
        print("  Usage: provenance <thread_id>")
        return

    async def _query() -> dict:
        client = GraphClient(config=GraphClientConfig())
        await client.connect()
        try:
            return await QueryEngine(client).run_provenance(thread_id)
        finally:
            await client.close()

    try:
        prov = asyncio.run(_query())
    except Exception as exc:  # graph unavailable — never crash the REPL
        print(f"  ✗ Provenance query failed: {exc}")
        return

    print(f"\n[Provenance] Thread {thread_id}")
    print(f"  Intent: {prov.get('intent') or '(none recorded)'}")
    volks = prov.get("volks") or []
    print(f"  Executed by: {', '.join(volks) if volks else '(none)'}")
    artifacts = prov.get("artifacts") or []
    print(f"  Artifacts ({len(artifacts)}):")
    for art in artifacts:
        print(
            f"    - {art.get('type', '?')} "
            f"[{art.get('stage', '?')}] {art.get('format', '')}".rstrip()
        )
    print()


def _cmd_log(kernel: PipelineRunner) -> None:
    """Handle the ``log`` command."""
    print("\n[Postman Log]")
    for line in kernel.postman.get_log():
        print(f"  {line}")
    print()


def _dispatch_command(
    kernel: PipelineRunner, cmd: str, args: str, active_thread: str | None
) -> tuple[str | None, bool]:
    """Dispatch a single REPL command.

    Returns ``(active_thread, should_quit)``.
    """
    if cmd in ("quit", "exit"):
        print("[Kernel] Shutting down.")
        kernel.shutdown(reason="User quit")
        return active_thread, True

    if cmd == "help":
        print_help()
    elif cmd == "intent":
        active_thread = _cmd_intent(kernel, args, active_thread)
    elif cmd == "respond":
        _cmd_respond(kernel, args, active_thread)
    elif cmd == "status":
        _cmd_status(kernel, active_thread)
    elif cmd == "review":
        _cmd_review(kernel, args)
    elif cmd == "approve":
        _cmd_approve(kernel, args, active_thread)
    elif cmd == "packets":
        _cmd_packets(kernel, args, active_thread)
    elif cmd == "provenance":
        _cmd_provenance(args, active_thread)
    elif cmd == "log":
        _cmd_log(kernel)
    else:
        print(f"  Unknown command: {cmd}. Type 'help' for available commands.")

    return active_thread, False


def main(kernel: PipelineRunner | None = None) -> None:
    print("=" * 60)
    print("  Orchestrata Architecture Spike v0.1")
    print("  Thin vertical slice — CXP + Prolog + Junior Volks")
    print("=" * 60)
    print()

    if kernel is None:
        kernel = PipelineRunner()
        kernel.boot()

    print_help()

    active_thread = None

    while True:
        try:
            raw = input("orchestrata> ").strip()
        except EOFError, KeyboardInterrupt:
            print("\n[Kernel] Shutting down.")
            kernel.shutdown(reason="Process interrupted")
            break

        if not raw:
            continue

        parts = raw.split(None, 1)
        cmd = parts[0].lower()
        args = parts[1] if len(parts) > 1 else ""

        active_thread, should_quit = _dispatch_command(kernel, cmd, args, active_thread)
        if should_quit:
            break


if __name__ == "__main__":
    main()