orchestrata_ultimate.factory.detectors.lexicons
Reference › orchestrata_ultimate › factory › detectors › lexicons
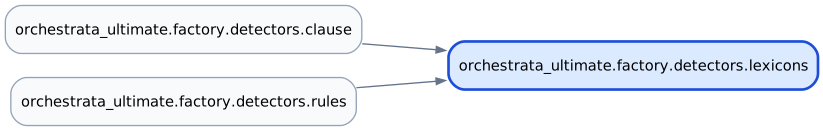
lexicons holds the word lists used by the C3 detectors (SPEC-033 row B22, ADR-0029), such as the subjective-language set, comparatives, negation markers, boundary words, placeholders and the conditional and rationale markers. They are starter sets; adding an entry changes a rule's recall, not its shape. Each constant documents its provenance and measured precision where one exists, and a missing precision is never invented. compile_lexicon (cached) compiles a set of entries into one case-insensitive pattern ordered longest-first, so a phrase such as "easy to use" wins over "easy" at the same position. _wrap_entry_boundary adds \b only on the side of an entry that borders a word character, so TBD does not match inside TBDX while a symbol entry such as ??? still matches literally. find_lexicon_matches returns every non-overlapping match in a text. The clause and rules modules import it. No test module imports it directly.
At a glance
| Source | src/orchestrata_ultimate/factory/detectors/lexicons.py |
| Lines of code | 313 |
| Classes | 0 |
| Functions | 3 |
| Imports (internal) | none |
| Imported by | orchestrata_ultimate.factory.detectors.clause, orchestrata_ultimate.factory.detectors.rules |
| Tests that import it | none |
Class diagram
No classes; see Functions.
Dependency diagram
API
Functions
| Function | Signature | Summary |
|---|---|---|
_wrap_entry_boundary |
_wrap_entry_boundary(raw: str) -> str |
Escape raw and add \b on whichever edge borders a word char. |
compile_lexicon functools.cache |
compile_lexicon(entries: frozenset[str], *, word_boundary: bool = True) -> re.Pattern[str] |
Compile entries into one case-insensitive, longest-first pattern. |
find_lexicon_matches |
find_lexicon_matches(text: str, entries: frozenset[str], *, word_boundary: bool = True) -> list[re.Match[str]] |
Return every non-overlapping match of entries in text. |
Source
"""Lexicons for the SPEC-033 C3 detector set (B22, ADR-0029).

Starter sets, deliberately extendable -- adding an entry never changes a
rule's shape, only its recall. Provenance and measured precision (where one
exists) are documented per constant; ``None``/absent precision is never
invented (ADR-0029, Femmer et al. JSS 2017 Tables 6-8 unless noted).

:func:`compile_lexicon` gives every rule the same word-boundary discipline:
each entry gets ``\\b`` on whichever side actually borders a word character,
so an alnum entry like ``TBD`` never partial-matches inside ``TBDX``, while a
symbol entry like ``???`` (no word chars at all, so ``\\b`` cannot apply)
still matches as a plain literal. Multi-word phrases are matched as literal
substrings with boundaries at the phrase's own edges. Entries are ordered
longest-first so a phrase (``"easy to use"``) is preferred over a
sub-matching single word (``"easy"``) at the same position.
"""

from __future__ import annotations

import functools
import re

# -- Tier 1 (BLOCKING) ------------------------------------------------------

# ISO/IEC/IEEE 29148 §5.2.7 "subjective language"; Femmer et al. JSS 2017
# Table 6 -- precision 0.96, recall 0.86 (dictionary family).
SUBJECTIVE = frozenset(
    {
        "user-friendly",
        "easy",
        "easy to use",
        "simple",
        "adequate",
        "appropriate",
        "efficient",
        "flexible",
        "intuitive",
        "seamless",
        "robust",
        "user-centric",
        "state-of-the-art",
        "powerful",
    }
)

# Femmer et al. Table 6 -- precision 0.81, recall 0.86 (dictionary family).
AMBIGUOUS_ADVERBS_ADJECTIVES = frozenset(
    {
        "almost",
        "approximately",
        "significant",
        "significantly",
        "minimal",
        "minimally",
        "some",
        "several",
        "few",
        "many",
        "most",
        "normal",
        "timely",
        "fast",
        "slow",
        "quickly",
        "regularly",
        "periodically",
        "sufficient",
        "sufficiently",
        "relevant",
        "common",
        "generally",
        "usually",
        "often",
        "typical",
        "typically",
    }
)

# Femmer et al. Table 6 -- precision 0.72, recall 0.86 (dictionary family).
LOOPHOLES = frozenset(
    {
        "as far as possible",
        "if possible",
        "where possible",
        "if necessary",
        "where applicable",
        "as appropriate",
        "as required",
        "to the extent practical",
        "whenever feasible",
        "as much as possible",
        "if needed",
    }
)

# Femmer et al. Table 6 -- precision 0.70, recall 0.86 (dictionary family).
OPEN_ENDED = frozenset(
    {
        "etc",
        "and so on",
        "including but not limited to",
        "such as",
        "but not limited to",
        "among others",
        "or similar",
        "and the like",
    }
)

# ISO 29148 §5.2.7 weak-modal class; no per-rule precision measured for this
# variant in Femmer et al. -- published_precision is None in rules.py's
# RuleMeta for this rule.
WEAK_MODALS = frozenset(
    {"may", "might", "could", "can", "should", "would", "ought to", "will possibly"}
)

# ISO 29148 §5.2.7 unresolved-placeholder class; not in Femmer's measured
# catalogue -- published_precision is None.
PLACEHOLDERS = frozenset({"TBD", "TBR", "TODO", "FIXME", "???", "<placeholder>", "XXX"})

# -- Tier 2 (ADVISORY) -------------------------------------------------------

# Femmer et al. Table 7 -- precision 0.49, recall 0.50.
SUPERLATIVES = frozenset(
    {
        "best",
        "worst",
        "most",
        "least",
        "fastest",
        "slowest",
        "highest",
        "lowest",
        "maximum possible",
        "minimal possible",
        "optimal",
        "optimum",
    }
)

# Femmer et al. Table 7 -- precision 0.48, recall 0.95.
COMPARATIVES = frozenset(
    {
        "better",
        "worse",
        "faster",
        "slower",
        "higher",
        "lower",
        "greater",
        "larger",
        "smaller",
        "more than",
        "less than",
        "at least",
        "at most",
        "improved",
        "increased",
        "reduced",
    }
)

# Femmer et al. Table 7 -- precision 0.33, recall 0.84.
NEGATION_MARKERS = frozenset(
    {
        "not",
        "never",
        "no",
        "none",
        "cannot",
        "can't",
        "won't",
        "shall not",
        "must not",
        "without",
    }
)

# Solution-language nouns (implementation vocabulary leaking into a
# requirement) -- no per-rule precision measured in the source study; this
# is a structural, not dictionary-family, detector.
SOLUTION_LANGUAGE_NOUNS = frozenset(
    {
        "database",
        "table",
        "thread",
        "mutex",
        "redis",
        "sql",
        "class",
        "function",
        "endpoint",
        "button",
    }
)

# -- Tier 3 (QUESTION-generating only) --------------------------------------

# Femmer et al. Table 8 -- precision 0.26, recall 0.92.
VAGUE_PRONOUNS = frozenset({"it", "this", "that", "these", "those", "they", "them"})

# Berry, Kamsties & Krieger (2003) §5.2-5.7 scope lexicon.
BOUNDARY_WORDS = frozenset(
    {
        "up to",
        "by",
        "until",
        "minimum",
        "maximum",
        "min",
        "max",
        "at least",
        "at most",
        "only",
        "also",
        "even",
        "between",
        "from",
        "to",
        "within",
        "exceed",
        "no more than",
        "no less than",
    }
)

TEMPORAL_NONSPECIFIC = frozenset(
    {
        "soon",
        "eventually",
        "immediately",
        "in a timely manner",
        "promptly",
        "as soon as possible",
        "real-time",
        "quickly",
        "periodically",
        "at regular intervals",
    }
)

DEICTIC = frozenset(
    {
        "above",
        "below",
        "aforementioned",
        "the former",
        "the latter",
        "previously mentioned",
        "as described",
        "said",
    }
)

UNDERSPECIFIED_HEAD_NOUNS = frozenset(
    {"the data", "the information", "the content", "the system"}
)

# -- Global rule support (clause segmentation) -------------------------------

RATIONALE_MARKERS = frozenset(
    {"so that", "in order to", "because", "to enable", "to allow", "to support"}
)

CONDITIONAL_MARKERS = frozenset(
    {
        "if",
        "when",
        "whenever",
        "where",
        "unless",
        "in case",
        "provided that",
        "as long as",
        "while",
        "until",
        "once",
    }
)


def _wrap_entry_boundary(raw: str) -> str:
    """Escape ``raw`` and add ``\\b`` on whichever edge borders a word char."""
    escaped = re.escape(raw)
    prefix = r"\b" if raw[:1].isalnum() or raw[:1] == "_" else ""
    suffix = r"\b" if raw[-1:].isalnum() or raw[-1:] == "_" else ""
    return f"{prefix}{escaped}{suffix}"


@functools.cache
def compile_lexicon(
    entries: frozenset[str], *, word_boundary: bool = True
) -> re.Pattern[str]:
    """Compile ``entries`` into one case-insensitive, longest-first pattern.

    ``word_boundary=False`` disables the per-entry boundary wrap entirely
    (a plain literal-alternation match) -- used where a rule wants raw
    substring matches regardless of context.
    """
    ordered = sorted(entries, key=len, reverse=True)
    if word_boundary:
        parts = [_wrap_entry_boundary(e) for e in ordered]
    else:
        parts = [re.escape(e) for e in ordered]
    return re.compile("|".join(parts), re.IGNORECASE)


def find_lexicon_matches(
    text: str, entries: frozenset[str], *, word_boundary: bool = True
) -> list[re.Match[str]]:
    """Return every non-overlapping match of ``entries`` in ``text``."""
    pattern = compile_lexicon(entries, word_boundary=word_boundary)
    return list(pattern.finditer(text))