Orchestrata Ultimate › Tests › Running the test suite
Running the test suite (orchestrata-ultimate)
Start at the tests guide (updated 2026-10-23). It covers what the suite contains, every
run_tests.pymode, the rules (including the 300 s test-phase cap), the test fleet, the pre-push gate, RUL-032 green-ledger reuse, the slow tail, and how to read a report. This page keeps the detailed caveats and teardown patterns that the guide links to. The timing table below is the 2026-07-18 record; current durations are on durations.
The canonical entry point is .venv/bin/python scripts/run_tests.py. As of 2026-10-23 its stages are: freshness guard, affected-set resolution, infrastructure check, five blocking static gates, proven-run and green-ledger reuse, a capped batched executor, a solo-retry round, package parity suites, and the report. The tests guide has the full pipeline diagram. CI and local runs both go through it (enforced by scripts/validate_ci.py).
The pipeline at a glance
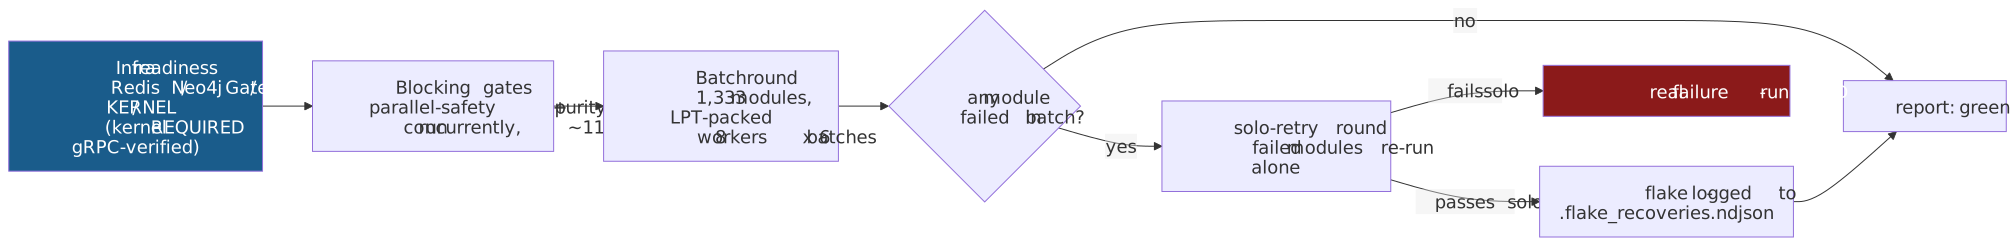
A module that fails in a batch but passes alone is a contention flake, not a bug — the solo-retry round exists to make that distinction mechanically.
Timing (record of 2026-07-18)
The 2026-07-18 numbers below predate the 300 s test-phase cap, the green ledger and affected-only runs. Later measurements: the gate floor of about 250 s (suite parallelism floor) and the per-module durations.
| Stage | Time |
|---|---|
| Infra readiness check (Redis / Neo4j / Memgraph / Prolog / gateway up) | seconds |
| Blocking gates (parallel-safety static analysis + test-purity audit) | ~11 s (run concurrently since 2026-07-18; was 35 s serial) |
Batched execution (1,333 test modules, -j 8 × 6 batches/worker) |
~10 min (596 s, clean authoritative run, measured 2026-07-18) |
| Solo-retry round (batch-failed modules re-run in isolation) | variable |
| Total wall-clock | ~10 min 12 s (612 s) |
Measured 2026-07-18 (session 242, quiescent box, kernel gRPC-verified), two runs: 26,859 passed / 0 failed / 0 skipped in 10:12 end-to-end (runner timer 596 s), replicated at 10:30 (runner timer 608 s, 1 flake recovered solo) — 30.0–32.4% faster than the 2026-07-11 baseline (869 s runner timer / ~905–910 s end-to-end, which was a 17-failure run) despite the suite growing by ~2,600 tests. Run-to-run variance ≈ 3%. The session-242 speed levers: parallel static gates, Memgraph resource-group co-scheduling in the batch packer (contended files share one bin), the janus-swi in-process Prolog transport, the AST warm cache + resident AST daemon, and canonical-schema migration of the per-worker Neo4j replicas (which eliminated the parallel-only ConstraintError retries).
Caveats (READ before running or debugging a "slow"/"flaky" run)
1. NEVER use pytest -n auto / --dist / pytest-xdist
xdist deadlocks this suite (~78%). Use the batched executor
(scripts/run_tests.py, or scripts/run_tests_threadpool.py). This is enforced
by a PreToolUse hook + test-review rule T15. The batched executor gets
parallelism from per-worker process isolation (per-worker Neo4j instances via
NEO4J_URI_GW<N>, per-slot Redis DB), not from xdist.
2. A handful of live-e2e modules are slow and flake under parallel contention
The Memgraph semantic-graph adapter tests, some gateway/pipeline e2e modules, and anything writing to the shared Memgraph HA cluster are slow and can fail under load (concurrent writers/readers on the same shared cluster — see HA controller). These are order/contention flakes, not real breakage:
- The solo-retry round exists precisely to absorb them — a module that
fails in a batch is re-run alone; if it passes, it's a flake (logged to
.flake_recoveries.ndjson), not a failure. This is why end-to-end wall time exceeds the raw batch time. - If you run a subset by hand and see a Memgraph-adapter failure, re-run that
file ALONE before believing it — it almost always passes without the
contention. Do not run two suites against the shared Memgraph cluster
concurrently (the
storage.access_timeoutaborts a writer if you poll it with reads mid-write).
3. Tests must be observed, not waited on
Never run the suite in the foreground and read only the exit code (a deny-hook
blocks it). Launch it in the background and watch it with the deployed observers
(/opt/orchestrata-tools/bin, on PATH; current as of 2026-10-23):
pytest-live <paths> -q &           # background; puts the observer plugin on PYTHONPATH
observe-pytest list                # find the session (instant)
observe-pytest attach latest       # stream PASS/FAIL until the session finishes
The older in-repo form still works inside a checkout:
python scripts/observe_pytest.py list and attach <id> --follow.
4. Real infrastructure only — no mocks
Every test uses the real fleet. The addresses in this paragraph's original form
(Redis .10, Neo4j .11, Memgraph HA orchgraph-*, Prolog .16/.17/.18) are the
2026-07 shared fleet. Since then the suite is pinned to the isolated orchestrata-test
fleet on 10.53.2.0/24 through env/test.env; see the
tests guide.
No mocks/fakes/stubs/monkeypatch anywhere
(enforced by scripts/audit_test_purity.py + a stop-hook). A failing test that
catches a real bug is fixed in the code, never weakened.
5. Teardown patterns — how tests must clean the graphs (2026-07-21)
Slow teardown was the dominant per-test tax (see the speedup story, Wave 2). Rules for new tests:
- Never write a label-less cleanup (
MATCH (n) WHERE n.test_id = ...) — it full-scans ~800k nodes. Enumerate the labels you write in an indexedCALL () { MATCH (n:Label) WHERE ... UNION ALL ... } WITH n DETACH DELETE nsweep; for Session-sized labels use an indexedSTARTS WITHseek. tests/knowledge_graph/cleans at session end, not per test — the autouse_neo4j_cleanuponly registers yourtest_id; one session-end sweep deletes everything in 200-id chunks. Consequence: any name your test LINKS/SEARCHES by (not just node ids) must embed thetest_iddown to the leaf, because sibling tests' nodes are still present while yours runs.- Memgraph: never create per-test indexes or labels — index creation
scans the whole vertex store (~2.5s even for an empty label). Use the
session-scoped worker-slot label (
TestChunk<slot>intest_memgraph_adapter.py) and isolate by test_id-prefixed ids. Never physically delete chunks under the shared HNSW vector index mid-session (deleted objects surface in results for >10s). - Isolation-audit waivers: a judged-sanctioned seam gets
# gate-ok: <reason>DIRECTLY above the flagged line; a detector-fixture file whose strings trip the scanner gets# isolation-audit-file-ok: CATEGORY: <reason>in its first 30 lines. Reasons are mandatory; the audit runs at 0 violations.
6. Every Redis key a test writes must be scoped — the fixture doesn't do it for you (2026-08-12)
The redis_client fixture (tests/conftest.py) connects with no db=
argument:
client = redis_lib.Redis(
    host=TestSettings().REDIS_HOST,
    port=TestSettings().REDIS_PORT,
    decode_responses=True,
    socket_connect_timeout=5,
    socket_timeout=5,
)
That lands on Redis logical database 0 — the redis-py library default —
which is also REDIS_DB=0 in env/test.env, the same database the live
test-fleet kernel and gateway use (InfraConfig.redis_host/redis_port
resolve the identical REDIS_HOST/REDIS_PORT keys). TestSettings even
declares a REDIS_DB: int = 0 field, but the fixture never reads it — the
isolation this buys is coincidental, not designed. Fixture teardown only
deletes keys matching f"{test_id}:*", so any key your test writes without
that prefix is a live cross-worker collision and a permanent leak into the
database the running fleet depends on, not a test-only side effect.
This is exactly what Gate 0.4 (Redis key namespacing,
scripts/gate_parallel_safety.py) exists to catch statically — see
a checker must prove it looked for
how thoroughly the original version of that gate missed it (130 real sites
found on rebuild; the old detector's own frozen tree comparison found 101 of
what the rebuilt one finds 138 of, on the identical code). The two legitimate
outs are: derive the key from test_id (verifiable — the gate proves it, not
just asserts it), or bind to a genuinely isolated database via
_worker_redis_db() (tests/fixtures/redis.py) and record why in a # gate-ok: <reason> waiver directly on the write.