HA Controller
DECOMMISSIONED 2026-07-10. This page describes the custom Python HTTP HA controller (
memgraph-ha) that fronted the old 3-node Memgraph Community cluster. That controller and cluster were deleted on 2026-07-10. The live cluster is orchgraph (Raft HA — 3 coordinators + 2 data instances) with no HTTP controller: failover is coordinator-managed and clients connect with a routing driver atneo4j://10.53.1.160:7691. Retained as a design record — see Memgraph HA Cluster Reference (orchgraph).
The HA controller monitors a Memgraph data cluster, detects MAIN/replica state, and exposes a simple HTTP API so clients do not need to track the current MAIN node.
Responsibilities
- Discover cluster nodes from
MEMGRAPH_URIS. - Periodically query each node for its role (MAIN/REPLICA).
- Expose
/mainreturning the current MAIN Bolt URI. - Trigger failover when MAIN is unreachable.
- Trigger failback to a preferred node when it recovers.
API
| Endpoint | Method | Description |
|---|---|---|
/status |
GET | Controller health and cluster view |
/main |
GET | Current MAIN Bolt URI |
/failover |
POST | Demote MAIN, promote replica |
/failback |
POST | Promote preferred node back to MAIN |
Autofailback
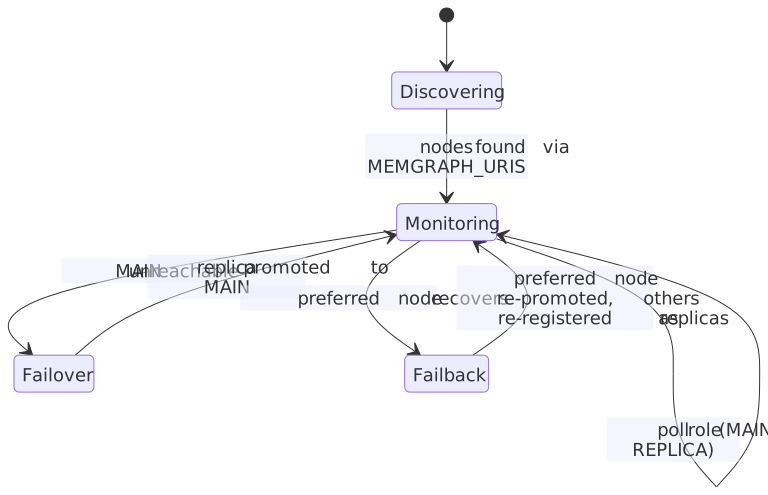
Autofailback is the primary requirement: when the preferred MAIN node returns, the controller automatically re-promotes it and re-registers the other nodes as replicas.
Cluster state lifecycle managed by the controller
Known Limitations
- Controller container was a single point of failure (one motivation for the Raft redesign).
- Cluster split-brain protection relies on the controller's single view.