orchestrata_ultimate.refactor.ctok.tokenizer
Reference › orchestrata_ultimate › refactor › ctok › tokenizer
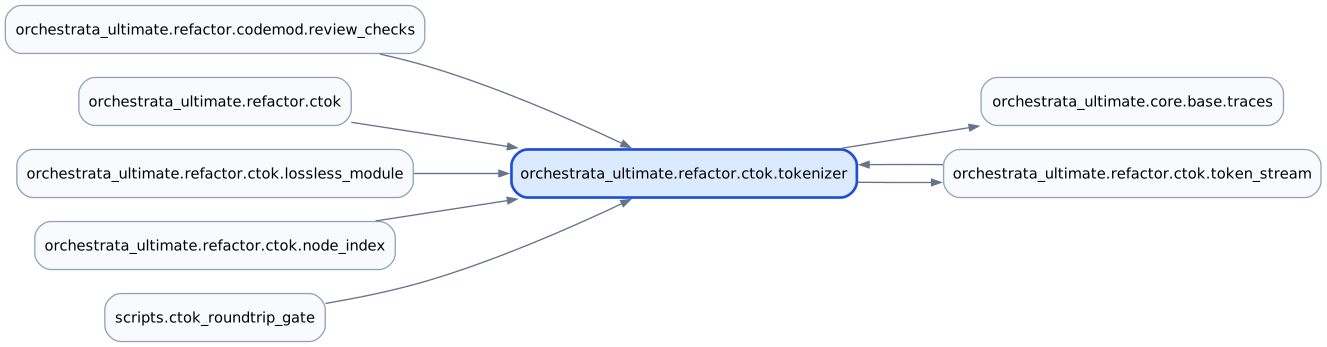
The Python surface over the ctok C extension, a free-threading-safe tokenizer for Python 3.14 source. It is the first layer of the lossless pipeline described in the ctok index and is traced to spec 110 story US-110-006 (REQ-110-120 to 122). Besides the other ctok modules it is imported by the codemod review_checks and by the ctok_roundtrip_gate script.
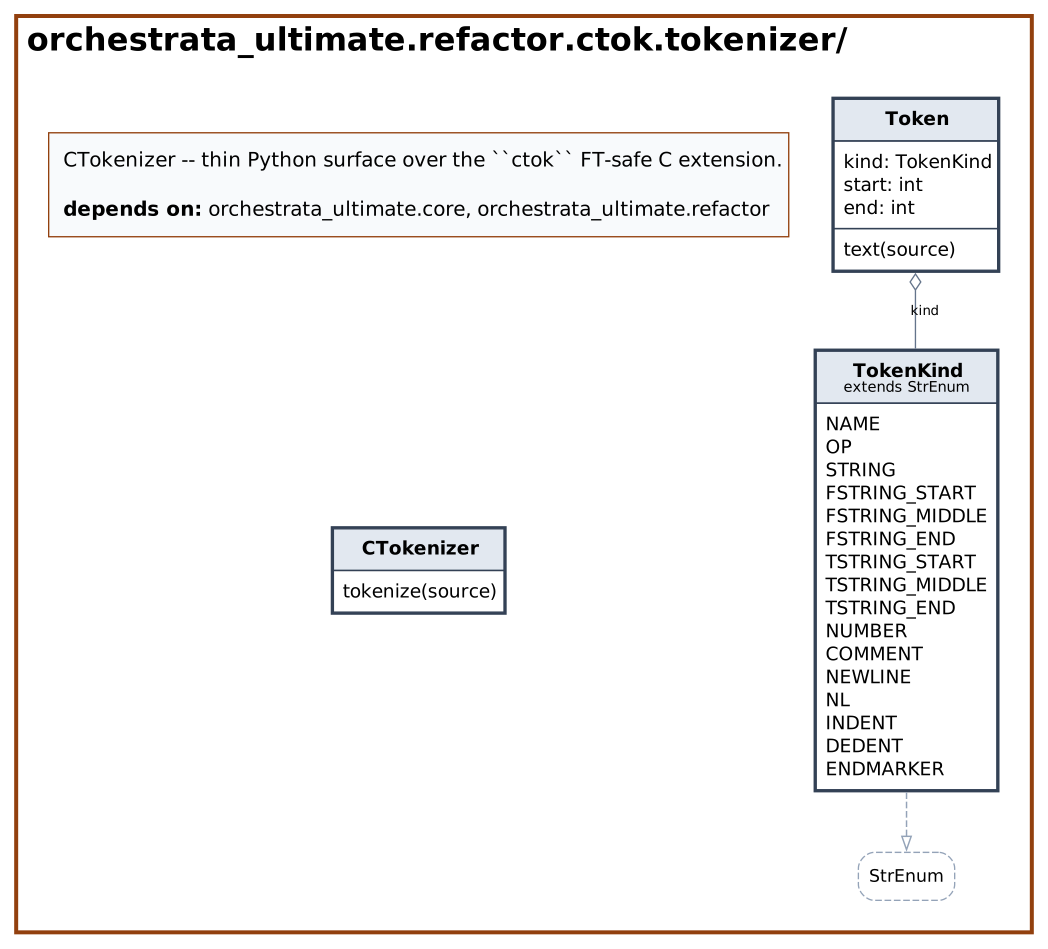
TokenKind is a StrEnum of lexical kinds. A Token is a frozen record of a kind and a start and end byte offset into the original source, with text(source) returning the bytes it covers. CTokenizer.tokenize takes raw file bytes (not decoded text, so byte order marks and CRLF never depend on an encoding), calls the native tokenizer, converts its numeric kind codes into TokenKind, and returns a TokenStream whose reconstruct() equals the input.
At a glance
| Source | src/orchestrata_ultimate/refactor/ctok/tokenizer.py |
| Lines of code | 122 |
| Classes | 3 |
| Functions | 0 |
| Imports (internal) | orchestrata_ultimate.core.base.traces, orchestrata_ultimate.refactor.ctok.token_stream |
| Imported by | orchestrata_ultimate.refactor.codemod.review_checks, orchestrata_ultimate.refactor.ctok, orchestrata_ultimate.refactor.ctok.lossless_module, orchestrata_ultimate.refactor.ctok.node_index, orchestrata_ultimate.refactor.ctok.token_stream, scripts.ctok_roundtrip_gate |
| Tests that import it | tests/refactor/codemod/test_transactional_writeback.py, tests/refactor/ctok/test_node_index.py, tests/refactor/ctok/test_token_stream.py, tests/refactor/ctok/test_tokenizer.py |
Class diagram
Dependency diagram
API
Constants
| Name | Type | Value |
|---|---|---|
_KIND_BY_CODE |
tuple[TokenKind, ...] |
(TokenKind.NAME, TokenKind.OP, TokenKind.STRING, TokenKind.FSTRING_START, Token… |
Classes
TokenKind (enum)
Bases: StrEnum · Line 22
Lexical token kinds produced by the C tokenizer.
| Member | Value |
|---|---|
NAME |
'NAME' |
OP |
'OP' |
STRING |
'STRING' |
FSTRING_START |
'FSTRING_START' |
FSTRING_MIDDLE |
'FSTRING_MIDDLE' |
FSTRING_END |
'FSTRING_END' |
TSTRING_START |
'TSTRING_START' |
TSTRING_MIDDLE |
'TSTRING_MIDDLE' |
TSTRING_END |
'TSTRING_END' |
NUMBER |
'NUMBER' |
COMMENT |
'COMMENT' |
NEWLINE |
'NEWLINE' |
NL |
'NL' |
INDENT |
'INDENT' |
DEDENT |
'DEDENT' |
ENDMARKER |
'ENDMARKER' |
Token (dataclass)
Decorators: traces(spec='110', story='US-110-006', reqs=['REQ-110-120']), dataclass(frozen=True, slots=True) · Line 75
One lexical token as a byte span over the original source.
| Attribute | Type | Default |
|---|---|---|
kind |
TokenKind |
|
start |
int |
|
end |
int |
| Method | Signature | Summary |
|---|---|---|
text |
text(source: bytes) -> bytes |
Exact original bytes this token spans. |
CTokenizer
Decorators: traces(spec='110', story='US-110-006', reqs=['REQ-110-120', 'REQ-110-121']) · Line 101
FT-safe C tokenizer for Python 3.14 source, producing a TokenStream.
| Method | Signature | Summary |
|---|---|---|
tokenize staticmethod |
tokenize(source: bytes) -> TokenStream |
Tokenize source into a lossless TokenStream. |
Source
"""CTokenizer -- thin Python surface over the ``ctok`` FT-safe C extension.

P1 of the ctok-parser contract (plans/contracts/ctok-parser.contract.json):
a C extension that DRIVES CPython's own lexer (see scripts/_ctok/README.md)
replaces LibCST's Rust parser as the lexical layer feeding SPEC-110's
codemod engine. ``CTokenizer.tokenize`` returns a
:class:`~orchestrata_ultimate.refactor.ctok.token_stream.TokenStream` whose
``reconstruct()`` is byte-identical to the input by construction.
"""

from __future__ import annotations

from dataclasses import dataclass
from enum import StrEnum

from ctok import tokenize as _native_tokenize

from orchestrata_ultimate.core.base.traces import traces
from orchestrata_ultimate.refactor.ctok.token_stream import TokenStream


class TokenKind(StrEnum):
    """Lexical token kinds produced by the C tokenizer.

    Order matches the C extension's integer kind codes exactly (see
    ``_KIND_BY_CODE`` below and the ``TK_*`` constants in
    ``scripts/_ctok/ctok/_ctok.c``) -- do not reorder without updating
    both sides. Extends the ratified 13-member enum
    (``plans/contracts/ctok-parser.mmd``) additively with
    ``TSTRING_START``/``MIDDLE``/``END`` (PEP 750 t-strings, new in Python
    3.14): CPython's real lexer reports them as their own token type, and
    collapsing them into the FSTRING kinds would mislabel real t-strings.
    """

    NAME = "NAME"
    OP = "OP"
    STRING = "STRING"
    FSTRING_START = "FSTRING_START"
    FSTRING_MIDDLE = "FSTRING_MIDDLE"
    FSTRING_END = "FSTRING_END"
    TSTRING_START = "TSTRING_START"
    TSTRING_MIDDLE = "TSTRING_MIDDLE"
    TSTRING_END = "TSTRING_END"
    NUMBER = "NUMBER"
    COMMENT = "COMMENT"
    NEWLINE = "NEWLINE"
    NL = "NL"
    INDENT = "INDENT"
    DEDENT = "DEDENT"
    ENDMARKER = "ENDMARKER"


_KIND_BY_CODE: tuple[TokenKind, ...] = (
    TokenKind.NAME,
    TokenKind.OP,
    TokenKind.STRING,
    TokenKind.FSTRING_START,
    TokenKind.FSTRING_MIDDLE,
    TokenKind.FSTRING_END,
    TokenKind.TSTRING_START,
    TokenKind.TSTRING_MIDDLE,
    TokenKind.TSTRING_END,
    TokenKind.NUMBER,
    TokenKind.COMMENT,
    TokenKind.NEWLINE,
    TokenKind.NL,
    TokenKind.INDENT,
    TokenKind.DEDENT,
    TokenKind.ENDMARKER,
)


@traces(spec="110", story="US-110-006", reqs=["REQ-110-120"])
@dataclass(frozen=True, slots=True)
class Token:
    """One lexical token as a byte span over the original source.

    Attributes:
        kind: Lexical category.
        start: Byte offset of the token's first byte (inclusive).
        end: Byte offset one past the token's last byte (exclusive).
    """

    kind: TokenKind
    start: int
    end: int

    def text(self, source: bytes) -> bytes:
        """Exact original bytes this token spans.

        Args:
            source: The same bytes object the token was produced from.

        Returns:
            ``source[self.start:self.end]``.
        """
        return source[self.start : self.end]


@traces(spec="110", story="US-110-006", reqs=["REQ-110-120", "REQ-110-121"])
class CTokenizer:
    """FT-safe C tokenizer for Python 3.14 source, producing a TokenStream."""

    @traces(spec="110", story="US-110-006", reqs=["REQ-110-120", "REQ-110-121"])
    @staticmethod
    def tokenize(source: bytes) -> TokenStream:
        """Tokenize ``source`` into a lossless TokenStream.

        Args:
            source: Raw file bytes (not decoded -- the tokenizer works on
                bytes directly so BOM/CRLF handling never depends on a
                chosen text encoding).

        Returns:
            TokenStream whose ``reconstruct()`` equals ``source``.
        """
        raw = _native_tokenize(source)
        tokens = tuple(
            Token(kind=_KIND_BY_CODE[kind], start=start, end=end)
            for kind, start, end in raw
        )
        return TokenStream(source=source, tokens=tokens)