orchestrata_ultimate.refactor.ctok.token_stream
Reference › orchestrata_ultimate › refactor › ctok › token_stream
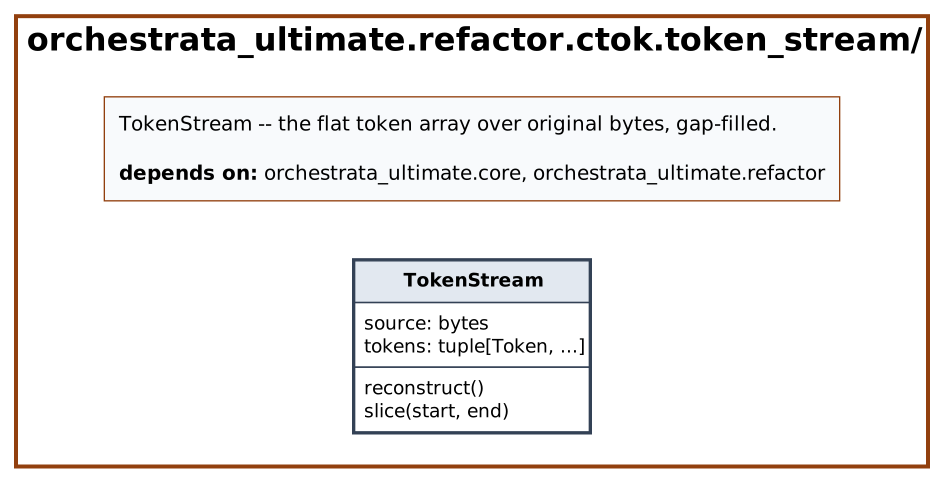
TokenStream is the flat token array over the original bytes, produced by CTokenizer and used by node_index and lossless_module. It is a frozen dataclass holding the unmodified source bytes and the tokens in source order, which may leave gaps such as whitespace or a byte order mark. reconstruct rebuilds the source by emitting each gap from the original bytes and each token span, advancing a watermark so it equals the source for any in-bounds token list, even an overlapping or unordered one (REQ-110-120). slice(start, end) returns the raw original bytes in a range.
At a glance
| Source | src/orchestrata_ultimate/refactor/ctok/token_stream.py |
| Lines of code | 78 |
| Classes | 1 |
| Functions | 0 |
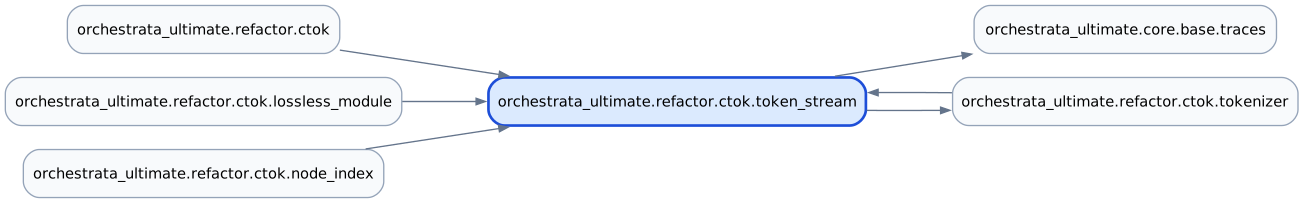
| Imports (internal) | orchestrata_ultimate.core.base.traces, orchestrata_ultimate.refactor.ctok.tokenizer |
| Imported by | orchestrata_ultimate.refactor.ctok, orchestrata_ultimate.refactor.ctok.lossless_module, orchestrata_ultimate.refactor.ctok.node_index, orchestrata_ultimate.refactor.ctok.tokenizer |
| Tests that import it | tests/refactor/ctok/test_token_stream.py, tests/refactor/ctok/test_tokenizer.py |
Class diagram
Dependency diagram
API
Classes
TokenStream (dataclass)
Decorators: traces(spec='110', story='US-110-006', reqs=['REQ-110-120', 'REQ-110-122']), dataclass(frozen=True, slots=True) · Line 26
Original bytes plus the token array covering (most of) them.
| Attribute | Type | Default |
|---|---|---|
source |
bytes |
|
tokens |
tuple[Token, ...] |
| Method | Signature | Summary |
|---|---|---|
reconstruct |
reconstruct() -> bytes |
Byte-splice the original source back together. |
slice |
slice(start: int, end: int) -> bytes |
Raw original bytes in [start, end). |
Source
"""TokenStream -- the flat token array over original bytes, gap-filled.

P1 of the ctok-parser contract (plans/contracts/ctok-parser.contract.json):
losslessness lives here, not in the C tokenizer. CPython's own lexer
(driven by ``ctok._ctok.tokenize``, see scripts/_ctok/README.md) does not
itself emit a token for every byte -- inter-token whitespace and a leading
BOM are simply not tokens. ``reconstruct()`` gap-fills those bytes straight
from the ORIGINAL ``source``, so byte-identity holds regardless of exactly
which spans the tokenizer chooses to report (proven tree-wide by
scripts/ctok_roundtrip_gate.py).
"""

from __future__ import annotations

from dataclasses import dataclass
from typing import TYPE_CHECKING

from orchestrata_ultimate.core.base.traces import traces

if TYPE_CHECKING:
    from orchestrata_ultimate.refactor.ctok.tokenizer import Token


@traces(spec="110", story="US-110-006", reqs=["REQ-110-120", "REQ-110-122"])
@dataclass(frozen=True, slots=True)
class TokenStream:
    """Original bytes plus the token array covering (most of) them.

    Attributes:
        source: The original, unmodified source bytes.
        tokens: Tokens in source order. May contain gaps (untokenized
            whitespace/BOM bytes) -- ``reconstruct()`` fills them from
            ``source``, not from the tokens themselves.
    """

    source: bytes
    tokens: tuple[Token, ...]

    def reconstruct(self) -> bytes:
        """Byte-splice the original source back together.

        Walks the tokens in order, emitting any untokenized gap before
        each one straight from ``source``, then the token's own span
        (clipped to never re-emit bytes already covered by an earlier
        token), and finally any trailing gap after the last token. A
        watermark (``pos``) only ever advances, so this is byte-identical
        to ``source`` for ANY token list that stays within bounds -- even
        one with overlapping or out-of-order spans -- which is exactly
        what REQ-110-120 requires.

        Returns:
            Bytes equal to ``self.source``.
        """
        parts: list[bytes] = []
        pos = 0
        for token in self.tokens:
            if token.start > pos:
                parts.append(self.source[pos : token.start])
            start = max(pos, token.start)
            if token.end > start:
                parts.append(self.source[start : token.end])
            pos = max(pos, token.end)
        if pos < len(self.source):
            parts.append(self.source[pos:])
        return b"".join(parts)

    @traces(spec="110", story="US-110-006", reqs=["REQ-110-120", "REQ-110-122"])
    def slice(self, start: int, end: int) -> bytes:
        """Raw original bytes in ``[start, end)``.

        Args:
            start: Inclusive byte offset.
            end: Exclusive byte offset.

        Returns:
            ``self.source[start:end]``.
        """
        return self.source[start:end]