orchestrata_ultimate.refactor.codemod.passes
Reference › orchestrata_ultimate › refactor › codemod › passes
The built-in transform passes of the codemod engine. A pass takes the in-memory workspace and returns a ChangeSet (see report) of mutated trees; passes do no disk I/O, which a test enforces (REQ-110-011). All edits are byte splices through the ctok layer, so formatting outside the edit is untouched. The facade, the daemon server and scripts.codemod import it.
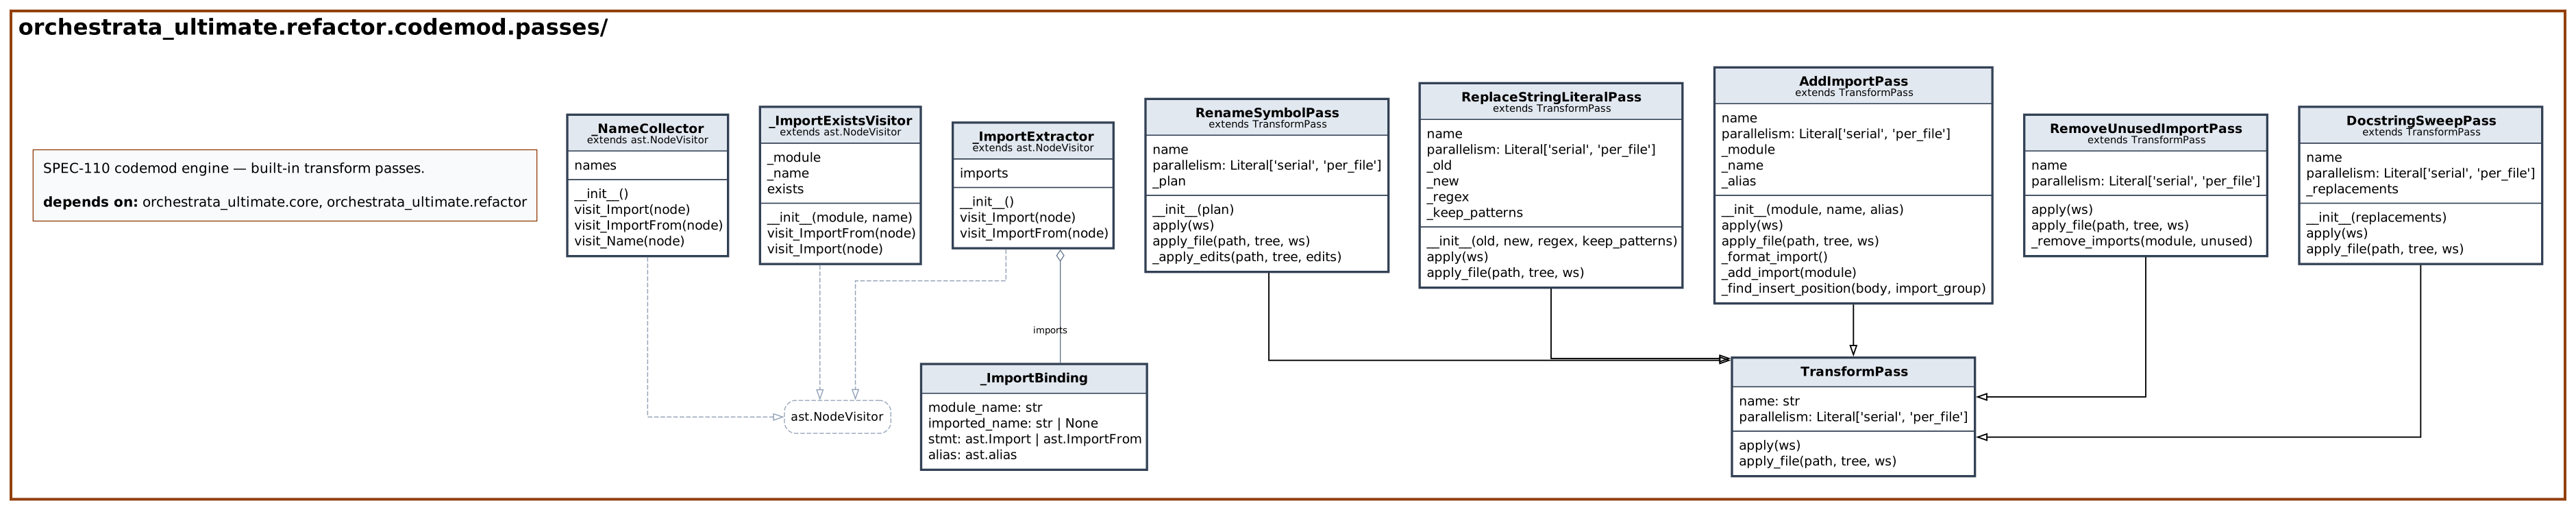
TransformPass is the base class: apply(ws) runs the whole workspace and apply_file one file, and a parallelism attribute says whether the pass is serial or per file. The concrete passes:
ReplaceStringLiteralPass: replaces string literals, exact or by regular expression, withkeep_patternsguarding literals to leave alone. It keeps the literal's prefix and refuses a replacement that would break its quoting.AddImportPass: adds an import (module, optional name and alias) to the right group (standard library, third party, local) at the right position, skipping files that already have it.RemoveUnusedImportPass: collects the names a module binds through imports and removes those never referenced.DocstringSweepPass: applies a vocabulary mapping to docstrings and comments only (REQ-110-010), never to string literals that are code.RenameSymbolPass: consumes a workspace edit plan from SPEC-109, resolves each line and column edit to byte offsets, and applies it through anEditBuffer. Every splice is guarded byverify_editso that a rename changes identifier fields only (REQ-110-127).
At a glance
| Source | src/orchestrata_ultimate/refactor/codemod/passes.py |
| Lines of code | 1051 |
| Classes | 10 |
| Functions | 9 |
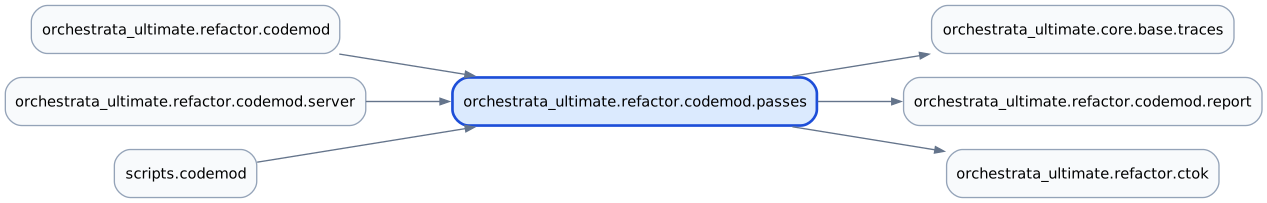
| Imports (internal) | orchestrata_ultimate.core.base.traces, orchestrata_ultimate.refactor.codemod.report, orchestrata_ultimate.refactor.ctok |
| Imported by | orchestrata_ultimate.refactor.codemod, orchestrata_ultimate.refactor.codemod.server, scripts.codemod |
| Tests that import it | tests/refactor/codemod/test_cli.py, tests/refactor/codemod/test_docstring_sweep_scope.py, tests/refactor/codemod/test_observability_wiring.py, tests/refactor/codemod/test_review_engine.py, tests/refactor/codemod/test_review_engine_commit_wiring.py, tests/refactor/codemod/test_transactional_writeback.py, tests/refactor/codemod/test_transform_passes.py, tests/scripts/test_codemod_cli.py |
Class diagram
Dependency diagram
API
Classes
TransformPass
Decorators: traces(spec='110', story='US-110-003', reqs=['REQ-110-011']) · Line 50
Abstract base class for transform passes.
| Attribute | Type | Default |
|---|---|---|
name |
str |
'TransformPass' |
parallelism |
Literal['serial', 'per_file'] |
'serial' |
| Method | Signature | Summary |
|---|---|---|
apply |
apply(ws: Any) -> ChangeSet |
Apply the transform pass to the workspace. |
apply_file |
apply_file(path: str, tree: LosslessModule, ws: Any) -> ChangeEntry | None |
Apply the transform to a single file (for per_file parallelism). |
ReplaceStringLiteralPass
Bases: TransformPass · Decorators: traces(spec='110', story='US-110-002', reqs=['REQ-110-010']) · Line 268
Replace string literals in exact or regex mode with keep-pattern guard.
| Attribute | Type | Default |
|---|---|---|
parallelism |
Literal['serial', 'per_file'] |
'per_file' |
| Method | Signature | Summary |
|---|---|---|
__init__ |
__init__(old: str, new: str, regex: bool = False, keep_patterns: Sequence[str] = ()) -> None |
Initialize string literal replacement pass. |
apply |
apply(ws: Any) -> ChangeSet |
Apply string replacement across all files in workspace. |
apply_file |
apply_file(path: str, tree: LosslessModule, ws: Any) -> ChangeEntry | None |
Replace string literals in one file. |
_ImportExistsVisitor
Bases: ast.NodeVisitor · Line 341
Check if an import already exists in the module.
| Method | Signature | Summary |
|---|---|---|
__init__ |
__init__(module: str, name: str | None) -> None |
|
visit_ImportFrom |
visit_ImportFrom(node: ast.ImportFrom) -> None |
Check from-import statements. |
visit_Import |
visit_Import(node: ast.Import) -> None |
Check import statements. |
AddImportPass
Bases: TransformPass · Decorators: traces(spec='110', story='US-110-007', reqs=['REQ-110-010']) · Line 470
Add import statement to target modules.
| Attribute | Type | Default |
|---|---|---|
parallelism |
Literal['serial', 'per_file'] |
'per_file' |
| Method | Signature | Summary |
|---|---|---|
__init__ |
__init__(module: str, name: str | None = None, alias: str | None = None) -> None |
Initialize import addition pass. |
apply |
apply(ws: Any) -> ChangeSet |
Add import to all files in workspace. |
apply_file |
apply_file(path: str, tree: LosslessModule, ws: Any) -> ChangeEntry | None |
Add import to one file. |
_format_import |
_format_import() -> str |
Format the import statement for description. |
_add_import |
_add_import(module: LosslessModule) -> LosslessModule |
Add import statement to module in correct group. |
_find_insert_position |
_find_insert_position(body: Sequence[ast.stmt], import_group: str) -> int |
Find position to insert import based on group ordering. |
_NameCollector
Bases: ast.NodeVisitor · Line 609
Collect all Name nodes in the module body (excluding imports).
| Method | Signature | Summary |
|---|---|---|
__init__ |
__init__() -> None |
|
visit_Import |
visit_Import(node: ast.Import) -> None |
Skip import statements -- they carry no Name child nodes to collect. |
visit_ImportFrom |
visit_ImportFrom(node: ast.ImportFrom) -> None |
Skip from-import statements -- they carry no Name child nodes to collect. |
visit_Name |
visit_Name(node: ast.Name) -> None |
_ImportBinding (dataclass)
Decorators: dataclass(slots=True) · Line 626
One imported alias, tracked separately from its sibling aliases.
| Attribute | Type | Default |
|---|---|---|
module_name |
str |
|
imported_name |
str | None |
|
stmt |
ast.Import | ast.ImportFrom |
|
alias |
ast.alias |
_ImportExtractor
Bases: ast.NodeVisitor · Line 645
Extract imported names from a module, per alias (Finding 3 fix).
| Method | Signature | Summary |
|---|---|---|
__init__ |
__init__() -> None |
|
visit_Import |
visit_Import(node: ast.Import) -> None |
|
visit_ImportFrom |
visit_ImportFrom(node: ast.ImportFrom) -> None |
RemoveUnusedImportPass
Bases: TransformPass · Decorators: traces(spec='110', story='US-110-007', reqs=['REQ-110-010']) · Line 666
Remove imports not referenced in module body.
| Attribute | Type | Default |
|---|---|---|
parallelism |
Literal['serial', 'per_file'] |
'per_file' |
| Method | Signature | Summary |
|---|---|---|
apply |
apply(ws: Any) -> ChangeSet |
Remove unused imports from all files. |
apply_file |
apply_file(path: str, tree: LosslessModule, ws: Any) -> ChangeEntry | None |
Remove unused imports from one file. |
_remove_imports |
_remove_imports(module: LosslessModule, unused: list[_ImportBinding]) -> LosslessModule |
Remove unused import aliases, statement-by-statement. |
DocstringSweepPass
Bases: TransformPass · Decorators: traces(spec='110', story='US-110-002', reqs=['REQ-110-010']) · Line 878
Vocabulary replacement in docstrings AND comments (REQ-110-010).
| Attribute | Type | Default |
|---|---|---|
parallelism |
Literal['serial', 'per_file'] |
'per_file' |
| Method | Signature | Summary |
|---|---|---|
__init__ |
__init__(replacements: dict[str, str]) -> None |
Initialize docstring sweep pass. |
apply |
apply(ws: Any) -> ChangeSet |
Apply vocabulary replacements across all files. |
apply_file |
apply_file(path: str, tree: LosslessModule, ws: Any) -> ChangeEntry | None |
Replace vocabulary in docstrings and comments of one file. |
RenameSymbolPass
Bases: TransformPass · Decorators: traces(spec='110', story='US-110-009', reqs=['REQ-110-010', 'REQ-110-020', 'REQ-110-021', 'REQ-110-127']) · Line 943
Consume WorkspaceEditPlan from SPEC-109, apply LSP edits as byte splices.
| Attribute | Type | Default |
|---|---|---|
parallelism |
Literal['serial', 'per_file'] |
'serial' |
| Method | Signature | Summary |
|---|---|---|
__init__ |
__init__(plan: Any) -> None |
Initialize rename symbol pass. |
apply |
apply(ws: Any) -> ChangeSet |
Apply LSP text edits from SPEC-109 plan. |
apply_file |
apply_file(path: str, tree: LosslessModule, ws: Any) -> ChangeEntry | None |
Apply LSP edits to a single file (not used for serial pass). |
_apply_edits |
_apply_edits(path: str, tree: LosslessModule, edits: Sequence[Any]) -> ChangeEntry | None |
Splice a file's SPEC-109 TextEdits directly over its bytes. |
Functions
| Function | Signature | Summary |
|---|---|---|
_parse_string_token traces |
_parse_string_token(text: bytes) -> tuple[bytes, bytes, str] |
Split a STRING token's bytes into (prefix, quote_bytes, raw_content_str). |
_is_simple_string_literal traces |
_is_simple_string_literal(stream: TokenStream, span: Token) -> bool |
True if span covers exactly one STRING token. |
_fits_between_quotes |
_fits_between_quotes(prefix: bytes, quote: bytes, content: str) -> bool |
True if content makes a valid literal between prefix and quote. |
_rewrite_literal |
_rewrite_literal(prefix: bytes, quote: bytes, content: str) -> bytes | None |
The literal with content between its own prefix and quotes, or None. |
_replace_string_literals traces |
_replace_string_literals(module: LosslessModule, old: str, new: str, regex: bool) -> LosslessModule | None |
Replace matching string/bytes literals in exact or regex mode. |
_extract_dotted_name |
_extract_dotted_name(node: ast.expr) -> str |
Extract a dotted name from an ast Name/Attribute chain. |
_classify_import |
_classify_import(module_name: str) -> str |
Classify import as stdlib, third-party, or local. |
_docstring_nodes |
_docstring_nodes(tree: ast.Module) -> set[int] |
id of every docstring constant in tree (ast.get_docstring's rule). |
_sweep_docstrings_and_comments |
_sweep_docstrings_and_comments(module: LosslessModule, replacements: dict[str, str]) -> LosslessModule | None |
Replace vocabulary in docstrings AND comments. |
Source
"""SPEC-110 codemod engine — built-in transform passes.
Five composable transform passes that mutate the token/ast forest in-memory
via byte-span edits over the ctok lossless CST layer (P3 cutover from
LibCST, ``plans/contracts/ctok-parser.contract.json``):
- ReplaceStringLiteralPass: Exact and regex string replacement
- AddImportPass: Add import statements to modules
- RemoveUnusedImportPass: Remove unreferenced imports via CIG
- DocstringSweepPass: Vocabulary replacement in docstrings and comments
- RenameSymbolPass: Consume SPEC-109 WorkspaceEditPlan, apply as ctok
EditBuffer byte-splice edits
"""
from __future__ import annotations
import ast
import fnmatch
import logging
import re
import warnings
from collections.abc import Sequence
from dataclasses import dataclass
from typing import Any, Literal
from orchestrata_ultimate.core.base.traces import traces
from orchestrata_ultimate.refactor.codemod.report import ChangeEntry, ChangeSet
from orchestrata_ultimate.refactor.ctok import (
EditBuffer,
LosslessModule,
NodeSpanError,
Token,
TokenKind,
TokenStream,
verify_edit,
)
logger = logging.getLogger(__name__)
__all__ = [
"TransformPass",
"ReplaceStringLiteralPass",
"AddImportPass",
"RemoveUnusedImportPass",
"DocstringSweepPass",
"RenameSymbolPass",
]
@traces(spec="110", story="US-110-003", reqs=["REQ-110-011"])
class TransformPass:
"""Abstract base class for transform passes.
All transform passes must implement apply() which takes a workspace
and returns a ChangeSet of mutated trees.
"""
name: str = "TransformPass"
parallelism: Literal["serial", "per_file"] = "serial"
def apply(self, ws: Any) -> ChangeSet:
"""Apply the transform pass to the workspace.
Args:
ws: CodemodWorkspace instance.
Returns:
ChangeSet containing all mutations.
"""
raise NotImplementedError("Subclasses must implement apply()")
def apply_file(
self, path: str, tree: LosslessModule, ws: Any
) -> ChangeEntry | None:
"""Apply the transform to a single file (for per_file parallelism).
Args:
path: Repo-relative file path.
tree: Parsed LosslessModule.
ws: CodemodWorkspace instance.
Returns:
ChangeEntry if mutated, None if unchanged.
"""
raise NotImplementedError("Subclasses must implement apply_file()")
# ============================================================================
# String-literal helpers (span-splice) — shared by ReplaceStringLiteralPass
# and DocstringSweepPass.
# ============================================================================
_STRING_PREFIX_RE = re.compile(rb"[A-Za-z]*")
@traces(spec="110", story="US-110-002", reqs=["REQ-110-010"])
def _parse_string_token(text: bytes) -> tuple[bytes, bytes, str]:
"""Split a STRING token's bytes into (prefix, quote_bytes, raw_content_str).
Mirrors LibCST's ``SimpleString.prefix``/``.quote``/``.raw_value``: the
string prefix (r/b/u — f-strings are a distinct ast node type and never
reach here), the quote delimiter (possibly triple) and the un-escaped
literal content between the quotes. A caller that rewrites the literal
writes ``prefix + quote + new_content + quote`` to keep the literal's
kind (a raw docstring stays raw).
Args:
text: The raw source bytes of one STRING token, prefix included.
Returns:
``(prefix, quote, content)`` — ``prefix`` is the (possibly empty)
letters before the opening quote; ``quote`` is the opening/closing
delimiter bytes (single or double, plain or triple-quoted);
``content`` is the literal text between the quotes, decoded as UTF-8
(not unescaped).
"""
prefix_len = _STRING_PREFIX_RE.match(text).end() # type: ignore[union-attr]
prefix = text[:prefix_len]
body = text[prefix_len:]
quote = body[:3] if body[:3] in (b'"""', b"'''") else body[:1]
content = body[len(quote) : -len(quote)]
return prefix, quote, content.decode("utf-8")
@traces(spec="110", story="US-110-002", reqs=["REQ-110-010"])
def _is_simple_string_literal(stream: TokenStream, span: Token) -> bool:
"""True if ``span`` covers exactly one STRING token.
An implicitly-concatenated string literal (``"a" "b"``) collapses to a
SINGLE ``ast.Constant`` node spanning both segments, but is backed by
TWO STRING tokens. The pre-port LibCST version left concatenated
strings untouched (``leave_ConcatenatedString`` was a no-op) — this
detects that shape so the port preserves the same skip.
Args:
stream: The module's TokenStream.
span: The candidate literal's token span (from ``NodeIndex.span_for``).
Returns:
True only if ``span`` is backed by exactly one STRING token.
"""
count = 0
for token in stream.tokens:
if token.start >= span.end:
break
if token.start >= span.start and token.kind is TokenKind.STRING:
count += 1
if count > 1:
return False
return count == 1
def _fits_between_quotes(prefix: bytes, quote: bytes, content: str) -> bool:
"""True if *content* makes a valid literal between *prefix* and *quote*.
False when the content holds the delimiter character unescaped (for a
triple-quoted literal: three in a row, or one at the very end, where it
would merge with the closing delimiter), ends with an odd run of
backslashes (which would escape the closing delimiter), for a
non-triple-quoted literal holds a raw newline (invalid source), or when
``ast.literal_eval`` refuses the assembled literal (a malformed escape
such as ``\\N``, ``\\x`` or ``\\u12``, or a NUL).
"""
delimiter = chr(quote[0])
triple = len(quote) == 3
if not triple and ("\n" in content or "\r" in content):
return False
backslashes = 0 # the run of backslashes just before the next character
delimiters = 0 # the run of unescaped delimiter characters just seen
for char in content:
if char == "\\":
backslashes += 1
delimiters = 0
continue
escaped = backslashes % 2 == 1
backslashes = 0
if char != delimiter or escaped:
delimiters = 0
continue
if not triple:
return False
delimiters += 1
if delimiters == 3:
return False
if backslashes % 2 or (triple and delimiters):
return False
# The fast paths above catch the delimiter, newline and backslash rules;
# the interpreter has the last word on escapes (``\N``, ``\x``, ``\u12``)
# and on NUL, which no scan of the characters alone gets right.
literal = (prefix + quote).decode("ascii") + content + quote.decode("ascii")
try:
with warnings.catch_warnings():
warnings.simplefilter("ignore") # ``\d`` is valid, merely deprecated
ast.literal_eval(literal)
except SyntaxError, ValueError:
return False
return True
def _rewrite_literal(prefix: bytes, quote: bytes, content: str) -> bytes | None:
"""The literal with *content* between its own prefix and quotes, or None.
None leaves the literal as it is: the content cannot sit between those
quotes (``_fits_between_quotes``), or the literal is a bytes literal and
the content is not ASCII (``b"é"`` is not valid source).
"""
if b"b" in prefix.lower() and not content.isascii():
return None
if not _fits_between_quotes(prefix, quote, content):
return None
return prefix + quote + content.encode("utf-8") + quote
@traces(spec="110", story="US-110-002", reqs=["REQ-110-010"])
def _replace_string_literals(
module: LosslessModule, old: str, new: str, regex: bool
) -> LosslessModule | None:
"""Replace matching string/bytes literals in exact or regex mode.
Args:
module: The LosslessModule to search.
old: String or regex pattern to match against a literal's raw content.
new: Replacement text.
regex: If True, treat ``old`` as a regex pattern.
Returns:
A new LosslessModule with the replacements applied, or None if
nothing matched.
"""
pattern = re.compile(old) if regex else None
edits = EditBuffer()
changed = False
for node in ast.walk(module.tree):
if not (
isinstance(node, ast.Constant) and isinstance(node.value, (str, bytes))
):
continue
try:
span = module.index.span_for(node)
except NodeSpanError:
continue
if not _is_simple_string_literal(module.stream, span):
continue
text = module.stream.slice(span.start, span.end)
prefix, quote, raw_value = _parse_string_token(text)
if regex:
if not (pattern and pattern.search(raw_value)):
continue
new_value = pattern.sub(new, raw_value)
else:
if raw_value != old:
continue
new_value = new
rewritten = _rewrite_literal(prefix, quote, new_value)
if rewritten is None:
continue
edits.add(span.start, span.end, rewritten)
changed = True
if not changed:
return None
return module.apply(edits)
@traces(spec="110", story="US-110-002", reqs=["REQ-110-010"])
class ReplaceStringLiteralPass(TransformPass):
"""Replace string literals in exact or regex mode with keep-pattern guard."""
name = "ReplaceStringLiteralPass"
parallelism: Literal["serial", "per_file"] = "per_file"
def __init__(
self,
old: str,
new: str,
regex: bool = False,
keep_patterns: Sequence[str] = (),
) -> None:
"""Initialize string literal replacement pass.
Args:
old: String or regex pattern to match.
new: Replacement string.
regex: If True, treat old as regex pattern.
keep_patterns: Glob patterns for files to skip.
"""
self._old = old
self._new = new
self._regex = regex
self._keep_patterns = tuple(keep_patterns)
@traces(spec="110", story="US-110-002", reqs=["REQ-110-010"])
def apply(self, ws: Any) -> ChangeSet:
"""Apply string replacement across all files in workspace.
Args:
ws: CodemodWorkspace instance.
Returns:
ChangeSet with all mutated files.
"""
entries: list[ChangeEntry] = []
for path, tree in ws.forest.items():
entry = self.apply_file(path, tree, ws)
if entry is not None:
entries.append(entry)
return ChangeSet(entries=tuple(entries))
@traces(spec="110", story="US-110-002", reqs=["REQ-110-010"])
def apply_file(
self, path: str, tree: LosslessModule, ws: Any
) -> ChangeEntry | None:
"""Replace string literals in one file.
Args:
path: Repo-relative file path.
tree: Parsed LosslessModule.
ws: CodemodWorkspace instance.
Returns:
ChangeEntry if mutated, None if unchanged or skipped.
"""
if any(fnmatch.fnmatch(path, pat) for pat in self._keep_patterns):
return None
mutated_tree = _replace_string_literals(tree, self._old, self._new, self._regex)
if mutated_tree is None:
return None
return ChangeEntry(
path=path,
original_tree=tree,
mutated_tree=mutated_tree,
pass_name=self.name,
description=f"Replaced '{self._old}' with '{self._new}'",
)
class _ImportExistsVisitor(ast.NodeVisitor):
"""Check if an import already exists in the module."""
def __init__(self, module: str, name: str | None) -> None:
self._module = module
self._name = name
self.exists = False
def visit_ImportFrom(self, node: ast.ImportFrom) -> None:
"""Check from-import statements."""
if any(alias.name == "*" for alias in node.names):
return
module_name = node.module or ""
if module_name != self._module:
return
if self._name is None:
return
for alias in node.names:
if alias.name == self._name:
self.exists = True
return
def visit_Import(self, node: ast.Import) -> None:
"""Check import statements."""
if self._name is not None:
return
for alias in node.names:
if alias.name == self._module:
self.exists = True
return
def _extract_dotted_name(node: ast.expr) -> str:
"""Extract a dotted name from an ast Name/Attribute chain.
``ast`` already flattens import module/alias names to plain strings, so
this file no longer needs this for import processing the way the
pre-port LibCST version did (CST represented dotted module paths as
nested ``Attribute``/``Name`` chains) — kept, and directly tested, as a
general-purpose dotted-name resolver for other Name/Attribute
expression chains.
Args:
node: An ``ast.Name``, ``ast.Attribute``, or other expression.
Returns:
The dotted-name string, or "" if ``node`` is neither a Name nor an
Attribute chain rooted in one.
"""
if isinstance(node, ast.Name):
return node.id
if isinstance(node, ast.Attribute):
left = _extract_dotted_name(node.value)
return f"{left}.{node.attr}" if left else node.attr
return ""
def _classify_import(module_name: str) -> str:
"""Classify import as stdlib, third-party, or local.
Args:
module_name: Dotted module name.
Returns:
One of 'stdlib', 'third_party', or 'local'.
"""
stdlib_prefixes = (
"abc",
"argparse",
"array",
"ast",
"asyncio",
"base64",
"builtins",
"collections",
"concurrent",
"contextlib",
"copy",
"dataclasses",
"datetime",
"enum",
"fnmatch",
"functools",
"gc",
"hashlib",
"importlib",
"inspect",
"io",
"itertools",
"json",
"logging",
"math",
"os",
"pathlib",
"pickle",
"platform",
"pprint",
"queue",
"random",
"re",
"shutil",
"signal",
"socket",
"string",
"struct",
"subprocess",
"sys",
"tempfile",
"textwrap",
"threading",
"time",
"traceback",
"typing",
"unittest",
"uuid",
"warnings",
"weakref",
"xml",
"zipfile",
)
top_level = module_name.split(".")[0]
if top_level in stdlib_prefixes:
return "stdlib"
if module_name.startswith("orchestrata_ultimate") or module_name.startswith("."):
return "local"
return "third_party"
@traces(spec="110", story="US-110-007", reqs=["REQ-110-010"])
class AddImportPass(TransformPass):
"""Add import statement to target modules."""
name = "AddImportPass"
parallelism: Literal["serial", "per_file"] = "per_file"
def __init__(
self, module: str, name: str | None = None, alias: str | None = None
) -> None:
"""Initialize import addition pass.
Args:
module: Module to import from (e.g., 'typing').
name: Name to import (e.g., 'Optional'), or None for whole module.
alias: Optional alias (e.g., 'opt' for 'Optional as opt').
"""
self._module = module
self._name = name
self._alias = alias
def apply(self, ws: Any) -> ChangeSet:
"""Add import to all files in workspace.
Args:
ws: CodemodWorkspace instance.
Returns:
ChangeSet with all mutated files.
"""
entries: list[ChangeEntry] = []
for path, tree in ws.forest.items():
entry = self.apply_file(path, tree, ws)
if entry is not None:
entries.append(entry)
return ChangeSet(entries=tuple(entries))
def apply_file(
self, path: str, tree: LosslessModule, ws: Any
) -> ChangeEntry | None:
"""Add import to one file.
Args:
path: Repo-relative file path.
tree: Parsed LosslessModule.
ws: CodemodWorkspace instance.
Returns:
ChangeEntry if mutated, None if import already exists.
"""
visitor = _ImportExistsVisitor(self._module, self._name)
visitor.visit(tree.tree)
if visitor.exists:
return None
mutated_tree = self._add_import(tree)
return ChangeEntry(
path=path,
original_tree=tree,
mutated_tree=mutated_tree,
pass_name=self.name,
description=f"Added import: {self._format_import()}",
)
def _format_import(self) -> str:
"""Format the import statement for description."""
if self._name:
base = f"from {self._module} import {self._name}"
if self._alias:
base += f" as {self._alias}"
return base
return f"import {self._module}"
def _add_import(self, module: LosslessModule) -> LosslessModule:
"""Add import statement to module in correct group.
Args:
module: Original LosslessModule.
Returns:
Mutated LosslessModule with the new import spliced in as a
zero-width EditBuffer insertion at the computed byte offset.
"""
import_group = _classify_import(self._module)
body = module.tree.body
insert_idx = self._find_insert_position(body, import_group)
offset = (
module.index.span_for(body[insert_idx]).start
if insert_idx < len(body)
else len(module.code)
)
prefix = (
b"" if offset == 0 or module.code[offset - 1 : offset] == b"\n" else b"\n"
)
new_text = prefix + self._format_import().encode("utf-8") + b"\n"
edits = EditBuffer()
edits.add(offset, offset, new_text)
return module.apply(edits)
def _find_insert_position(self, body: Sequence[ast.stmt], import_group: str) -> int:
"""Find position to insert import based on group ordering.
Args:
body: Module top-level statements.
import_group: One of 'stdlib', 'third_party', or 'local'.
Returns:
Index into ``body`` where the new import should be inserted.
"""
group_order = {"stdlib": 0, "third_party": 1, "local": 2}
target_order = group_order[import_group]
last_import_idx = -1
last_group_idx = -1
for i, stmt in enumerate(body):
if isinstance(stmt, ast.Import):
last_import_idx = i
for alias in stmt.names:
if alias.name:
stmt_group = _classify_import(alias.name)
if group_order[stmt_group] <= target_order:
last_group_idx = i
elif isinstance(stmt, ast.ImportFrom):
last_import_idx = i
if stmt.module:
stmt_group = _classify_import(stmt.module)
if group_order[stmt_group] <= target_order:
last_group_idx = i
if last_import_idx == -1:
return 0
if last_group_idx >= 0:
return last_group_idx + 1
return last_import_idx + 1
class _NameCollector(ast.NodeVisitor):
"""Collect all Name nodes in the module body (excluding imports)."""
def __init__(self) -> None:
self.names: set[str] = set()
def visit_Import(self, node: ast.Import) -> None:
"""Skip import statements -- they carry no Name child nodes to collect."""
def visit_ImportFrom(self, node: ast.ImportFrom) -> None:
"""Skip from-import statements -- they carry no Name child nodes to collect."""
def visit_Name(self, node: ast.Name) -> None:
self.names.add(node.id)
@dataclass(slots=True)
class _ImportBinding:
"""One imported alias, tracked separately from its sibling aliases.
Finding 3 fix: the pre-port version recorded ``(module_name,
imported_name, node)`` per alias but ``node`` was always the WHOLE
import statement, so ``RemoveUnusedImportPass`` deleted every alias on
a statement the moment even ONE was unused (``import os, sys`` with
only ``os`` unused silently deleted ``sys`` too — same for
``from x import a, b``). Carrying the ``alias`` node itself lets
removal target exactly the unused alias's own byte span, keeping used
siblings intact.
"""
module_name: str
imported_name: str | None
stmt: ast.Import | ast.ImportFrom
alias: ast.alias
class _ImportExtractor(ast.NodeVisitor):
"""Extract imported names from a module, per alias (Finding 3 fix)."""
def __init__(self) -> None:
self.imports: list[_ImportBinding] = []
def visit_Import(self, node: ast.Import) -> None:
for alias in node.names:
if alias.name == "*":
continue
self.imports.append(_ImportBinding(alias.name, None, node, alias))
def visit_ImportFrom(self, node: ast.ImportFrom) -> None:
module_name = node.module or ""
for alias in node.names:
if alias.name == "*":
continue
self.imports.append(_ImportBinding(module_name, alias.name, node, alias))
@traces(spec="110", story="US-110-007", reqs=["REQ-110-010"])
class RemoveUnusedImportPass(TransformPass):
"""Remove imports not referenced in module body."""
name = "RemoveUnusedImportPass"
parallelism: Literal["serial", "per_file"] = "per_file"
def apply(self, ws: Any) -> ChangeSet:
"""Remove unused imports from all files.
Args:
ws: CodemodWorkspace instance.
Returns:
ChangeSet with all mutated files.
"""
entries: list[ChangeEntry] = []
for path, tree in ws.forest.items():
entry = self.apply_file(path, tree, ws)
if entry is not None:
entries.append(entry)
return ChangeSet(entries=tuple(entries))
def apply_file(
self, path: str, tree: LosslessModule, ws: Any
) -> ChangeEntry | None:
"""Remove unused imports from one file.
Args:
path: Repo-relative file path.
tree: Parsed LosslessModule.
ws: CodemodWorkspace instance.
Returns:
ChangeEntry if mutated, None if no unused imports.
"""
name_collector = _NameCollector()
name_collector.visit(tree.tree)
used_names = name_collector.names
import_extractor = _ImportExtractor()
import_extractor.visit(tree.tree)
unused: list[_ImportBinding] = []
for binding in import_extractor.imports:
if binding.imported_name:
if binding.imported_name not in used_names:
unused.append(binding)
else:
top_level = binding.module_name.split(".")[0]
if top_level not in used_names:
unused.append(binding)
if not unused:
return None
mutated_tree = self._remove_imports(tree, unused)
return ChangeEntry(
path=path,
original_tree=tree,
mutated_tree=mutated_tree,
pass_name=self.name,
description=f"Removed {len(unused)} unused imports",
)
def _remove_imports(
self, module: LosslessModule, unused: list[_ImportBinding]
) -> LosslessModule:
"""Remove unused import aliases, statement-by-statement.
A statement whose EVERY alias is unused is deleted whole (including
its trailing newline, by splicing up to the byte offset of the next
top-level statement, or end-of-file). A statement with only SOME
unused aliases keeps its used siblings and splices out just the
unused alias's own text plus its separating comma (Finding 3 fix —
the pre-port version deleted the whole statement in this case).
Note: matches the pre-port scope of "top-level only" — only
statements that appear directly in ``module.tree.body`` are ever
removed, even though ``_ImportExtractor`` (mirroring the original
CST visitor) walks the whole tree and so may report unused imports
nested inside functions/classes; those are counted but never
structurally removed, identical to the pre-port behaviour.
Args:
module: Original LosslessModule.
unused: The unused per-alias bindings to remove.
Returns:
Mutated LosslessModule with the unused imports removed.
"""
unused_by_stmt: dict[int, list[ast.alias]] = {}
for binding in unused:
unused_by_stmt.setdefault(id(binding.stmt), []).append(binding.alias)
body = module.tree.body
edits = EditBuffer()
for i, stmt in enumerate(body):
stmt_unused = unused_by_stmt.get(id(stmt))
if not stmt_unused or not isinstance(stmt, (ast.Import, ast.ImportFrom)):
continue
if len(stmt_unused) >= len(stmt.names):
start = module.index.span_for(stmt).start
end = (
module.index.span_for(body[i + 1]).start
if i + 1 < len(body)
else len(module.code)
)
edits.add(start, end, b"")
continue
alias_spans = [module.index.span_for(a) for a in stmt.names]
unused_ids = {id(a) for a in stmt_unused}
for idx, alias in enumerate(stmt.names):
if id(alias) not in unused_ids:
continue
if idx < len(stmt.names) - 1:
del_start, del_end = (
alias_spans[idx].start,
alias_spans[idx + 1].start,
)
else:
del_start, del_end = alias_spans[idx - 1].end, alias_spans[idx].end
edits.add(del_start, del_end, b"")
return module.apply(edits)
def _docstring_nodes(tree: ast.Module) -> set[int]:
"""``id`` of every docstring constant in ``tree`` (``ast.get_docstring``'s rule).
A docstring is the first statement of a module, class or function body
when that statement is a bare ``str`` constant; ``bytes`` never is one.
"""
nodes: set[int] = set()
for owner in ast.walk(tree):
if not isinstance(
owner, (ast.Module, ast.ClassDef, ast.FunctionDef, ast.AsyncFunctionDef)
):
continue
first = owner.body[0] if owner.body else None
if (
isinstance(first, ast.Expr)
and isinstance(first.value, ast.Constant)
and isinstance(first.value.value, str)
):
nodes.add(id(first.value))
return nodes
def _sweep_docstrings_and_comments(
module: LosslessModule, replacements: dict[str, str]
) -> LosslessModule | None:
"""Replace vocabulary in docstrings AND comments.
Only a docstring is rewritten among the string literals: a string that is
code (an assignment value, a dict key, a call argument, a ``return``
value, an ``__all__`` entry) changes behaviour when its text changes, so
the sweep leaves it alone. The string prefix survives the rewrite (a raw
docstring stays raw).
Args:
module: The LosslessModule to sweep.
replacements: Mapping of old text to new text.
Returns:
A new LosslessModule with the replacements applied, or None if
nothing matched.
"""
edits = EditBuffer()
changed = False
docstrings = _docstring_nodes(module.tree)
for node in ast.walk(module.tree):
if not (isinstance(node, ast.Constant) and id(node) in docstrings):
continue
try:
span = module.index.span_for(node)
except NodeSpanError:
continue
if not _is_simple_string_literal(module.stream, span):
continue
text = module.stream.slice(span.start, span.end)
prefix, quote, raw_value = _parse_string_token(text)
new_value = raw_value
for old, new in replacements.items():
new_value = new_value.replace(old, new)
if new_value != raw_value:
rewritten = _rewrite_literal(prefix, quote, new_value)
if rewritten is not None:
edits.add(span.start, span.end, rewritten)
changed = True
for token in module.stream.tokens:
if token.kind is not TokenKind.COMMENT:
continue
comment_text = token.text(module.stream.source).decode("utf-8")
new_comment_text = comment_text
for old, new in replacements.items():
new_comment_text = new_comment_text.replace(old, new)
if new_comment_text != comment_text:
edits.add(token.start, token.end, new_comment_text.encode("utf-8"))
changed = True
if not changed:
return None
return module.apply(edits)
@traces(spec="110", story="US-110-002", reqs=["REQ-110-010"])
class DocstringSweepPass(TransformPass):
"""Vocabulary replacement in docstrings AND comments (REQ-110-010).
Only docstrings and comments change; a string literal that is code stays
as it is, so a sweep never alters what a program does.
"""
name = "DocstringSweepPass"
parallelism: Literal["serial", "per_file"] = "per_file"
def __init__(self, replacements: dict[str, str]) -> None:
"""Initialize docstring sweep pass.
Args:
replacements: Mapping of old text to new text.
"""
self._replacements = replacements
def apply(self, ws: Any) -> ChangeSet:
"""Apply vocabulary replacements across all files.
Args:
ws: CodemodWorkspace instance.
Returns:
ChangeSet with all mutated files.
"""
entries: list[ChangeEntry] = []
for path, tree in ws.forest.items():
entry = self.apply_file(path, tree, ws)
if entry is not None:
entries.append(entry)
return ChangeSet(entries=tuple(entries))
def apply_file(
self, path: str, tree: LosslessModule, ws: Any
) -> ChangeEntry | None:
"""Replace vocabulary in docstrings and comments of one file.
Args:
path: Repo-relative file path.
tree: Parsed LosslessModule.
ws: CodemodWorkspace instance.
Returns:
ChangeEntry if mutated, None if unchanged.
"""
mutated_tree = _sweep_docstrings_and_comments(tree, self._replacements)
if mutated_tree is None:
return None
return ChangeEntry(
path=path,
original_tree=tree,
mutated_tree=mutated_tree,
pass_name=self.name,
description=f"Swept {len(self._replacements)} vocabulary replacements",
)
@traces(
spec="110",
story="US-110-009",
reqs=["REQ-110-010", "REQ-110-020", "REQ-110-021", "REQ-110-127"],
)
class RenameSymbolPass(TransformPass):
"""Consume WorkspaceEditPlan from SPEC-109, apply LSP edits as byte splices.
Applies SPEC-109 ``TextEdit`` line/col ranges directly via ``EditBuffer``
byte splices, resolving each edit's ``(line, start_col)``/``(line,
end_col)`` to absolute byte offsets through ``NodeIndex.line_starts`` --
no tree-walk-and-match against ast Name/Attribute nodes (the deleted
``_LSPToCSTTransformer`` did that; the token/ast model resolves the
range directly, per the ctok-parser contract §5). Every splice is
guarded by ``verify_edit(expect_equivalent=False)`` (REQ-110-127): a
rename must change ONLY identifier fields, never anything else.
"""
name = "RenameSymbolPass"
parallelism: Literal["serial", "per_file"] = "serial"
def __init__(self, plan: Any) -> None:
"""Initialize rename symbol pass.
Args:
plan: WorkspaceEditPlan from SPEC-109's SymbolRenamer.
"""
self._plan = plan
@traces(spec="110", story="US-110-009", reqs=["REQ-110-020", "REQ-110-127"])
def apply(self, ws: Any) -> ChangeSet:
"""Apply LSP text edits from SPEC-109 plan.
Args:
ws: CodemodWorkspace instance.
Returns:
ChangeSet with all mutated files.
"""
entries: list[ChangeEntry] = []
for file_edit in self._plan.files:
path = str(file_edit.path.relative_to(ws.root))
if path not in ws.forest:
logger.warning("File not in forest: %s", path)
continue
entry = self._apply_edits(path, ws.forest[path], file_edit.edits)
if entry is not None:
entries.append(entry)
return ChangeSet(entries=tuple(entries))
def apply_file(
self, path: str, tree: LosslessModule, ws: Any
) -> ChangeEntry | None:
"""Apply LSP edits to a single file (not used for serial pass).
Args:
path: Repo-relative file path.
tree: Parsed LosslessModule.
ws: CodemodWorkspace instance.
Returns:
ChangeEntry if mutated, None if unchanged.
"""
for file_edit in self._plan.files:
edit_path = str(file_edit.path.relative_to(ws.root))
if edit_path == path:
return self._apply_edits(path, tree, file_edit.edits)
return None
@traces(spec="110", story="US-110-009", reqs=["REQ-110-020", "REQ-110-127"])
def _apply_edits(
self, path: str, tree: LosslessModule, edits: Sequence[Any]
) -> ChangeEntry | None:
"""Splice a file's SPEC-109 TextEdits directly over its bytes.
Args:
path: Repo-relative file path.
tree: Parsed LosslessModule for ``path``.
edits: SPEC-109 ``TextEdit`` sequence (0-based line, byte
columns, ``end_col`` exclusive) for this file.
Returns:
ChangeEntry if the edits changed the file's bytes, else None.
Raises:
EditSafetyError: an edit changed more than the renamed
identifier(s) (REQ-110-127).
"""
if not edits:
return None
edit_buffer = EditBuffer()
for edit in edits:
start = tree.index.line_starts[edit.line] + edit.start_col
end = tree.index.line_starts[edit.line] + edit.end_col
edit_buffer.add(start, end, edit.new_text.encode("utf-8"))
original_code = tree.code
new_bytes = edit_buffer.apply(original_code)
if new_bytes == original_code:
return None
verify_edit(original_code, new_bytes, expect_equivalent=False)
mutated_tree = LosslessModule.parse(new_bytes)
return ChangeEntry(
path=path,
original_tree=tree,
mutated_tree=mutated_tree,
pass_name=self.name,
description=f"Applied {len(edits)} LSP edits",
)