orchestrata_ultimate.harness.runner
Reference › orchestrata_ultimate › harness › runner
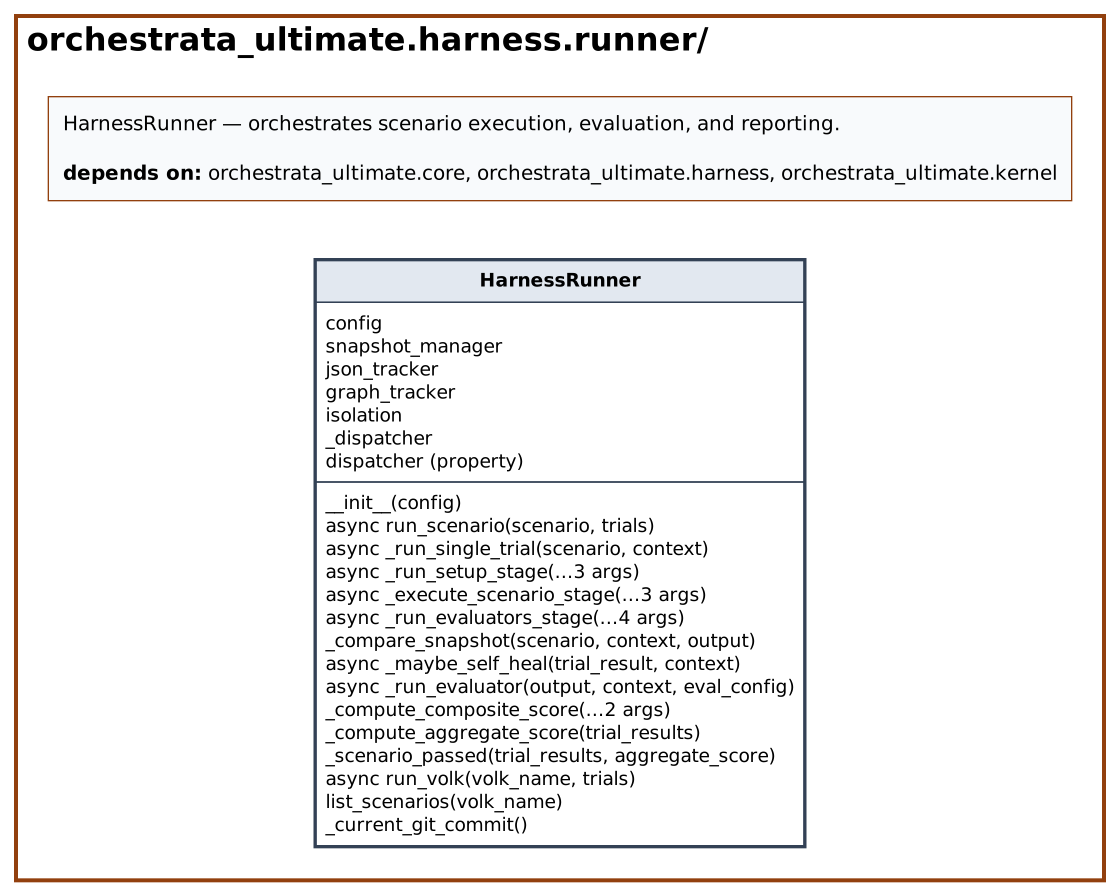
HarnessRunner is the main entry point for executing volk test scenarios (SPEC-102); the cli builds one and calls it. The constructor creates a SnapshotManager, a JSONHistoryTracker, a WorktreeIsolation and, when possible, a GraphHistoryTracker; a graph failure is logged and the runner continues without graph history. The CXP dispatcher is created lazily on first use.
run_scenario(scenario, trials=3) loops over the trials. For each it mints a test_id, creates the isolation, assembles a HarnessContext with isolated Redis database and graph prefix, runs _run_single_trial, and always cleans up. A trial runs a setup stage (the setup hook), an execution stage with the executor chosen by the scenario mode, and an evaluator stage that runs the configured evaluators concurrently. Failures at any stage become a failed TrialResult with an error message instead of an exception. The composite score is the weighted average of evaluator scores (_compute_composite_score); a trial passes when the composite is at least 0.8, every evaluator passed and the output matches its snapshot. A failed trial may go to the self-healing loop. A scenario passes only if all trials pass and the aggregate score is at least 0.8. The ScenarioResult carries the git commit and is recorded in the history trackers.
At a glance
| Source | src/orchestrata_ultimate/harness/runner.py |
| Lines of code | 480 |
| Classes | 1 |
| Functions | 0 |
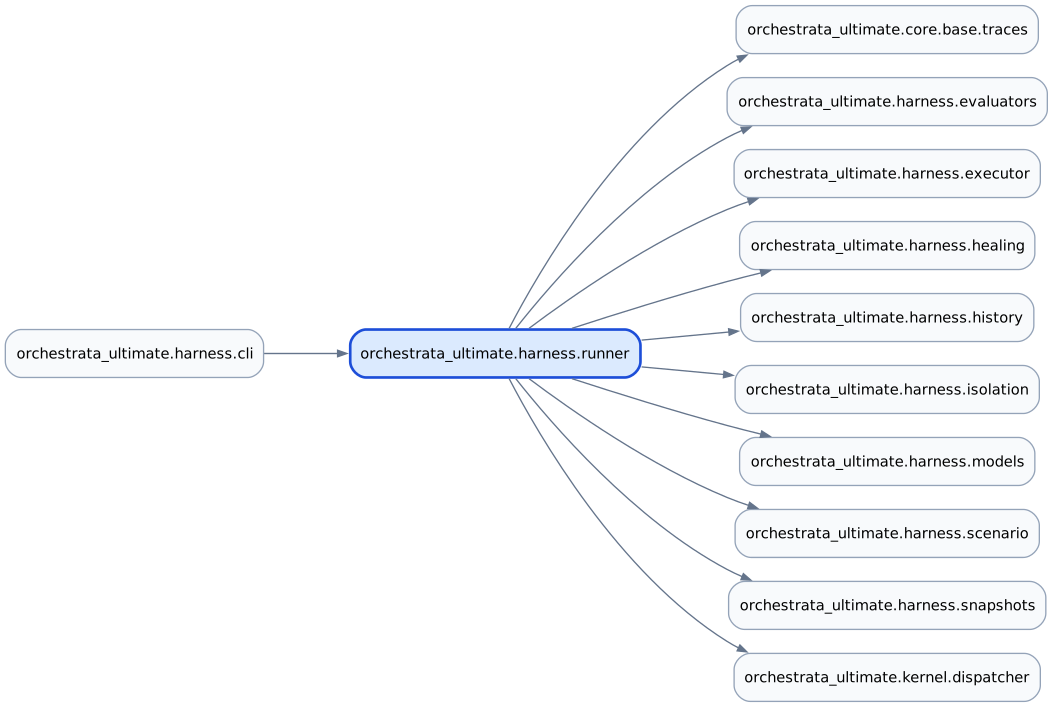
| Imports (internal) | orchestrata_ultimate.core.base.traces, orchestrata_ultimate.harness.evaluators, orchestrata_ultimate.harness.executor, orchestrata_ultimate.harness.healing, orchestrata_ultimate.harness.history, orchestrata_ultimate.harness.isolation, orchestrata_ultimate.harness.models, orchestrata_ultimate.harness.scenario, orchestrata_ultimate.harness.snapshots, orchestrata_ultimate.kernel.dispatcher |
| Imported by | orchestrata_ultimate.harness.cli |
| Tests that import it | tests/harness/test_runner.py |
Class diagram
Dependency diagram
API
Constants
| Name | Type | Value |
|---|---|---|
_COMPOSITE_PASS_THRESHOLD |
float |
0.8 |
Classes
HarnessRunner
Decorators: traces(spec='102', story='US-001', reqs=['REQ-102-007', 'REQ-102-015', 'REQ-102-019']) · Line 49
Main entry point for executing volk test scenarios.
| Method | Signature | Summary |
|---|---|---|
__init__ |
__init__(config: HarnessConfig) -> None |
|
dispatcher property |
dispatcher() -> MessageDispatcher |
Lazy-initialize the CXP message dispatcher. |
run_scenario |
async run_scenario(scenario: Scenario, trials: int = 3) -> ScenarioResult |
Run scenario for trials independent trials and aggregate results. |
_run_single_trial |
async _run_single_trial(scenario: Scenario, context: HarnessContext) -> TrialResult |
Execute a single trial and return its result. |
_run_setup_stage |
async _run_setup_stage(scenario: Scenario, context: HarnessContext, trial_start_ms: int) -> TrialResult | None |
Run the setup hook (if any). |
_execute_scenario_stage |
async _execute_scenario_stage(scenario: Scenario, context: HarnessContext, trial_start_ms: int) -> tuple[Any, TrialResult | None] |
Execute the scenario. |
_run_evaluators_stage |
async _run_evaluators_stage(scenario: Scenario, context: HarnessContext, output: Any, trial_start_ms: int) -> tuple[list[EvaluatorResult], TrialResult | None] |
Run evaluators concurrently. |
_compare_snapshot |
_compare_snapshot(scenario: Scenario, context: HarnessContext, output: Any) -> Any |
Compare output to the stored snapshot, saving a baseline if none exists. |
_maybe_self_heal |
async _maybe_self_heal(trial_result: TrialResult, context: HarnessContext) -> TrialResult |
Run the self-healing loop on a failed trial, returning the healed result. |
_run_evaluator staticmethod |
async _run_evaluator(output: Any, context: HarnessContext, eval_config: Any) -> EvaluatorResult |
Instantiate and run a single evaluator, catching any errors. |
_compute_composite_score staticmethod |
_compute_composite_score(evaluator_results: list[EvaluatorResult], scenario: Scenario) -> float |
Weighted average of evaluator scores. |
_compute_aggregate_score staticmethod |
_compute_aggregate_score(trial_results: list[TrialResult]) -> float |
Average composite score across all trials. |
_scenario_passed staticmethod |
_scenario_passed(trial_results: list[TrialResult], aggregate_score: float) -> bool |
Return True when all trials passed and aggregate score meets threshold. |
run_volk |
async run_volk(volk_name: str, trials: int = 3) -> list[ScenarioResult] |
Run all scenarios for a given volk and return their results. |
list_scenarios |
list_scenarios(volk_name: str | None = None) -> list[Scenario] |
List all loaded scenarios, optionally filtered by volk. |
_current_git_commit staticmethod |
_current_git_commit() -> str |
Return the current HEAD commit SHA, or empty string on failure. |
Source
"""HarnessRunner — orchestrates scenario execution, evaluation, and reporting."""

from __future__ import annotations

import asyncio
import logging
import subprocess
import time
import uuid
from pathlib import Path
from typing import Any

from orchestrata_ultimate.core.base.traces import traces
from orchestrata_ultimate.harness.evaluators import get_evaluator
from orchestrata_ultimate.harness.executor import (
    CXPacketExecutor,
    DirectCallExecutor,
    Executor,
)
from orchestrata_ultimate.harness.healing import SelfHealingLoop
from orchestrata_ultimate.harness.history import GraphHistoryTracker, JSONHistoryTracker
from orchestrata_ultimate.harness.isolation import (
    WorktreeIsolation,
    get_graph_prefix,
    get_redis_db_for_trial,
)
from orchestrata_ultimate.harness.models import (
    EvaluatorResult,
    HarnessConfig,
    HarnessContext,
    Scenario,
    ScenarioResult,
    TrialResult,
)
from orchestrata_ultimate.harness.scenario import (
    list_all_scenarios,
    load_scenarios_for_volk,
    run_setup_hook,
)
from orchestrata_ultimate.harness.snapshots import SnapshotManager
from orchestrata_ultimate.kernel.dispatcher import MessageDispatcher

_logger = logging.getLogger(__name__)

_COMPOSITE_PASS_THRESHOLD: float = 0.8


@traces(spec="102", story="US-001", reqs=["REQ-102-007", "REQ-102-015", "REQ-102-019"])
class HarnessRunner:
    """Main entry point for executing volk test scenarios."""

    def __init__(self, config: HarnessConfig) -> None:
        self.config = config
        self.snapshot_manager = SnapshotManager(config.snapshot_dir)
        self.json_tracker = JSONHistoryTracker(config.history_dir)
        self.graph_tracker: GraphHistoryTracker | None = None
        self.isolation = WorktreeIsolation()
        self._dispatcher: MessageDispatcher | None = None

        # Attempt graph tracker creation; failures are non-fatal.
        try:
            self.graph_tracker = GraphHistoryTracker(
                uri=config.graph_uri,
                username=config.graph_username,
                password=config.graph_password,
            )
        except Exception as exc:  # noqa: BLE001
            _logger.warning("Graph history tracker unavailable: %s", exc)

    @property
    @traces(spec="102", story="US-006", reqs=["REQ-102-096"])
    def dispatcher(self) -> MessageDispatcher:
        """Lazy-initialize the CXP message dispatcher."""
        if self._dispatcher is None:
            self._dispatcher = MessageDispatcher()
        return self._dispatcher

    @traces(
        spec="102",
        story="US-001",
        reqs=[
            "REQ-102-010",
            "REQ-102-011",
            "REQ-102-013",
            "REQ-102-027",
            "REQ-102-091",
        ],
    )
    async def run_scenario(self, scenario: Scenario, trials: int = 3) -> ScenarioResult:
        """Run *scenario* for *trials* independent trials and aggregate results.

        Steps per trial:
        1. Create worktree isolation.
        2. Run setup hook (if defined).
        3. Execute scenario (CXP or direct call).
        4. Run evaluators concurrently.
        5. Compute composite score and snapshot diff.
        6. Self-healing loop on failure (if enabled).
        7. Cleanup isolation.
        """
        git_commit = self._current_git_commit()
        trial_results: list[TrialResult] = []
        scenario_start_ms = int(time.time() * 1000)

        for trial_number in range(1, trials + 1):
            trial_start_ms = int(time.time() * 1000)
            test_id = uuid.uuid4().hex
            _logger.info(
                "Running trial %d/%d for scenario '%s' (test_id=%s)",
                trial_number,
                trials,
                scenario.id,
                test_id,
            )

            worktree_path = Path()
            try:
                worktree_path = await self.isolation.create(test_id)
            except Exception as exc:  # noqa: BLE001
                _logger.error(
                    "Failed to create isolation for trial %d: %s", trial_number, exc
                )
                trial_results.append(
                    TrialResult(
                        trial_number=trial_number,
                        passed=False,
                        error=f"Isolation creation failed: {exc}",
                        execution_time_ms=int(time.time() * 1000) - trial_start_ms,
                    )
                )
                continue

            context = HarnessContext(
                scenario_id=scenario.id,
                volk_name=scenario.volk,
                trial_number=trial_number,
                test_id=test_id,
                worktree_path=worktree_path,
                redis_db=get_redis_db_for_trial(trial_number - 1),
                graph_prefix=get_graph_prefix(test_id),
                config=self.config,
                logger=_logger,
            )

            try:
                trial_result = await self._run_single_trial(scenario, context)
            except Exception as exc:  # noqa: BLE001
                _logger.exception("Unexpected error in trial %d", trial_number)
                trial_result = TrialResult(
                    trial_number=trial_number,
                    passed=False,
                    error=f"Unexpected error: {exc}",
                    execution_time_ms=int(time.time() * 1000) - trial_start_ms,
                )
            finally:
                try:
                    await self.isolation.cleanup(test_id)
                except Exception as exc:  # noqa: BLE001
                    _logger.warning("Isolation cleanup failed for %s: %s", test_id, exc)

            trial_results.append(trial_result)

        aggregate_score = self._compute_aggregate_score(trial_results)
        passed = self._scenario_passed(trial_results, aggregate_score)
        execution_time_ms = int(time.time() * 1000) - scenario_start_ms

        result = ScenarioResult(
            scenario_id=scenario.id,
            volk_name=scenario.volk,
            trials=trial_results,
            aggregate_score=aggregate_score,
            passed=passed,
            execution_time_ms=execution_time_ms,
            git_commit=git_commit,
        )

        await self.json_tracker.record(result)
        if self.graph_tracker is not None:
            try:
                await self.graph_tracker.record(result)
            except Exception as exc:  # noqa: BLE001
                _logger.warning("graph history recording failed: %s", exc)

        return result

    @traces(
        spec="102",
        story="US-004",
        reqs=["REQ-102-054", "REQ-102-060", "REQ-102-078", "REQ-102-116"],
    )
    async def _run_single_trial(
        self, scenario: Scenario, context: HarnessContext
    ) -> TrialResult:
        """Execute a single trial and return its result."""
        trial_start_ms = int(time.time() * 1000)
        trial_number = context.trial_number

        setup_failure = await self._run_setup_stage(scenario, context, trial_start_ms)
        if setup_failure is not None:
            return setup_failure

        output, exec_failure = await self._execute_scenario_stage(
            scenario, context, trial_start_ms
        )
        if exec_failure is not None:
            return exec_failure

        evaluator_results, eval_failure = await self._run_evaluators_stage(
            scenario, context, output, trial_start_ms
        )
        if eval_failure is not None:
            return eval_failure

        # Compute composite score
        composite_score = self._compute_composite_score(evaluator_results, scenario)
        all_evaluators_passed = all(er.passed for er in evaluator_results)

        snapshot_diff = self._compare_snapshot(scenario, context, output)
        snapshot_regression = snapshot_diff is not None

        trial_passed = (
            composite_score >= _COMPOSITE_PASS_THRESHOLD
            and all_evaluators_passed
            and not snapshot_regression
        )

        trial_result = TrialResult(
            trial_number=trial_number,
            passed=trial_passed,
            evaluator_results=evaluator_results,
            snapshot_diff=snapshot_diff,
            execution_time_ms=int(time.time() * 1000) - trial_start_ms,
            error=None,
        )

        if not trial_passed:
            trial_result = await self._maybe_self_heal(trial_result, context)

        return trial_result

    @traces(spec="102", story="US-006", reqs=["REQ-102-089", "REQ-102-090"])
    async def _run_setup_stage(
        self, scenario: Scenario, context: HarnessContext, trial_start_ms: int
    ) -> TrialResult | None:
        """Run the setup hook (if any). Return a failed TrialResult on error, else None."""
        if not scenario.setup_hook:
            return None
        try:
            await asyncio.wait_for(
                run_setup_hook(scenario.setup_hook, context),
                timeout=self.config.setup_hook_timeout_seconds,
            )
            return None
        except TimeoutError:
            return TrialResult(
                trial_number=context.trial_number,
                passed=False,
                error=(
                    "Setup hook timed out after "
                    f"{self.config.setup_hook_timeout_seconds}s"
                ),
                execution_time_ms=int(time.time() * 1000) - trial_start_ms,
            )
        except Exception as exc:  # noqa: BLE001
            return TrialResult(
                trial_number=context.trial_number,
                passed=False,
                error=f"Setup hook failed: {exc}",
                execution_time_ms=int(time.time() * 1000) - trial_start_ms,
            )

    @traces(spec="102", story="US-001", reqs=["REQ-102-014", "REQ-102-116"])
    async def _execute_scenario_stage(
        self, scenario: Scenario, context: HarnessContext, trial_start_ms: int
    ) -> tuple[Any, TrialResult | None]:
        """Execute the scenario. Return (output, None) on success or (None, failure)."""
        try:
            executor: Executor
            if scenario.mode == "cxp_inject":
                executor = CXPacketExecutor(dispatcher=self.dispatcher)
            else:
                executor = DirectCallExecutor()

            output = await asyncio.wait_for(
                executor.execute(scenario, context),
                timeout=scenario.timeout_seconds,
            )
            return output, None
        except TimeoutError:
            return None, TrialResult(
                trial_number=context.trial_number,
                passed=False,
                error=f"Scenario timed out after {scenario.timeout_seconds}s",
                execution_time_ms=int(time.time() * 1000) - trial_start_ms,
            )
        except Exception as exc:  # noqa: BLE001
            return None, TrialResult(
                trial_number=context.trial_number,
                passed=False,
                error=f"Execution failed: {exc}",
                execution_time_ms=int(time.time() * 1000) - trial_start_ms,
            )

    @traces(spec="102", story="US-005", reqs=["REQ-102-068"])
    async def _run_evaluators_stage(
        self,
        scenario: Scenario,
        context: HarnessContext,
        output: Any,
        trial_start_ms: int,
    ) -> tuple[list[EvaluatorResult], TrialResult | None]:
        """Run evaluators concurrently. Return (results, None) or ([], failure)."""
        if not scenario.evaluation:
            return [], None
        try:
            eval_tasks = [
                self._run_evaluator(output, context, eval_config)
                for eval_config in scenario.evaluation
            ]
            return await asyncio.gather(*eval_tasks), None
        except Exception as exc:  # noqa: BLE001
            return [], TrialResult(
                trial_number=context.trial_number,
                passed=False,
                error=f"Evaluator execution failed: {exc}",
                execution_time_ms=int(time.time() * 1000) - trial_start_ms,
            )

    @traces(spec="102", story="US-004", reqs=["REQ-102-050", "REQ-102-053"])
    def _compare_snapshot(
        self, scenario: Scenario, context: HarnessContext, output: Any
    ) -> Any:
        """Compare *output* to the stored snapshot, saving a baseline if none exists."""
        snapshot_diff = self.snapshot_manager.compare(scenario.id, output)
        if snapshot_diff is None and not self.snapshot_manager.exists(scenario.id):
            # No baseline exists — save current output as baseline.
            # Bug fix: HarnessConfig never has a `git_commit` attribute (the
            # hasattr() guard always failed and silently saved "" baselines);
            # the real commit hash comes from _current_git_commit(), same as
            # run_scenario()'s ScenarioResult.git_commit.
            self.snapshot_manager.save(
                scenario.id,
                output,
                self._current_git_commit(),
            )
            snapshot_diff = None
        return snapshot_diff

    @traces(spec="102", story="US-003", reqs=["REQ-102-036"])
    async def _maybe_self_heal(
        self, trial_result: TrialResult, context: HarnessContext
    ) -> TrialResult:
        """Run the self-healing loop on a failed trial, returning the healed result."""
        if self.config.max_healing_hops <= 0:
            return trial_result
        healing_loop = SelfHealingLoop(
            dispatcher=self.dispatcher,
            max_hops=self.config.max_healing_hops,
        )
        try:
            healing_result = await healing_loop.heal(trial_result, context)
            if healing_result.success and healing_result.final_trial_result is not None:
                return healing_result.final_trial_result
        except Exception as exc:  # noqa: BLE001
            _logger.warning("Self-healing loop failed: %s", exc)
        return trial_result

    @staticmethod
    @traces(spec="102", story="US-005", reqs=["REQ-102-069", "REQ-102-117"])
    async def _run_evaluator(
        output: Any, context: HarnessContext, eval_config: Any
    ) -> EvaluatorResult:
        """Instantiate and run a single evaluator, catching any errors."""
        try:
            evaluator = get_evaluator(eval_config.name)
            return await evaluator.evaluate(output, context, eval_config)
        except Exception as exc:  # noqa: BLE001
            _logger.error("Evaluator '%s' crashed: %s", eval_config.name, exc)
            return EvaluatorResult(
                name=eval_config.name,
                passed=False,
                score=0.0,
                details=f"Evaluator error: {exc}",
            )

    @staticmethod
    @traces(spec="102", story="US-005", reqs=["REQ-102-075"])
    def _compute_composite_score(
        evaluator_results: list[EvaluatorResult], scenario: Scenario
    ) -> float:
        """Weighted average of evaluator scores.

        Returns 0.0 when there are no evaluator results or no weights.
        """
        if not evaluator_results or not scenario.evaluation:
            return 0.0

        total_weight = sum(ec.weight for ec in scenario.evaluation)
        if total_weight == 0:
            return 0.0

        score_map = {er.name: er.score for er in evaluator_results}
        weighted_sum = sum(
            score_map.get(ec.name, 0.0) * ec.weight for ec in scenario.evaluation
        )
        return weighted_sum / total_weight

    @staticmethod
    @traces(spec="102", story="US-001", reqs=["REQ-102-016"])
    def _compute_aggregate_score(trial_results: list[TrialResult]) -> float:
        """Average composite score across all trials.

        For each trial, re-derive the composite from evaluator results
        (simple mean of evaluator scores) since TrialResult doesn't store
        the composite directly.
        """
        if not trial_results:
            return 0.0

        scores: list[float] = []
        for trial in trial_results:
            if trial.evaluator_results:
                avg = sum(er.score for er in trial.evaluator_results) / len(
                    trial.evaluator_results
                )
                scores.append(avg)
            else:
                scores.append(0.0)

        return sum(scores) / len(scores) if scores else 0.0

    @staticmethod
    @traces(spec="102", story="US-001", reqs=["REQ-102-015", "REQ-102-060"])
    def _scenario_passed(
        trial_results: list[TrialResult], aggregate_score: float
    ) -> bool:
        """Return *True* when all trials passed and aggregate score meets threshold."""
        if not trial_results:
            return False
        return (
            all(t.passed for t in trial_results)
            and aggregate_score >= _COMPOSITE_PASS_THRESHOLD
        )

    @traces(spec="102", story="US-001", reqs=["REQ-102-007"])
    async def run_volk(self, volk_name: str, trials: int = 3) -> list[ScenarioResult]:
        """Run all scenarios for a given volk and return their results."""
        scenarios = load_scenarios_for_volk(volk_name)
        if not scenarios:
            _logger.warning("No scenarios found for volk '%s'", volk_name)
            return []

        results: list[ScenarioResult] = []
        for scenario in scenarios:
            result = await self.run_scenario(scenario, trials=trials)
            results.append(result)
        return results

    @traces(spec="102", story="US-001", reqs=["REQ-102-006"])
    def list_scenarios(self, volk_name: str | None = None) -> list[Scenario]:
        """List all loaded scenarios, optionally filtered by volk."""
        if volk_name:
            return load_scenarios_for_volk(volk_name)
        return list_all_scenarios()

    @staticmethod
    @traces(spec="102", story="US-002", reqs=["REQ-102-020"])
    def _current_git_commit() -> str:
        """Return the current HEAD commit SHA, or empty string on failure."""
        try:
            result = subprocess.run(
                ["git", "rev-parse", "HEAD"],
                capture_output=True,
                text=True,
                check=True,
            )
            return result.stdout.strip()
        except subprocess.CalledProcessError:
            _logger.warning("Unable to determine current git commit")
            return ""