Home / Infrastructure / Memgraph HA cluster reference
Memgraph HA Cluster Reference (orchgraph)
Topology at a glance
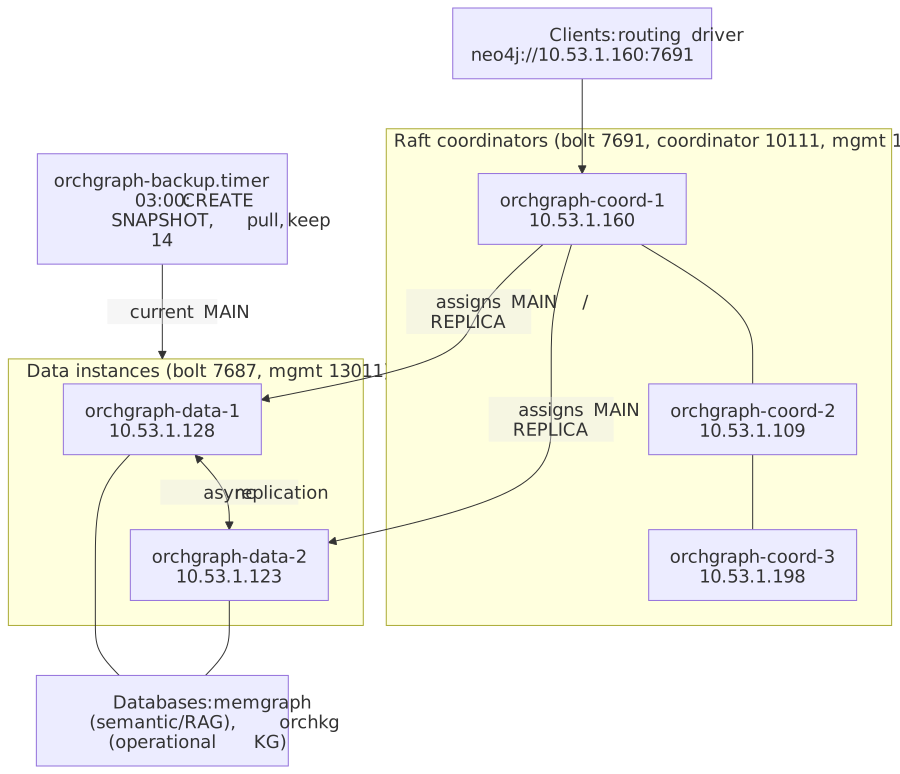
State on 2026-10-23
- All five containers are RUNNING in the Incus project
default, withboot.autostarttrue. They run Archlinux images on thet9-btrfspool. - The prod env profile connects with
KG_URI=neo4j://10.53.1.160:7691andKG_DATABASE=orchkg. - MAIN moves between the two data instances. The daily backup manifests from 2026-10-09 to 2026-10-22 record MAIN at
10.53.1.123on six days and at10.53.1.128on eight. On the last run, 2026-10-22 03:00, MAIN was10.53.1.123(orchgraph-data-2). - Node counts in the last backup manifest:
memgraph19,973 andorchkg156,953. On 2026-10-09 they were 19,737 and 115,995. - On 2026-10-21 a DeepChat session stopped the prod cluster. It was running again on 2026-10-22.
Writes auto-route to whichever data instance currently holds MAIN — the coordinators' Raft group decides that, and it can move on failover. Never hardcode a data-instance address for writes; always enter through the routing endpoint.
orchgraph is a custom C++ fork of Memgraph Community 3.11 that implements clustering, HA, and load-balancing at the C++ level with Raft-based high availability. Three Raft coordinators elect and monitor two data instances; MAIN/REPLICA roles are assigned dynamically by the coordinators, and failover is automatic and native — there is no external HTTP controller.
Layout
| Container | Role | Bolt URI |
|---|---|---|
| orchgraph-coord-1 | Raft coordinator | bolt://10.53.1.160:7691 |
| orchgraph-coord-2 | Raft coordinator | bolt://10.53.1.109:7691 |
| orchgraph-coord-3 | Raft coordinator | bolt://10.53.1.198:7691 |
| orchgraph-data-1 | Data (main/replica, dynamic) | bolt://10.53.1.128:7687 |
| orchgraph-data-2 | Data (main/replica, dynamic) | bolt://10.53.1.123:7687 |
Client Connection
Use a routing driver against a coordinator; the neo4j:// scheme auto-routes writes to the current MAIN and reads to replicas, and survives failover:
MEMGRAPH_URI=neo4j://10.53.1.160:7691 # auth=None
Never hardcode a data-instance IP as the write target — the MAIN can move.
Replication & Failover
Single MAIN with asynchronous replication to the replica. The Raft coordinators own cluster membership, role assignment, health monitoring, promotion, and failback natively — no manual role Cypher or curl endpoint is involved. Inspect cluster state over Bolt to any coordinator on port 7691:
SHOW INSTANCES;
Databases on this cluster
The cluster is MG_ENTERPRISE=ON, so CREATE DATABASE gives per-database
isolated storage, replicated by the same Raft group — two logical graphs
share this one physical cluster, not two clusters:
| Database | Graph | Contents |
|---|---|---|
memgraph (default) |
Shared semantic/RAG graph | knowledge-wiki :Chunk (wiki graph indexer) + orchestrata :SemanticChunk (semantic_graph ingest) |
orchkg |
Operational KG | orchestrata sessions, threads, CXP packets, decisions, specs, harness history, code intelligence — migrated off Neo4j 2026-07-26/27, see the migration record |
Select the database explicitly on every session (database=orchkg or
database=memgraph) — the routing URI above is the same for both.
Vector Search
The vector_search MAGE module is live on orchgraph:
CALL vector_search.search(...)CALL vector_search.search_edges(...)CALL vector_search.show_index_info()
Four indexes are present:
| Index | Graph |
|---|---|
| chunk_embedding | knowledge-wiki (:Chunk) |
| semantic_chunk_embedding_idx | orchestrata (:SemanticChunk) |
| qwen_chunk_embedding_idx | orchestrata |
| codestral_chunk_embedding_idx | orchestrata |
History
The previous cluster — a 3-node Memgraph Community cluster (memgraph-1/2/3) fronted by a custom Python HTTP HA controller (memgraph-ha, :8080, /main /status /failover /failback) plus a standalone memgraph-db — was decommissioned and deleted on 2026-07-10. Both graphs (wiki :Chunk and orchestrata :SemanticChunk) were ported to orchgraph and confirmed serving with a verified parity check before the old cluster was taken offline and deleted.
Backups
orchgraph-backup.service (timer daily at 03:00) runs /opt/orchestrata/scripts/backup_orchgraph.sh --retain 14. It finds the current MAIN, runs CREATE SNAPSHOT; on every database, pulls each newest snapshot with incus file pull to /var/lib/orchestrata/backups/orchgraph/<run>, writes manifest.json with each database's node count (MATCH (n) RETURN count(n)), and prunes to 14 runs. On 2026-10-23 the archive held 14 runs, 4.3 GB. The 2026-10-22 run pulled 213 MB for memgraph and 84 MB for the second database, which is stored under its UUID directory ab169e8f-.... The unit failed on every run from its install until commit 8b2038b92 (2026-10-05); see section 9 of Host services.
Test and dev graphs
These are not part of orchgraph. They are separate containers in the other environments (Incus fleets).
| Environment | Container | URI (env profile) | Role |
|---|---|---|---|
| test | orchestrata-test:memgraph |
bolt://10.53.2.10:7687 (KG_URI, TEST_MEMGRAPH_URI) |
standalone test graph, database orchkg |
| test | memgraph-ha-main, memgraph-ha-replica |
bolt://10.53.2.20:7687, bolt://10.53.2.21:7687 |
main/replica replication tests |
| test | rh-coord-1..3, rh-data-1 |
coordinators bolt://10.53.2.30..32:7691 |
Raft HA tests (TEST_MEMGRAPH_COORDINATOR_URIS) |
| dev | orchestrata-dev:memgraph |
bolt://10.53.3.20:7687 |
dev graph, database orchkg |
Prod is never a test target. The test suite's graph is orchestrata-test:memgraph.