orchestrata_ultimate.session.spec_parser
Reference › orchestrata_ultimate › session › spec_parser
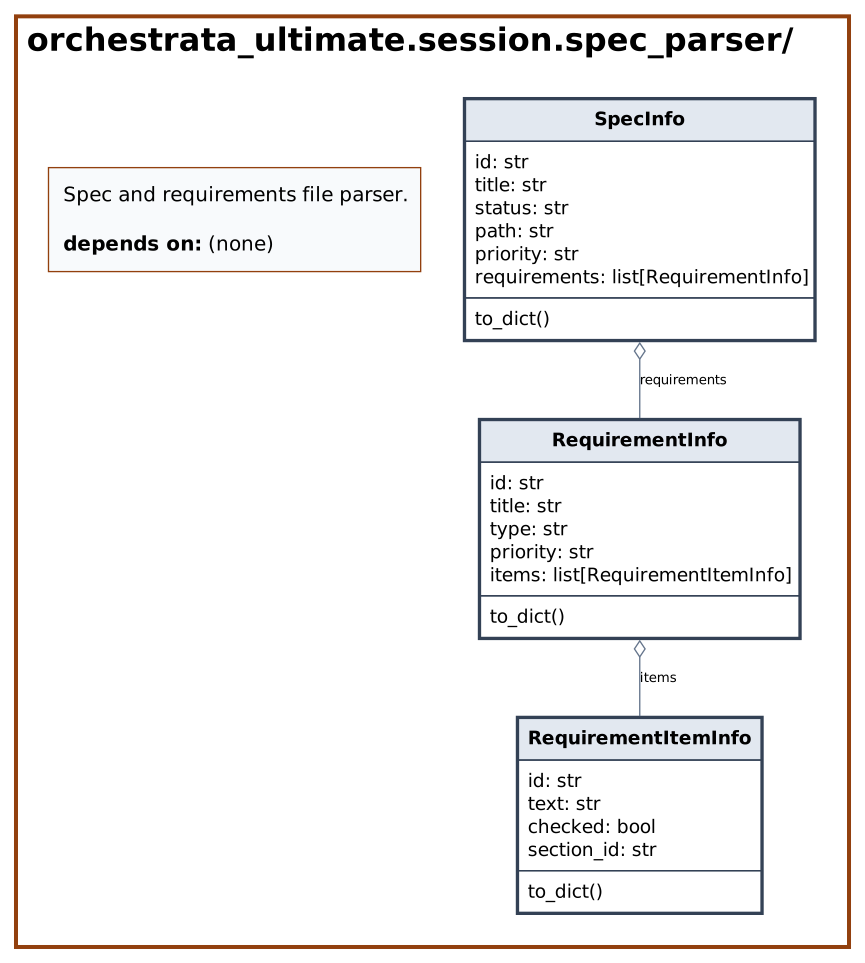
Parser for the specs/ directory, used by the spec stage of the knowledge-graph sync. parse_spec_file reads a spec.md and returns a SpecInfo with the spec's metadata, or nothing; parse_requirements_file reads a requirements.md checklist and returns a list of RequirementInfo sections (FR, NFR and US sections or plain headings), each holding RequirementItemInfo checklist items; parse_all_specs parses every spec under a directory. The three dataclasses have to_dict methods for graph insertion.
At a glance
| Source | src/orchestrata_ultimate/session/spec_parser.py |
| Lines of code | 366 |
| Classes | 3 |
| Functions | 9 |
| Imports (internal) | none |
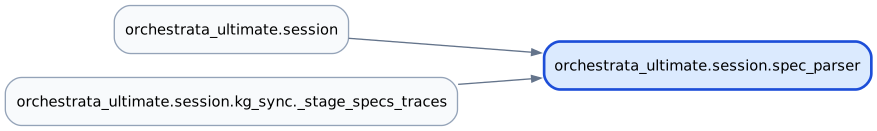
| Imported by | orchestrata_ultimate.session, orchestrata_ultimate.session.kg_sync._stage_specs_traces |
| Tests that import it | tests/session/test_session_signatures.py, tests/session/test_session_spec_parser.py, tests/session/test_spec_parser.py |
Class diagram
Dependency diagram
API
Classes
RequirementItemInfo (dataclass)
Decorators: dataclass · Line 19
A single requirement item from a checklist.
| Attribute | Type | Default |
|---|---|---|
id |
str |
|
text |
str |
|
checked |
bool |
|
section_id |
str |
'' |
| Method | Signature | Summary |
|---|---|---|
to_dict |
to_dict() -> dict |
RequirementInfo (dataclass)
Decorators: dataclass · Line 37
A requirement section (FR-NNN, NFR-NNN, US-NNN, or section heading).
| Attribute | Type | Default |
|---|---|---|
id |
str |
|
title |
str |
|
type |
str |
'' |
priority |
str |
'' |
items |
list[RequirementItemInfo] |
field(default_factory=list) |
| Method | Signature | Summary |
|---|---|---|
to_dict |
to_dict() -> dict |
SpecInfo (dataclass)
Decorators: dataclass · Line 57
Parsed spec metadata.
| Attribute | Type | Default |
|---|---|---|
id |
str |
|
title |
str |
|
status |
str |
'' |
path |
str |
'' |
priority |
str |
'' |
requirements |
list[RequirementInfo] |
field(default_factory=list) |
| Method | Signature | Summary |
|---|---|---|
to_dict |
to_dict() -> dict |
Functions
| Function | Signature | Summary |
|---|---|---|
parse_spec_file |
parse_spec_file(spec_path: str) -> SpecInfo | None |
Parse a spec.md file to extract metadata. |
_parse_spec_title |
_parse_spec_title(line: str) -> tuple[str, str] | None |
Parse a spec title line, returning (spec_id, title) or None. |
_parse_spec_metadata_line |
_parse_spec_metadata_line(line: str, meta: dict) -> None |
Update meta in place from a **Status**/**Priority** line. |
parse_requirements_file |
parse_requirements_file(req_path: str) -> list[RequirementInfo] |
Parse a requirements.md checklist file. |
_parse_requirement_section |
_parse_requirement_section(line: str) -> RequirementInfo | None | Literal[False] |
Parse a section heading line. |
_parse_bold_item |
_parse_bold_item(line: str, current: RequirementInfo | None) -> RequirementItemInfo | None |
Parse a bold **REQ-NNN** checklist item, or None if the line isn't one. |
_parse_plain_item |
_parse_plain_item(line: str, current: RequirementInfo | None, spec_id_from_path: str, plain_counter: int) -> tuple[int, RequirementItemInfo | None] |
Parse a plain - [x] text checkbox, generating an auto requirement id. |
_ensure_current |
_ensure_current(current: RequirementInfo | None, requirements: list[RequirementInfo]) -> RequirementInfo |
Return current, creating and registering an 'uncategorized' section if None. |
parse_all_specs |
parse_all_specs(specs_dir: str) -> list[SpecInfo] |
Parse all specs in the specs/ directory. |
Source
"""Spec and requirements file parser.

Parses spec.md and requirements.md files from the specs/ directory
to extract structured data for knowledge graph sync.

Spec: 006 - Session Management
"""

import logging
import re
from dataclasses import dataclass, field
from pathlib import Path
from typing import Literal

logger = logging.getLogger(__name__)


@dataclass
class RequirementItemInfo:
    """A single requirement item from a checklist."""

    id: str
    text: str
    checked: bool
    section_id: str = ""

    def to_dict(self) -> dict:
        return {
            "id": self.id,
            "text": self.text,
            "checked": self.checked,
            "section_id": self.section_id,
        }


@dataclass
class RequirementInfo:
    """A requirement section (FR-NNN, NFR-NNN, US-NNN, or section heading)."""

    id: str
    title: str
    type: str = ""
    priority: str = ""
    items: list[RequirementItemInfo] = field(default_factory=list)

    def to_dict(self) -> dict:
        return {
            "id": self.id,
            "title": self.title,
            "type": self.type,
            "priority": self.priority,
            "items": [i.to_dict() for i in self.items],
        }


@dataclass
class SpecInfo:
    """Parsed spec metadata."""

    id: str
    title: str
    status: str = ""
    path: str = ""
    priority: str = ""
    requirements: list[RequirementInfo] = field(default_factory=list)

    def to_dict(self) -> dict:
        return {
            "id": self.id,
            "title": self.title,
            "status": self.status,
            "path": self.path,
            "priority": self.priority,
            "requirements": [r.to_dict() for r in self.requirements],
        }


# Regex patterns for spec.md
_SPEC_TITLE_RE = re.compile(r"^#\s+(\S+?):\s*(.+)")
_METADATA_RE = re.compile(r"^(?:-\s+)?\*\*(\w[\w\s]*?)\*\*:\s*(.+)")

# Regex patterns for requirements.md
# Matches: ### FR-014: Title  or  ### FR-014: Title (P0)
_SECTION_RE = re.compile(
    r"^###\s+((?:FR|NFR|US)-\d+):\s*(.+?)(?:\s*\(([P][0-3])\))?\s*$"
)
# Matches: ## Section Name (spec 008 style, no FR prefix)
_SECTION_HEADING_RE = re.compile(r"^##\s+(.+?)\s*$")
# Matches: - [x] **REQ-006-FR14-001**: description  or  - [ ] **REQ-008-001**: description
_ITEM_RE = re.compile(r"^-\s+\[([ xX])\]\s+\*\*(REQ-[\w-]+)\*\*:\s*(.+)")
# Validates that a parsed spec ID starts with 3 digits
_VALID_SPEC_ID = re.compile(r"^\d{3}")
# Extracts numeric prefix (e.g., "008" from "008-Knowledge-Graph")
_NUMERIC_PREFIX = re.compile(r"^(\d{3}[a-z]?)")
# Plain checkbox without bold REQ-NNN prefix (e.g., spec 004-cxp)
_ITEM_RE_PLAIN = re.compile(r"^-\s+\[([ xX])\]\s+(.+)")


def parse_spec_file(spec_path: str) -> SpecInfo | None:
    """Parse a spec.md file to extract metadata.

    Args:
        spec_path: Path to the spec.md file.

    Returns:
        SpecInfo with id, title, status, priority, or None if unparseable.
    """
    path = Path(spec_path)
    if not path.is_file():
        return None

    text = path.read_text(encoding="utf-8")
    lines = text.splitlines()

    spec_id = ""
    title = ""
    meta = {"status": "", "priority": ""}

    for line in lines:
        # Parse title line: # 006: Session Management
        if not spec_id:
            parsed = _parse_spec_title(line)
            if parsed is not None:
                spec_id, title = parsed
                continue

        _parse_spec_metadata_line(line, meta)

        # Stop after metadata section
        if line.startswith("## Overview") or line.startswith("## User"):
            break

    if not spec_id:
        return None

    return SpecInfo(
        id=spec_id,
        title=title,
        status=meta["status"],
        path=str(path),
        priority=meta["priority"],
    )


def _parse_spec_title(line: str) -> tuple[str, str] | None:
    """Parse a spec title line, returning ``(spec_id, title)`` or None."""
    m = _SPEC_TITLE_RE.match(line)
    if not m:
        return None
    spec_id = m.group(1).strip()
    # Normalize: "008-Knowledge-Graph" → "008"
    m2 = _NUMERIC_PREFIX.match(spec_id)
    if m2:
        spec_id = m2.group(1)
    return spec_id, m.group(2).strip()


def _parse_spec_metadata_line(line: str, meta: dict) -> None:
    """Update ``meta`` in place from a ``**Status**``/``**Priority**`` line."""
    m = _METADATA_RE.match(line.strip())
    if not m:
        return
    key = m.group(1).strip().lower()
    val = m.group(2).strip()
    if key == "status":
        meta["status"] = val
    elif key == "priority":
        meta["priority"] = val


def parse_requirements_file(req_path: str) -> list[RequirementInfo]:
    """Parse a requirements.md checklist file.

    Handles two formats:
    - Spec 006 style: ### FR-NNN: Title (P0) with REQ-006-FRN-NNN items
    - Spec 008 style: ## Section Name with REQ-008-NNN items

    Args:
        req_path: Path to the requirements.md file.

    Returns:
        List of RequirementInfo, each containing its RequirementItemInfo items.
    """
    path = Path(req_path)
    if not path.is_file():
        return []

    # Extract spec ID from path for auto-generated requirement IDs
    spec_id_from_path = ""
    for parent in path.parents:
        m = re.match(r"^(\d{3})", parent.name)
        if m:
            spec_id_from_path = m.group(1)
            break

    text = path.read_text(encoding="utf-8")
    lines = text.splitlines()

    requirements: list[RequirementInfo] = []
    current: RequirementInfo | None = None
    plain_counter = 0

    for line in lines:
        # Section heading (### FR-NNN or ## Section Name) resets current
        section = _parse_requirement_section(line)
        if section is not False:
            current = section
            if current is not None:
                requirements.append(current)
            continue

        # Requirement item (bold REQ-NNN prefix)
        item = _parse_bold_item(line, current)
        if item is None:
            # Fallback: plain checkbox without bold REQ prefix (e.g. spec 004-cxp)
            plain_counter, item = _parse_plain_item(
                line, current, spec_id_from_path, plain_counter
            )
        if item is None:
            continue

        current = _ensure_current(current, requirements)
        current.items.append(item)

    return requirements


def _parse_requirement_section(line: str) -> RequirementInfo | None | Literal[False]:
    """Parse a section heading line.

    Returns a new ``RequirementInfo`` for a section, ``None`` when the line is a
    heading that clears the current section, or ``False`` when the line is not a
    section heading at all.
    """
    m = _SECTION_RE.match(line)
    if m:
        return RequirementInfo(
            id=m.group(1),
            title=m.group(2).strip(),
            type=m.group(1).split("-")[0],
            priority=m.group(3) or "",
        )

    m = _SECTION_HEADING_RE.match(line)
    if m:
        heading = m.group(1).strip()
        # Skip top-level headings like "Completion Criteria"
        if heading.lower() in ("completion criteria",):
            return None
        return RequirementInfo(
            id=heading.replace(" ", "-").lower(),
            title=heading,
            type="section",
        )

    return False


def _parse_bold_item(
    line: str, current: RequirementInfo | None
) -> RequirementItemInfo | None:
    """Parse a bold ``**REQ-NNN**`` checklist item, or None if the line isn't one."""
    m = _ITEM_RE.match(line)
    if not m:
        return None
    return RequirementItemInfo(
        id=m.group(2),
        text=m.group(3).strip(),
        checked=m.group(1).lower() == "x",
        section_id=current.id if current else "",
    )


def _parse_plain_item(
    line: str,
    current: RequirementInfo | None,
    spec_id_from_path: str,
    plain_counter: int,
) -> tuple[int, RequirementItemInfo | None]:
    """Parse a plain ``- [x] text`` checkbox, generating an auto requirement id.

    Returns the (possibly incremented) plain counter and the item, or None.
    """
    m = _ITEM_RE_PLAIN.match(line)
    if not m:
        return plain_counter, None
    plain_counter += 1
    section_part = current.id if current else "UNC"
    sid = spec_id_from_path or "UNK"
    item = RequirementItemInfo(
        id=f"REQ-{sid}-{section_part}-{plain_counter:03d}",
        text=m.group(2).strip(),
        checked=m.group(1).lower() == "x",
        section_id=current.id if current else "",
    )
    return plain_counter, item


def _ensure_current(
    current: RequirementInfo | None, requirements: list[RequirementInfo]
) -> RequirementInfo:
    """Return ``current``, creating and registering an 'uncategorized' section if None."""
    if current is not None:
        return current
    current = RequirementInfo(
        id="uncategorized",
        title="Uncategorized",
        type="section",
    )
    requirements.append(current)
    return current


def parse_all_specs(specs_dir: str) -> list[SpecInfo]:
    """Parse all specs in the specs/ directory.

    For each spec directory, parses spec.md and checklists/requirements.md.

    Args:
        specs_dir: Path to the specs/ directory.

    Returns:
        List of SpecInfo objects with requirements attached.
    """
    specs_path = Path(specs_dir)
    if not specs_path.is_dir():
        return []

    results: list[SpecInfo] = []

    for spec_dir in sorted(specs_path.iterdir()):
        if not spec_dir.is_dir():
            continue

        # Try candidate spec files in order of preference
        spec_info = None
        for candidate in ("spec.md", "prompt.md", "README.md"):
            spec_file = spec_dir / candidate
            info = parse_spec_file(str(spec_file))
            if info is not None and _VALID_SPEC_ID.match(info.id):
                spec_info = info
                break

        # Fallback: derive spec metadata from directory name
        if spec_info is None:
            dir_name = spec_dir.name
            m = re.match(r"^(\d{3})", dir_name)
            if m:
                spec_id = m.group(1)
                title = (
                    dir_name.split("-", 1)[1].replace("-", " ").title()
                    if "-" in dir_name
                    else dir_name
                )
                spec_info = SpecInfo(id=spec_id, title=title, path=str(spec_dir))

        if spec_info is None:
            continue

        req_file = spec_dir / "checklists" / "requirements.md"
        if req_file.is_file():
            spec_info.requirements = parse_requirements_file(str(req_file))

        results.append(spec_info)

    return results