orchestrata_ultimate.promotion.runner
Reference › orchestrata_ultimate › promotion › runner
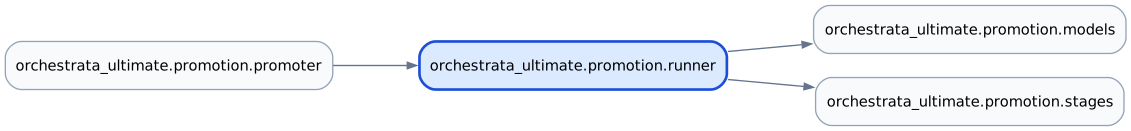
The runner executes the deployment stages in order and rolls the target back when the result does not serve. It is the module where the ordering guarantee lives: the first stage that fails stops the run, and a failure at or after the restart returns the target to the commit it served before. promoter is its only importer; it uses the result types from models and the stage functions re-exported by stages. The package story is in the promotion narrative.
deploy(ctx, execute, skip_graphs, skip_ingest, settle, progress) builds the step list: resolve, infra, tree, deps, assets, record_version, services and verify, then graphs and ingest unless skipped. It reads the lock hash of the target before anything moves so deps can tell whether the lock changed, and resolves the daemon units. Each stage is announced through the progress callback when it starts and when it ends, with its elapsed time, so a long stage such as the graph bootstrap is never silent. Once the run reaches the live stage (the restart), any later failure with execute true calls _rollback. With execute false every stage reports what it would do and nothing moves.
_rollback does a hard reset of the target to previous_sha, restores the previous VERSION text (or removes the file if there was none), re-runs the old tree's deploy/systemd/install.sh so the old unit files replace the new ones, reloads systemd, clears failed state and restarts the units that the deploy actually restarted. It adds a rollback result to the report: SKIP when there is no previous sha, FAIL when the reset, the unit reinstall or any restart fails, OK otherwise. Rollback is thus verified by restart and the report does not claim recovery that did not happen.
drift(ctx, ledger_sha) compares the sha recorded in the ledger with the target's actual HEAD and returns a FAIL result naming how many commits behind the target is, or OK when they match. It fails when the target is not a git checkout or the ledger holds no sha.
At a glance
| Source | src/orchestrata_ultimate/promotion/runner.py |
| Lines of code | 285 |
| Classes | 0 |
| Functions | 4 |
| Imports (internal) | orchestrata_ultimate.promotion.models, orchestrata_ultimate.promotion.stages |
| Imported by | orchestrata_ultimate.promotion.promoter |
| Tests that import it | tests/promotion/test_promotion_prod_lessons.py, tests/promotion/test_promotion_units.py, tests/promotion/test_runner_coverage.py, tests/promotion/test_stages_coverage.py |
Class diagram
No classes; see Functions.
Dependency diagram
API
Functions
| Function | Signature | Summary |
|---|---|---|
_settle_kw |
_settle_kw(settle: float | None) -> dict[str, float] |
Forward settle only when a caller actually chose one. |
deploy |
deploy(ctx: DeployContext, *, execute: bool = True, skip_graphs: bool = False, skip_ingest: bool = False, settle: float | None = None, progress: Callable[[str], None] | None = None) -> DeployReport |
Deploy ctx.sha to ctx.target_root; roll back if it will not serve. |
_rollback |
_rollback(ctx: DeployContext, report: DeployReport) -> bool |
Return the target to the sha it was serving, and restart onto it. |
drift |
drift(ctx: DeployContext, ledger_sha: str) -> StageResult |
Does the ledger still describe the running system? |
Source
"""Run the stages in order, roll back when verification fails.

The ordering guarantee this module provides is the whole product: stages run
in sequence, the first FAIL stops the run, and a failure at or after the
restart returns the target to the sha it was serving before. A deploy that
half-lands and reports success is worse than one that refuses.
"""

from __future__ import annotations

import time
from collections.abc import Callable

from orchestrata_ultimate.promotion.models import DeployReport, StageResult, StageStatus
from orchestrata_ultimate.promotion.stages import (
    DeployContext,
    _lock_hash,
    _run,
    _scope,
    _systemctl,
    advance_tree,
    bootstrap_graphs,
    daemon_units,
    ingest_projects,
    install_assets,
    probe_endpoints,
    record_version,
    resolve_commit,
    restart_services,
    sync_deps,
    verify,
)

#: Stages that have put the new code in front of traffic. A failure at or after
#: this point leaves the target SERVING the new tree, so rollback is required;
#: a failure before it has changed nothing that needs undoing.
_LIVE_FROM = "services"


def _settle_kw(settle: float | None) -> dict[str, float]:
    """Forward ``settle`` only when a caller actually chose one.

    ``deploy`` used to declare ``settle: float = 3.0`` and pass it down
    unconditionally, which silently overrode ``verify``'s own 90.0 — and
    verify's default is the one carrying the measurement: the kernel loads
    Prolog, connects Redis and the graph, and binds LAST, measured at 9s on
    prod. So the stage that proved 3s was too short had its proof overwritten
    by its caller, and the 2026-08-24 prod promotion rolled back a healthy
    tree reporting "not listening: kernel localhost:50053" after polling 3.3s.

    Omitting the key entirely means the default lives in exactly one place —
    the function whose docstring records the measurement behind it.
    """
    return {} if settle is None else {"settle": settle}


def deploy(
    ctx: DeployContext,
    *,
    execute: bool = True,
    skip_graphs: bool = False,
    skip_ingest: bool = False,
    settle: float | None = None,
    progress: Callable[[str], None] | None = None,
) -> DeployReport:
    """Deploy ``ctx.sha`` to ``ctx.target_root``; roll back if it will not serve.

    ``progress`` receives one line when each stage STARTS and one when it
    finishes. Without it, the first live promote ran its slowest stage (the
    31-project corpus rebuild, 15+ minutes) in total silence — the buffered
    end-of-run report is a record, not observability, and a caller watching
    the log could not tell a long stage from a hung one (user ruling
    2026-08-14: gates must notify; nobody waits blind on a silent stage).
    """
    report = DeployReport(env=ctx.env)
    emit = progress or (lambda line: None)

    previous_lock = _lock_hash(ctx.target_root)
    ctx.units = ctx.units or daemon_units(ctx.target_root)

    steps: list[tuple[str, Callable[[], StageResult]]] = [
        ("resolve", lambda: resolve_commit(ctx, execute=execute)),
        ("infra", lambda: probe_endpoints(ctx, execute=execute)),
        ("tree", lambda: advance_tree(ctx, execute=execute)),
        ("deps", lambda: sync_deps(ctx, execute=execute, previous_lock=previous_lock)),
        ("assets", lambda: install_assets(ctx, execute=execute)),
        ("record_version", lambda: record_version(ctx, execute=execute)),
        ("services", lambda: restart_services(ctx, execute=execute)),
        # settle is NOT defaulted here — verify owns it. See _settle_kw.
        ("verify", lambda: verify(ctx, execute=execute, **_settle_kw(settle))),
    ]
    if not skip_graphs:
        steps.append(
            ("graphs", lambda: bootstrap_graphs(ctx, execute=execute, progress=emit))
        )
    if not skip_ingest:
        steps.append(("ingest", lambda: ingest_projects(ctx, execute=execute)))

    went_live = False
    for name, step in steps:
        if name == _LIVE_FROM:
            went_live = True
        emit(f"[....] {name}")
        started = time.monotonic()
        result = report.add(step())
        elapsed = time.monotonic() - started
        emit(
            f"[{'FAIL' if result.failed else 'OK  '}] {name:22s} "
            f"{elapsed:6.1f}s  {result.detail}"
        )
        report.sha = ctx.sha
        report.previous_sha = ctx.previous_sha
        if result.failed:
            if went_live and execute:
                report.rolled_back = _rollback(ctx, report)
            break

    report.sha = ctx.sha
    report.previous_sha = ctx.previous_sha
    return report


def _rollback(ctx: DeployContext, report: DeployReport) -> bool:
    """Return the target to the sha it was serving, and restart onto it.

    Rollback is itself verified-by-restart rather than assumed: if the previous
    sha will not come up either, the record says so instead of implying the
    system was recovered.
    """
    if not ctx.previous_sha or ctx.previous_sha == ctx.sha:
        report.add(
            StageResult(
                name="rollback",
                status=StageStatus.SKIP,
                detail="no previous sha to return to",
            )
        )
        return False

    # --hard, not merge -- the same discipline advance_tree itself uses.
    # Rollback runs because the new tree will not serve; unexpected local
    # dirt on the target is not state worth preserving over getting the
    # system back to a sha that worked. The first rollback this package
    # attempted failed on exactly that, leaving prod on the bad tree.
    reset = _run(
        ["git", "reset", "--hard", "--quiet", ctx.previous_sha],
        cwd=ctx.target_root,
    )
    if reset.returncode != 0:
        report.add(
            StageResult(
                name="rollback",
                status=StageStatus.FAIL,
                detail=f"could not return to {ctx.previous_sha[:12]}: {reset.stderr.strip()[:120]}",
            )
        )
        return False

    # VERSION is restored only once the tree is actually back -- writing it
    # first would leave VERSION claiming a commit the checkout does not
    # carry if the reset above had failed (resolve_commit's own rule: a
    # record that cannot be true is a lie by construction).
    version_path = ctx.target_root / "VERSION"
    if ctx.previous_version_text:
        version_path.write_text(ctx.previous_version_text, encoding="utf-8")
    else:
        version_path.unlink(missing_ok=True)

    # The unit files are NOT in the tree the reset just restored: `assets`
    # copied the NEW commit's units into the systemd unit directory, and a
    # tree reset leaves those copies in place. A unit whose new file names
    # something only the new tree carries (2026-10-09: an EnvironmentFile=
    # that the old tree did not ship) then cannot even load, so the restart
    # below fails and prod is left on the old tree with no running service
    # -- which happened twice that day before this was written. The old
    # tree's own installer puts the old tree's units back; a tree without
    # one has nothing installed from it to undo.
    installer = ctx.target_root / "deploy" / "systemd" / "install.sh"
    if installer.is_file():
        reinstalled = _run(["bash", str(installer)], cwd=ctx.target_root, timeout=300)
        if reinstalled.returncode != 0:
            report.add(
                StageResult(
                    name="rollback",
                    status=StageStatus.FAIL,
                    detail=(
                        f"returned to {ctx.previous_sha[:12]} but reinstalling its "
                        f"units failed: {reinstalled.stderr.strip()[:120]}"
                    ),
                )
            )
            return False

    # Restart exactly what the deploy actually restarted (N1, reviewer on
    # U-T7): `ctx.units` is resolved once at the top of deploy(), before
    # `tree`/`deps` run, so it can still be [] here even though
    # restart_services -- which recomputes `ctx.units or daemon_units(...)`
    # itself, after deps created the target's .venv -- restarted five real
    # units. Falling back to a fresh daemon_units() only when nothing was
    # ever restarted (services itself never ran) keeps rollback from
    # restarting units the live deploy never touched.
    units = ctx.restarted_units or daemon_units(ctx.target_root)
    unit_scopes = {
        unit: _scope(ctx.target_root / "deploy" / "systemd" / unit) for unit in units
    }
    for scope in dict.fromkeys(unit_scopes.values()):
        _run([*_systemctl(scope), "daemon-reload"], timeout=60)
    # Real return codes, not an assumed "restarted N unit(s)" (F2, reviewer
    # on attempt 1): the tree/VERSION half of rollback above is what makes
    # this "verified-by-restart" rather than assumed, and a restart that
    # systemd genuinely refuses cannot be folded into the same OK the
    # successful ones get.
    failures: list[str] = []
    for unit in units:
        # A unit the bad tree already drove into its start-limit burst
        # refuses `restart` with "Start request repeated too quickly" until
        # its failed state is cleared, no matter how good the restored file
        # is. Clearing it is not a verdict on the unit -- the restart below
        # still is -- so its own exit code is deliberately not inspected.
        _run([*_systemctl(unit_scopes[unit]), "reset-failed", unit], timeout=60)
        result = _run([*_systemctl(unit_scopes[unit]), "restart", unit], timeout=120)
        if result.returncode != 0:
            failures.append(f"{unit} ({result.stderr.strip()[:80]})")
    if failures:
        report.add(
            StageResult(
                name="rollback",
                status=StageStatus.FAIL,
                detail=(
                    f"returned to {ctx.previous_sha[:12]} but restart failed: "
                    + "; ".join(failures)
                ),
            )
        )
        return False
    report.add(
        StageResult(
            name="rollback",
            status=StageStatus.OK,
            detail=f"returned to {ctx.previous_sha[:12]} and restarted {len(units)} unit(s)",
        )
    )
    return True


def drift(ctx: DeployContext, ledger_sha: str) -> StageResult:
    """Does the ledger still describe the running system?

    The failure this catches is the one that motivated the whole package: a
    ledger reading PROMOTED while the target served a tree 76 commits behind,
    with nothing in the system able to notice. Comparing the recorded sha
    against the target's actual HEAD turns that from an invisible state into a
    one-line verdict.
    """
    if not (ctx.target_root / ".git").exists():
        return StageResult(
            name="drift",
            status=StageStatus.FAIL,
            detail=f"{ctx.target_root} is not a git checkout",
        )

    head = _run(["git", "rev-parse", "HEAD"], cwd=ctx.target_root).stdout.strip()
    if not ledger_sha:
        return StageResult(
            name="drift",
            status=StageStatus.FAIL,
            detail=f"ledger records no sha; target is at {head[:12]} — the record cannot be checked",
        )
    if head == ledger_sha:
        return StageResult(
            name="drift",
            status=StageStatus.OK,
            detail=f"target matches ledger at {head[:12]}",
        )
    behind = _run(
        ["git", "rev-list", "--count", f"{head}..{ledger_sha}"], cwd=ctx.target_root
    ).stdout.strip()
    return StageResult(
        name="drift",
        status=StageStatus.FAIL,
        detail=(
            f"DRIFTED: ledger says {ledger_sha[:12]}, target serves {head[:12]}"
            + (f" ({behind} commit(s) behind)" if behind.isdigit() else "")
        ),
    )