orchestrata_ultimate.knowledge_graph.project_resolver
Reference › orchestrata_ultimate › knowledge_graph › project_resolver
Resolves the canonical project identifier that volks and the session subsystem use when they read or write :Project-scoped data in the operational knowledge graph (orchkg on orchgraph). derive_project_id returns the basename of a directory, or None for an empty value; it mirrors the older convention in the session KG sync and in kg_context. resolve_project_id (REQ-008-102) applies a fixed order: an explicit id wins; otherwise, if a synchronous graph repository is supplied, it runs one read query for a :Project node whose path, slug or id matches and returns coalesce(p.id, p.slug), because slug is the canonical merge key that production writers populate; otherwise it falls back to the basename. The lookup is best-effort: any exception is logged at debug level and the basename is returned, so context injection degrades instead of failing. Many analyst, compliance and kernel volks import it.
At a glance
| Source | src/orchestrata_ultimate/knowledge_graph/project_resolver.py |
| Lines of code | 122 |
| Classes | 0 |
| Functions | 2 |
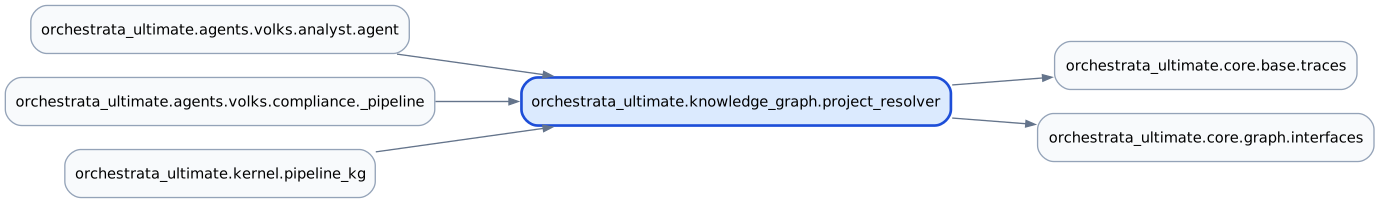
| Imports (internal) | orchestrata_ultimate.core.base.traces, orchestrata_ultimate.core.graph.interfaces |
| Imported by | orchestrata_ultimate.agents.volks.analyst.agent, orchestrata_ultimate.agents.volks.compliance._pipeline, orchestrata_ultimate.kernel.pipeline_kg |
| Tests that import it | tests/kernel/test_audit_logger_enforcement_proof.py, tests/kernel/test_volk_kg_sync.py, tests/knowledge_graph/test_project_resolver.py |
Class diagram
No classes; see Functions.
Dependency diagram
API
Functions
| Function | Signature | Summary |
|---|---|---|
derive_project_id |
derive_project_id(project_dir: str | None) -> str | None |
Derive a default project identifier from a project directory. |
resolve_project_id traces |
resolve_project_id(project_dir: str | None, repo: SyncGraphRepository | None = None, *, explicit_project_id: str | None = None) -> str | None |
Resolve the canonical project identifier for a project directory. |
Source
"""Project identity resolution for knowledge-graph operations.

Knowledge-graph File/Package nodes are project-qualified (``{project_id}:{path}``).
Historically every caller derived ``project_id`` from ``os.path.basename(project_dir)``,
which is a basename heuristic duplicated in several modules. This module provides
a single, tested resolution path:

1. If a project identifier is explicitly provided, use it.
2. Otherwise, look up an existing ``:Project`` node in the graph whose ``path`` or
   ``slug`` matches the directory and return its ``id``.
3. Fall back to the directory basename only when no Project node exists.

This keeps multi-project KG queries scoped and deterministic without requiring
every caller to repeat the basename extraction.
"""

from __future__ import annotations

import logging
import os
from pathlib import Path
from typing import TYPE_CHECKING

from orchestrata_ultimate.core.base.traces import traces

if TYPE_CHECKING:
    from orchestrata_ultimate.core.graph.interfaces import SyncGraphRepository

_logger = logging.getLogger(__name__)


def derive_project_id(project_dir: str | None) -> str | None:
    """Derive a default project identifier from a project directory.

    The default derivation is the basename of the directory. This mirrors the
    historical convention used by ``session/kg_sync/_base.py`` and
    ``knowledge_graph/kg_context.py`` so that callers migrating to explicit
    resolution remain compatible with existing Project nodes.

    Args:
        project_dir: Project root directory, or None.

    Returns:
        Basename of the directory, or None when ``project_dir`` is empty/None.
    """
    if not project_dir:
        return None
    return os.path.basename(project_dir.rstrip("/"))


@traces(spec="008", reqs=["REQ-008-102"])
def resolve_project_id(
    project_dir: str | None,
    repo: SyncGraphRepository | None = None,
    *,
    explicit_project_id: str | None = None,
) -> str | None:
    """Resolve the canonical project identifier for a project directory.

    Resolution order:

    1. ``explicit_project_id`` if provided.
    2. Lookup an existing ``:Project`` node in the supplied graph repository by
       matching ``project_dir`` against ``p.path`` and the directory basename
       against ``p.slug``; return ``coalesce(p.id, p.slug)`` — an explicitly
       configured ``id`` when the deployment sets one, otherwise ``slug``, the
       canonical merge key every production writer actually populates.
    3. Fall back to ``derive_project_id(project_dir)``.

    The lookup is best-effort: if the repository is unavailable or the query
    fails, the function falls back to the basename derivation rather than
    raising, so context-injection callers can degrade gracefully.

    Args:
        project_dir: Project root directory. Used for both the Project lookup
            and the basename fallback.
        repo: Optional graph repository for Project-node lookup.
        explicit_project_id: Optional explicitly configured project id that
            takes precedence over lookup.

    Returns:
        The resolved project identifier, or None when ``project_dir`` is empty
        and no explicit id was given.
    """
    if explicit_project_id:
        return explicit_project_id

    if not project_dir:
        return None

    if repo is not None:
        try:
            slug = derive_project_id(project_dir)
            result = repo.execute_read(
                "MATCH (p:Project) "
                "WHERE p.path = $path "
                "   OR p.slug = $slug "
                "   OR p.id = $slug "
                # `slug` is the CANONICAL merge key for :Project
                # (canonical_schema.CANONICAL_MERGE_KEYS[LABEL_PROJECT]), and
                # every production writer MERGEs on it without ever setting
                # `id` — the live node reads id=null. Returning bare `p.id`
                # therefore always fell through to the basename below, making
                # this whole lookup inert. Prefer an explicit id when a
                # deployment sets one; otherwise use the canonical key.
                "RETURN coalesce(p.id, p.slug) AS id LIMIT 1",
                {"path": str(Path(project_dir).resolve()), "slug": slug},
            )
            for record in result:
                raw_id = record.get("id")
                if raw_id:
                    project_id = str(raw_id)
                    _logger.debug(
                        "Resolved project_id %r for %r from KG Project node",
                        project_id,
                        project_dir,
                    )
                    return project_id
        except Exception as exc:
            _logger.debug("Project-node lookup failed: %s", exc)

    return derive_project_id(project_dir)