orchestrata_ultimate.drivers.extraction
Reference › orchestrata_ultimate › drivers › extraction
extraction holds the shared helpers that pull files out of raw model output, reusable by browser-based and API-based drivers. extract_file_blocks finds FILE: blocks in the response and returns (path, content) pairs. extract_markdown_code_blocks is the fallback for replies that contain fenced code without FILE: headers. _extract_fenced_code reads the content between fence markers. browser_driver uses both public functions and the package facade re-exports them. Tests are in tests/drivers/test_extraction.py.
At a glance
| Source | src/orchestrata_ultimate/drivers/extraction.py |
| Lines of code | 112 |
| Classes | 0 |
| Functions | 3 |
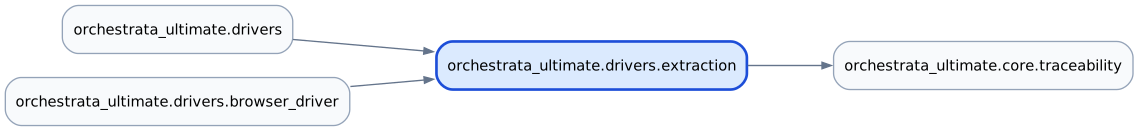
| Imports (internal) | orchestrata_ultimate.core.traceability |
| Imported by | orchestrata_ultimate.drivers, orchestrata_ultimate.drivers.browser_driver |
| Tests that import it | tests/drivers/test_extraction.py, tests/generated_recovery/test_drivers_extraction.py, tests/test_drivers.py |
Class diagram
No classes; see Functions.
Dependency diagram
API
Functions
| Function | Signature | Summary |
|---|---|---|
extract_file_blocks traces |
extract_file_blocks(response: str) -> list[tuple[str, str]] |
Extract FILE: blocks from LLM response text. |
extract_markdown_code_blocks traces |
extract_markdown_code_blocks(response: str) -> list[tuple[str, str]] |
Fallback: extract markdown code blocks without FILE: headers. |
_extract_fenced_code traces |
_extract_fenced_code(lines: list[str]) -> str |
Extract code content between ``` markers. |
Source
"""Shared file extraction utilities for LLM response parsing.

Extracts FILE: blocks and markdown code blocks from raw LLM output.
Reusable across browser-based and API-based drivers.
"""

import re

from orchestrata_ultimate.core.traceability import traces


@traces(
    spec="025",
    reqs=[
        "REQ-025-080",
        "REQ-025-081",
        "REQ-025-082",
        "REQ-025-083",
    ],
)
def extract_file_blocks(
    response: str,
) -> list[tuple[str, str]]:
    """Extract FILE: blocks from LLM response text.

    Parses the standard format:
        FILE: path/to/file.py
        ```python
        <content>
        ```

    Args:
        response: Raw LLM output containing FILE: blocks.

    Returns:
        List of (filename, content) tuples.
    """
    results: list[tuple[str, str]] = []
    parts = re.split(r"^FILE:\s*", response, flags=re.MULTILINE)

    for part in parts[1:]:
        lines = part.split("\n")
        if not lines:
            continue
        filename = lines[0].strip()
        if not filename:
            continue
        code = _extract_fenced_code(lines[1:])
        if code:
            results.append((filename, code))

    return results


@traces(
    spec="025",
    reqs=[
        "REQ-025-084",
        "REQ-025-085",
        "REQ-025-086",
    ],
)
def extract_markdown_code_blocks(
    response: str,
) -> list[tuple[str, str]]:
    """Fallback: extract markdown code blocks without FILE: headers.

    Parses fenced code blocks with optional language tags:
        ```python
        <content>
        ```

    Args:
        response: Raw LLM output with markdown code blocks.

    Returns:
        List of (language_or_empty, content) tuples.
    """
    pattern = re.compile(
        r"```(\w*)\n(.*?)```",
        re.DOTALL,
    )
    results: list[tuple[str, str]] = []
    for match in pattern.finditer(response):
        lang = match.group(1) or ""
        content = match.group(2)
        if content.strip():
            results.append((lang, content))
    return results


@traces(spec="025", reqs=["REQ-025-082"])
def _extract_fenced_code(lines: list[str]) -> str:
    """Extract code content between ``` markers.

    Args:
        lines: Lines after the filename line.

    Returns:
        Extracted code string, or empty if no code block found.
    """
    code_lines: list[str] = []
    in_code = False
    for line in lines:
        stripped = line.strip()
        if stripped.startswith("```") and not in_code:
            in_code = True
        elif stripped == "```" and in_code:
            break
        elif in_code:
            code_lines.append(line)
    return "\n".join(code_lines) if code_lines else ""