orchestrata_ultimate.context.usage_log
Reference › orchestrata_ultimate › context › usage_log
This module records and summarises context usage (SPEC-107 FR-005). The assembler calls write_usage_record on every assembly, and the script scripts.context_usage_report reads the file back. Tests are in tests/context/test_usage_log.py.
write_usage_record appends one JSON line holding a UTC timestamp, the volk alias, the subject, the thread id and the usage dictionary from budget. The file path is the log_path argument, otherwise the environment variable ORCHESTRATA_CONTEXT_USAGE_LOG, otherwise logs/context_usage.jsonl. Parent directories are created. read_usage_records returns every record in a file, returns an empty list when the file is missing, and skips blank or malformed lines so one corrupt line does not break reporting. aggregate_usage returns the call count, total tokens spent, and totals per layer, per volk and per subject. The two I/O functions carry @traces for REQ-107-020 and REQ-107-021.
At a glance
| Source | src/orchestrata_ultimate/context/usage_log.py |
| Lines of code | 131 |
| Classes | 0 |
| Functions | 4 |
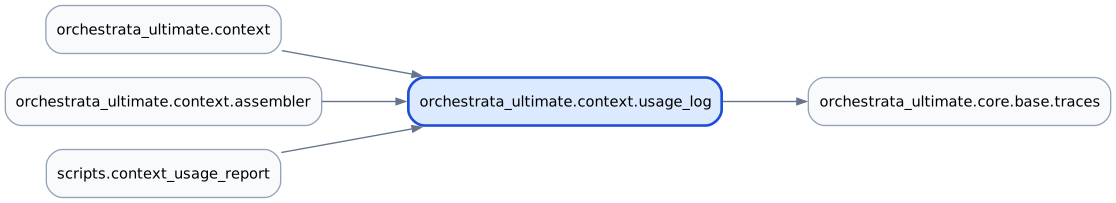
| Imports (internal) | orchestrata_ultimate.core.base.traces |
| Imported by | orchestrata_ultimate.context, orchestrata_ultimate.context.assembler, scripts.context_usage_report |
| Tests that import it | tests/context/test_usage_log.py |
Class diagram
No classes; see Functions.
Dependency diagram
API
Functions
| Function | Signature | Summary |
|---|---|---|
_resolve_log_path |
_resolve_log_path(log_path: str | Path | None, env: Mapping[str, str] | None) -> Path |
Resolve the log file path from argument, env, or default. |
write_usage_record traces |
write_usage_record(usage: dict[str, Any], *, volk_alias: str, subject: str, thread_id: str, log_path: str | Path | None = None, env: Mapping[str, str] | None = None) -> Path |
Append one context-usage record to the JSONL log. |
read_usage_records traces |
read_usage_records(log_path: str | Path) -> list[dict[str, Any]] |
Read all usage records from a JSONL file. |
aggregate_usage |
aggregate_usage(records: list[dict[str, Any]]) -> dict[str, Any] |
Aggregate a list of usage records into summary statistics. |
Source
"""Structured context-usage logging and aggregation.

Spec: SPEC-107 FR-005. Every ``UnifiedContextAssembler.assemble()`` call writes
a JSON line with per-layer token spend, the volk alias, and the subject. The
companion CLI script ``scripts/context_usage_report.py`` reads these lines and
produces aggregate reports.
"""

from __future__ import annotations

import json
import os
from collections import defaultdict
from collections.abc import Mapping
from datetime import UTC, datetime
from pathlib import Path
from typing import Any

from orchestrata_ultimate.core.base.traces import traces

_DEFAULT_LOG_PATH = "logs/context_usage.jsonl"


def _resolve_log_path(
    log_path: str | Path | None,
    env: Mapping[str, str] | None,
) -> Path:
    """Resolve the log file path from argument, env, or default."""
    env = env or os.environ
    if log_path is None:
        log_path = env.get("ORCHESTRATA_CONTEXT_USAGE_LOG", _DEFAULT_LOG_PATH)
    path = Path(log_path)
    path.parent.mkdir(parents=True, exist_ok=True)
    return path


@traces(spec="107", reqs=["REQ-107-020"])
def write_usage_record(
    usage: dict[str, Any],
    *,
    volk_alias: str,
    subject: str,
    thread_id: str,
    log_path: str | Path | None = None,
    env: Mapping[str, str] | None = None,
) -> Path:
    """Append one context-usage record to the JSONL log.

    Args:
        usage: ``ContextUsage.to_dict()`` value.
        volk_alias: Volk that received the assembled context.
        subject: CXP packet subject.
        thread_id: Pipeline thread id.
        log_path: Optional override for the JSONL file path.
        env: Optional environment mapping for testing.

    Returns:
        The resolved log file path.
    """
    path = _resolve_log_path(log_path, env)
    record = {
        "timestamp": datetime.now(UTC).isoformat(),
        "volk_alias": volk_alias,
        "subject": subject,
        "thread_id": thread_id,
        "usage": usage,
    }
    with path.open("a", encoding="utf-8") as fh:
        fh.write(json.dumps(record, separators=(",", ":"), sort_keys=True))
        fh.write("\n")
    return path


@traces(spec="107", reqs=["REQ-107-021"])
def read_usage_records(log_path: str | Path) -> list[dict[str, Any]]:
    """Read all usage records from a JSONL file.

    Skips malformed lines so a single corrupt record does not break reporting.
    """
    path = Path(log_path)
    records: list[dict[str, Any]] = []
    if not path.exists():
        return records
    with path.open("r", encoding="utf-8") as fh:
        for line in fh:
            line = line.strip()
            if not line:
                continue
            try:
                records.append(json.loads(line))
            except json.JSONDecodeError:
                continue
    return records


def aggregate_usage(records: list[dict[str, Any]]) -> dict[str, Any]:
    """Aggregate a list of usage records into summary statistics.

    Returns:
        Dict with ``total_calls``, ``total_spent``, ``per_layer`` totals,
        ``per_volk`` totals, and ``per_subject`` totals.
    """
    total_spent = 0
    per_layer: dict[str, int] = defaultdict(int)
    per_volk: dict[str, int] = defaultdict(int)
    per_subject: dict[str, int] = defaultdict(int)

    for record in records:
        usage = record.get("usage", {})
        if not isinstance(usage, dict):
            continue
        spent = usage.get("spent", 0)
        total_spent += spent
        per_volk[record.get("volk_alias", "")] += spent
        per_subject[record.get("subject", "")] += spent

        for key, value in usage.items():
            if key in {"total", "spent", "remaining"}:
                continue
            if isinstance(value, dict):
                layer_spent = value.get("spent", 0)
                if isinstance(layer_spent, int):
                    per_layer[key] += layer_spent

    return {
        "total_calls": len(records),
        "total_spent": total_spent,
        "per_layer": dict(per_layer),
        "per_volk": dict(per_volk),
        "per_subject": dict(per_subject),
    }