orchestrata_ultimate.context.providers.trimming
Reference › orchestrata_ultimate › context › providers › trimming
This module cuts a context layer down to a token budget while keeping the text coherent. The assembler applies it to every layer except system and user. Tests are in tests/context/providers/test_trimming.py. trim_to_budget carries @traces for REQ-106-030.
trim_to_budget returns the text unchanged if it already fits, and an empty string for a budget of zero or less. Otherwise it tries, in order, paragraph boundaries, sentence boundaries and word boundaries, using _trim_segments to keep the longest prefix of whole segments that fits. If even the first segment is too large, the next granularity is tried. With hard_limit true (the default) the last resort is _trim_by_bytes, a binary search over the byte length of the text that fits. With hard_limit false the original text is returned instead. Token counts come from the injected counter's count method.
At a glance
| Source | src/orchestrata_ultimate/context/providers/trimming.py |
| Lines of code | 123 |
| Classes | 0 |
| Functions | 3 |
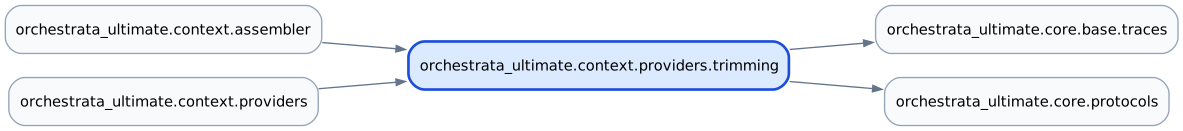
| Imports (internal) | orchestrata_ultimate.core.base.traces, orchestrata_ultimate.core.protocols |
| Imported by | orchestrata_ultimate.context.assembler, orchestrata_ultimate.context.providers |
| Tests that import it | tests/context/providers/test_trimming.py |
Class diagram
No classes; see Functions.
Dependency diagram
API
Functions
| Function | Signature | Summary |
|---|---|---|
trim_to_budget traces |
trim_to_budget(text: str, budget_tokens: int, counter: TokenCounterProtocol, *, hard_limit: bool = True) -> str |
Trim text to fit within budget_tokens. |
_trim_segments |
_trim_segments(segments: list[str], budget_tokens: int, counter: TokenCounterProtocol, *, join: str) -> str | None |
Greedily include segments until the budget is exhausted. |
_trim_by_bytes |
_trim_by_bytes(text: str, budget_tokens: int, counter: TokenCounterProtocol) -> str |
Binary-search the byte length that fits within the token budget. |
Source
"""Boundary-aware context trimming.

Truncates a context layer to a token budget while preferring whole sentences
and paragraphs over hard string slicing. This keeps LLM prompts coherent even
when a retrieved layer is larger than its reservation.
"""

from __future__ import annotations

import re

from orchestrata_ultimate.core.base.traces import traces
from orchestrata_ultimate.core.protocols import TokenCounterProtocol

# Split on sentence terminators followed by whitespace or end-of-string.
_SENTENCE_RE = re.compile(r"(?<=[.!?])\s+(?=\S)|\n{2,}")

# Split on blank lines (paragraph boundaries).
_PARAGRAPH_RE = re.compile(r"\n{2,}")


@traces(spec="106", reqs=["REQ-106-030"])
def trim_to_budget(
    text: str,
    budget_tokens: int,
    counter: TokenCounterProtocol,
    *,
    hard_limit: bool = True,
) -> str:
    """Trim *text* to fit within *budget_tokens*.

    Trimming prefers whole paragraphs, then whole sentences, then words,
    and finally bytes as a last resort. The returned text is always at or
    below the budget when *hard_limit* is True.

    Args:
        text: The layer text to trim.
        budget_tokens: Maximum tokens the returned text may consume.
        counter: A token counter with a ``count(text: str) -> int`` method.
        hard_limit: When True (default), guarantee the result fits the budget
            even if that requires mid-word truncation.

    Returns:
        Trimmed text. Empty string if *budget_tokens* is zero or negative.
    """
    if budget_tokens <= 0:
        return ""
    if not text:
        return text

    current = counter.count(text)
    if current <= budget_tokens:
        return text

    # First try paragraph boundaries.
    paragraphs = _PARAGRAPH_RE.split(text)
    trimmed = _trim_segments(paragraphs, budget_tokens, counter, join="\n\n")
    if trimmed is not None:
        return trimmed

    # Then sentence boundaries.
    sentences = [s for s in _SENTENCE_RE.split(text) if s.strip()]
    trimmed = _trim_segments(sentences, budget_tokens, counter, join=" ")
    if trimmed is not None:
        return trimmed

    # Then word boundaries.
    words = text.split()
    trimmed = _trim_segments(words, budget_tokens, counter, join=" ")
    if trimmed is not None:
        return trimmed

    if not hard_limit:
        return text

    # Final fallback: binary search byte length to fit the budget.
    return _trim_by_bytes(text, budget_tokens, counter)


def _trim_segments(
    segments: list[str],
    budget_tokens: int,
    counter: TokenCounterProtocol,
    *,
    join: str,
) -> str | None:
    """Greedily include segments until the budget is exhausted.

    Returns the joined prefix that fits, or None if even the first segment
    exceeds the budget.
    """
    if not segments:
        return ""
    # Fast path: include segments one by one.
    result_parts: list[str] = []
    for segment in segments:
        candidate = join.join(result_parts + [segment]) if result_parts else segment
        cost = counter.count(candidate)
        if cost > budget_tokens:
            if not result_parts:
                return None
            break
        result_parts.append(segment)
        if cost >= budget_tokens:
            break
    if not result_parts:
        return None
    return join.join(result_parts)


def _trim_by_bytes(text: str, budget_tokens: int, counter: TokenCounterProtocol) -> str:
    """Binary-search the byte length that fits within the token budget."""
    lo, hi = 0, len(text.encode("utf-8"))
    best = ""
    while lo <= hi:
        mid = (lo + hi) // 2
        prefix = text.encode("utf-8")[:mid].decode("utf-8", errors="ignore")
        if counter.count(prefix) <= budget_tokens:
            best = prefix
            lo = mid + 1
        else:
            hi = mid - 1
    return best