Orchestrata Ultimate › Gates › ci-pipeline
Gate: ci-pipeline
At a glance
| Purpose | Prove every pushed commit on a fresh runner: lint, types, architecture, the suite through the canonical runner, a coverage floor, the VizInt provenance gates and a package build. |
| Where it runs | GitLab CI from .gitlab-ci.yml (368 lines, last changed 9aa8a72f6, 2026-10-20) on the project MSamy/orchestrata-ultimate-architecture. The executor is the self-hosted Incus custom executor in deploy/gitlab-runner/ (shared runners hit ci_quota_exceeded on 2026-08-07, per its README). A second definition, .github/workflows/ci.yml, has no remote to run on (below). |
| Trigger | workflow: rules: schedule, web, merge-request event, branch push (suppressed while an MR is open for that branch), tag. |
| Exact command | Per job, listed below. |
| Blocks | A failed job fails the pipeline. Nothing local waits for it: deploy/ship.sh and scripts/hooks/pre-push contain no reference to pipelines, glab or the GitLab API (grep, 2026-10-23). CI is a report after the push, not a gate in front of it. |
| Ruling / ADR | RUL-004 (buildah, Incus executor, no docker-in-docker). The CI file itself is gated by validate-ci. |
Jobs
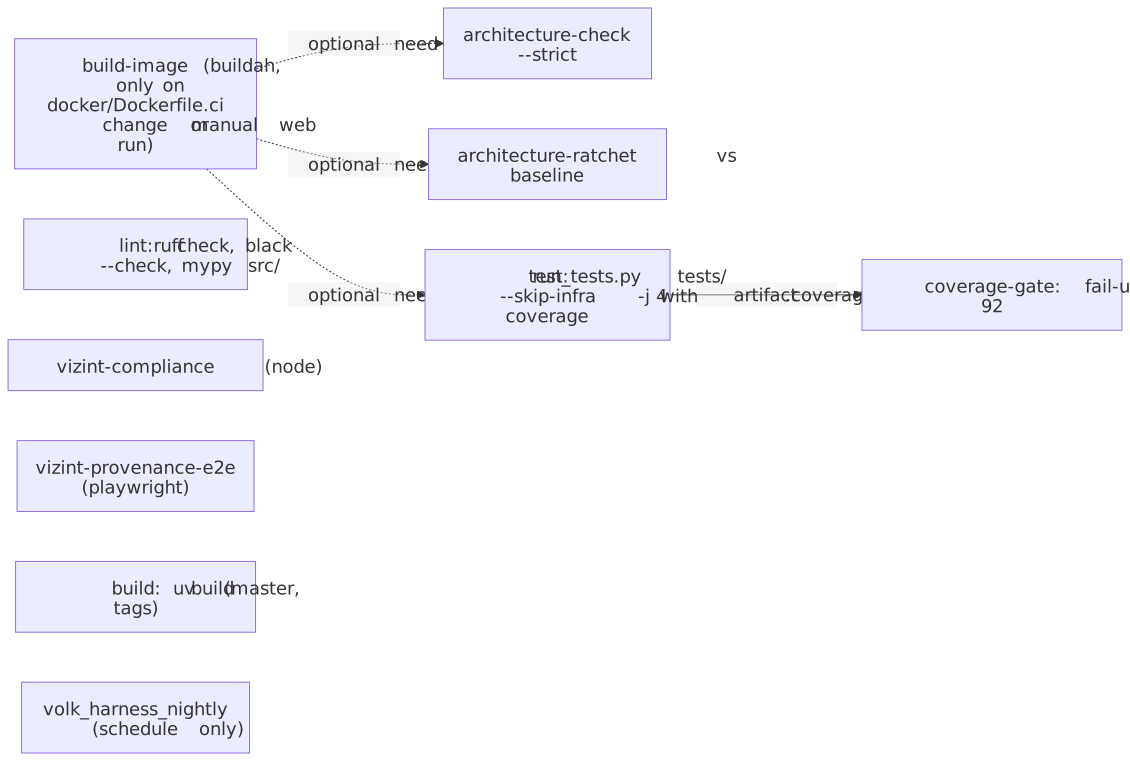
| Stage | Job | Command | Notes (from the file's comments) |
|---|---|---|---|
| docker | build-image |
buildah bud --format docker -t $CI_IMAGE -f docker/Dockerfile.ci . then buildah push |
buildah, not docker:dind (RUL-004): dind "could never start" on the Incus runner (pipeline 2742349337, job 15781528652). STORAGE_DRIVER=vfs, BUILDAH_ISOLATION=rootless (chroot and oci both failed to spawn the first RUN step). |
| lint | lint |
uv run ruff check src/ tests/ · uv run black --check src/ tests/ · uv run mypy src/ |
Shared setup uv sync --dev --no-editable; cache key uv-v2-… caches .uv-cache only (a cached 6.9 GB .venv filled the disk on 2026-08-07). |
| lint | architecture-check |
uv run --no-project python scripts/architecture_checker.py src/ --strict |
No uv sync (a stdlib-only scan once died building safetensors); --no-project still selects 3.14t because 59 files use PEP 758 except A, B:. |
| lint | architecture-ratchet |
uv run --no-project python scripts/architecture_static_check.py src/orchestrata_ultimate --baseline scripts/architecture_static_baseline.json |
Ratchets the static graph (TYPE_CHECKING and function-scoped edges, Tarjan cycle count); 100 lazy/type-only violations at the 2026-09-21 baseline. |
| lint | vizint-compliance |
node scripts/compliance-check.js (in vizint-ui/, node:20-slim) |
CONST-VII-101/102/103: no fabricated data. |
| test | test |
uv run python scripts/run_tests.py tests/ --skip-infra -j 4 with --cov=orchestrata_ultimate, --timeout=120; then coverage combine, xml, report |
Clones the rulings canon into .knowledge-wiki (RULINGS_DIR); JOB_USER: ci (four read-error tests are unreachable as root). Artifacts: coverage.xml, .flake_recoveries.ndjson, .coverage. |
| test | vizint-provenance-e2e |
npx playwright test tests/e2e/gateway-provenance.spec.js --project=chromium |
"gateway down ⇒ no data rendered"; needs no backend. |
| test | volk_harness_nightly |
python -m orchestrata_ultimate.harness run --all --trials 3, then report |
Schedule only; matrix VOLK: [qa, codedirector, architect]; image python:3.14. Whether a pipeline schedule exists, and which interpreter python -m resolves to after uv sync, were not measured. |
| coverage | coverage-gate |
uv run coverage report --fail-under=92 |
Consumes test's .coverage; until 2026-08-07 it re-ran the whole suite (~ten extra minutes). |
| build | build |
uv build |
master and tags only. |
What the test job really talks to
The job declares redis:7-alpine and neo4j:5-community services with endpoint
and credential variables (values not reproduced here). The file's own warning,
measured 2026-08-08 inside a live job: tests/conftest.py loads env/test.env with
override=True, so the suite reaches the Incus test fleet on 10.53.2.x instead,
and "a CI job and a local run_tests.py collide on the same Redis DBs and orchkg_w*
worker databases." Making CI hermetic was left as a separate decision.
Because the job calls run_tests.py tests/, the runner's gate-mode behaviour
applies in CI too: the freshness guard
runs (no --skip-freshness), and the
rehearsal exclusion
applies (paths are exactly tests/; reports/rehearsal-class-modules.json is
tracked in git).
CI and ship check different things
| Check | ship (orchestrata arm) |
GitLab CI |
|---|---|---|
| ruff, black | src/ tests/ scripts/ claude/ |
src/ tests/ |
| mypy | — | mypy src/ |
| RUL-007 range, plugin drift, env vs terraform | yes | — |
| Suite | run_tests.py --affected <last verified> |
run_tests.py tests/ with coverage |
| Coverage floor | — | 92% total |
| Architecture, VizInt | — | yes |
State on 2026-10-23 (measured, read-only)
- Pipelines. The last ten (iid 1169–1178, 2026-10-22T15:09Z to
2026-10-23T03:58Z; branches
masterandfix/ship-sanctioned-gate-pytest; sourcepush) are allfailed, each within about 1–2 s of creation (GitLab API via MCP). Pipeline 2979406170 (commita4cbc2bdf) has 8 jobs (lint, architecture-check, architecture-ratchet, vizint-compliance, test, vizint-provenance-e2e, coverage-gate, build), all failed; thelintjob's trace is 0 bytes, so no script line ran. - Runners. A system
gitlab-runner.serviceand a usergitlab-runner.service(/usr/local/bin/gitlab-runner run --config ~/.gitlab-runner/config.toml, started 2026-10-22 14:01 EDT) are both active. Neither journal has a singlejob=line since 2026-10-22 11:00 EDT (15:00Z); the system runner's last job line is 2026-10-22 05:28:55 EDT, job 17376209475,job-status=failed. So no job of those ten pipelines reached a runner on this host. - Cause: not measured. The signature (every job failed at about 0 s, nothing
ran) matches pipeline #2742244804 on 2026-08-07, which the runner README
attributes to
ci_quota_exceededon shared runners. The API calls used did not expose a failure reason, so whether today's cause is the same was not established. An open P1 backlog task (session-start report) records a separate, earlier failure: "CI jobs on the private registry image fail: incusd runs skopeo as ROOT and root has no registry.gitlab.com log[in]". That failure happens after a runner takes the job, so it does not explain jobs that no runner received.
The GitHub workflow
.github/workflows/ci.yml (142 lines, last changed d6ce4ce81, 2026-09-10): one job
quality on push and PR to main/master, with redis:7-alpine and
memgraph/memgraph:3.11.0 services. Steps: uv python install 3.14, uv sync --dev, ruff, code-review.py src/ --min-severity ERROR, architecture_checker.py --verbose, kg_schema.py apply and check, gen_level0.py --check,
gen_intent_lexicon.py --check, check-deps --include-tests, gate.py run,
untyped --max 0, pyright_ratchet.py --max 0 and --source tests --max 219,
check-traces --max 2219, check_async_await.py, audit_test_purity.py,
ast_report.py (advisory), validate_ci.py, then run_tests_threadpool.py tests/ -j 4 with coverage and a codecov upload.
- The repo's only remote is GitLab
origin; with no GitHub remote, whether this workflow runs anywhere was not measured. scripts/pyright_ratchet.pyis absent from the tree: it moved to codetools in71b4cd46f(2026-10-20, ADR-0118), so those two steps would fail as written.- It calls
run_tests_threadpool.pydirectly, which the GitLab file saysvalidate_ci.pygate 9 forbids for CI. Whethervalidate_ci.pyreads the GitHub file was not measured.
CI contends with the ship (measured 2026-11-06, ship-speed S17)
The runner (orchestrata-incus, id 58422150, concurrent = 2) runs on the same host as the
ship, the Hermes workers and the test fleet. Measured with the GitLab API, the job traces and the
cgroup tree:
- Two pipelines per ship.
deploy/ship.shpushes the feature branch (step 2) and then fast-forwards master (step 2b): the same sha twice, so GitLab ran two full pipelines. Ship 1106-d (7d3502e1f): master 30 min 39 s, branch 16 min 23 s. Ship N's pipelines were still running when ship N+1 started. - Jobs run one after another, with 50–100 s between them. The runner journal shows it idle
(
builds=0ofmax_builds=2) for the whole gap, so the delay is GitLab.com's scheduling, not the host. Inside a job the executor costs little: prepare 2–3 s, sources 5–7 s. - One CI job container weighs as much as the whole ship. Incus puts every container in a
root-level cgroup (
/sys/fs/cgroup/lxc.payload.<project>_<name>) atcpu.weight100, a sibling ofuser.slice, which is also 100 and holds everything run from the desktop session, the ship included.cpu.weightonly divides CPU between siblings, so under contention one job got as much CPU as the entire ship. Ship 1106-b'spromote prod(05:59:44–06:01:44Z) overlapped alintjob (06:00:27–06:02:12Z) and took 120 s against about 90 s. limits.cpu.priorityis not the knob. Incus turns it intocpu.sharesmoved by at most 10 out of 1024. An explicitraw.lxcline (lxc.cgroup2.cpu.weight = 10) is appended last to the LXC config and wins. Incus 6.15 accepts it on an OCI image launch (verified: an ephemeralrediscontainer with it reached RUNNING).- The uv cache never hit.
cache_dir = "/cache"is a path inside the throwaway job container. Every job logged "Cache file does not exist", then spent 16–17 s archiving 32,147.uv-cachefiles that no later job could see. A runner's "local cache" only persists if that path is mounted from the host. buildranuv sync --devfor nothing. It inherited.uv-setup'sbefore_script, whileuv buildmakes its own isolated build environment.- Per-job CPU cannot be recovered after the fact: sysstat samples every 10 minutes and the job
containers are deleted. Step timings come from the trace's
section_start/section_endmarkers.
The fix (c0ea6bd9b, brief plans/briefs/ci-yields-to-the-ship.md): the ship pushes the feature
branch with -o ci.skip when origin is gitlab.com, so only the master push runs a pipeline
(-o fails against a remote that does not advertise push options, such as a local bare repo).
The job and service containers launch at cpu.weight 10, so CI keeps every idle cycle and about
a tenth of a contended one, and nothing is stopped or killed. The cache block is gone, and
build has before_script: [].
Typical failures and how to fix them
| Symptom | Cause | Fix |
|---|---|---|
Every job failed in about a second, empty traces, nothing in the runner journals |
No runner received the jobs (2026-08-07: shared-runner quota) | Check the job's failure reason in the GitLab UI; confirm the self-hosted runner is registered for the project and accepts its jobs (deploy/gitlab-runner/README.md) |
build-image or prepare_exec fails before any step |
Executor or image problem (dind, registry auth) | buildah job as written; skopeo login for the registry user incusd runs as |
no space left on device during setup |
A cached venv restored under an old key | Bump the cache key when cache.paths shrinks (uv-v2 precedent) |
test red only in CI |
Shared test fleet with local runs; or running as root | Check for a concurrent local run on the same fleet; JOB_USER: ci |
coverage-gate red |
Total below 92% | Close the coverage gap; the per-file 90% rule is separate |
| A ship stage runs 30–100% slower than usual | A CI job overlapped it at equal CPU weight | List the jobs whose started_at/finished_at fall inside the stage's window; check a live job container's cpu.weight (/sys/fs/cgroup/lxc.payload.*glr-*/cpu.weight) reads 10 |
| Every job logs "Cache file does not exist" | /cache lives inside the job container |
Mount a host directory there, or declare no cache: (S17) |