scripts.intent_demo
Reference › scripts › intent_demo
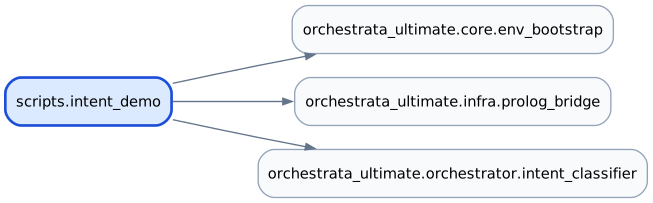
scripts/intent_demo.py shows what the intent pipeline does with a sentence. A human runs it as a demo. It uses orchestrata_ultimate.orchestrator.intent_classifier, orchestrata_ultimate.infra.prolog_bridge and orchestrata_ultimate.core.env_bootstrap. The Prolog side of the lexicon is generated by gen_intent_lexicon.
build constructs the production cascade, with the grammar tier in front and the vocabulary tier behind it. verdict classifies one utterance and returns a row with the work type, confidence, tier, evidence counts (winning over decisive hits) and whether the pipeline would dispatch or ask. Arguments are one or more sentences (otherwise a built-in list, DEMO_SENTENCES), --corpus to run the 76 captured real turns and compare with their gold work types, and --json for machine-readable rows. A failure to build the evaluator prints "CANNOT RUN" with the reason and exits 2. Otherwise it prints a table with a dispatch and accuracy summary and exits 0.
At a glance
| Source | scripts/intent_demo.py |
| Lines of code | 154 |
| Classes | 0 |
| Functions | 3 |
| Imports (internal) | orchestrata_ultimate.core.env_bootstrap, orchestrata_ultimate.infra.prolog_bridge, orchestrata_ultimate.orchestrator.intent_classifier |
| Imported by | none |
| Tests that import it | none |
Class diagram
No classes; see Functions.
Dependency diagram
API
Functions
| Function | Signature | Summary |
|---|---|---|
build |
build() -> IntentEvaluator |
The production cascade: grammar tier in front, vocabulary behind it. |
verdict |
verdict(evaluator: IntentEvaluator, text: str) -> dict[str, object] |
|
main |
main(argv: list[str] | None = None) -> int |
Source
Permalink: https://gitlab.com/MSamy/orchestrata-ultimate-architecture/-/blob/a4cbc2bdf/scripts/intent_demo.py
#!/usr/bin/env python3
"""Show what the intent pipeline does with a sentence — the demo seam.

Runs the REAL cascade against REAL infrastructure: the Prolog DCG grammar over
a live janus engine, the vocabulary fallback tier, the workflow mapper, and the
`IntentEvaluator` dispatch gate. No doubles, no canned answers.

It prints the verdict AND the evidence behind it, because the two are not the
same thing and the difference is the point:

    confidence   0.9 or 0.3 and nothing between (REQ-003-US-001-069 — a known
                 defect; every dispatch threshold in (0.30, 0.85] is identical)
    evidence     W/T decisive work-type words, W of them voting for the winner
                 (REQ-003-US-001-068). `0/0` on a grammar verdict means the parse
                 rested on a generic verb alone — the weakest thing the grammar
                 can return, and it scores the same 0.9 as a unanimous parse.

Usage::

    uv run python scripts/intent_demo.py                      # the demo set
    uv run python scripts/intent_demo.py "fix the login bug"   # one sentence
    uv run python scripts/intent_demo.py --corpus              # the real turns
    uv run python scripts/intent_demo.py --json                # machine output

Exit code is 0 whenever the pipeline ran; this is an inspection tool, not a
gate. It exits 2 if the pipeline could not be built at all.
"""

from __future__ import annotations

import argparse
import json
import sys
from pathlib import Path

REPO_ROOT = Path(__file__).resolve().parents[1]
sys.path.insert(0, str(REPO_ROOT / "src"))

from orchestrata_ultimate.core.env_bootstrap import load_env_contract  # noqa: E402

load_env_contract()

from orchestrata_ultimate.infra.prolog_bridge import PrologBridge  # noqa: E402
from orchestrata_ultimate.orchestrator.intent_classifier import (  # noqa: E402
    IntentEvaluator,
    NLIntentClassifier,
)

# One of each shape the cascade can produce, so a demo run shows the range
# rather than a curated best case. The last two are NOT work requests and must
# come back as `ask`, not as a dispatch.
DEMO_SENTENCES = [
    "fix the login bug in the gateway",
    "refactor the session module into smaller files",
    "the api is crashing on startup",
    "write documentation for the volk tools",
    "add a new volk",
    "no run allowed, i command you to stop",
    "should we promote to prod now?",
    "why did you stop in that state?",
]

CORPUS = REPO_ROOT / "tests" / "orchestrator" / "data" / "intent_corpus_raw_turns.json"


def build() -> IntentEvaluator:
    """The production cascade: grammar tier in front, vocabulary behind it."""
    bridge = PrologBridge()
    classifier = NLIntentClassifier(prolog_bridge=bridge)
    return IntentEvaluator(classifier=classifier)


def verdict(evaluator: IntentEvaluator, text: str) -> dict[str, object]:
    result = evaluator.evaluate(text)
    classified = result.classified
    return {
        "text": text,
        "work_type": result.work_type.value,
        "confidence": result.confidence,
        "tier": classified.tier if classified else "",
        "winning_hits": classified.winning_hits if classified else 0,
        "decisive_hits": classified.decisive_hits if classified else 0,
        "dispatch": not result.needs_disambiguation,
        "reasons": result.reasons,
    }


def main(argv: list[str] | None = None) -> int:
    parser = argparse.ArgumentParser(description=__doc__)
    parser.add_argument("sentence", nargs="*", help="sentence(s) to classify")
    parser.add_argument(
        "--corpus", action="store_true", help="run the 76 real captured turns"
    )
    parser.add_argument("--json", action="store_true", help="machine-readable output")
    args = parser.parse_args(argv)

    try:
        evaluator = build()
    except Exception as exc:  # noqa: BLE001 — say why rather than traceback at a demo
        print(f"[intent-demo] CANNOT RUN: {type(exc).__name__}: {exc}")
        return 2

    if args.corpus:
        cases = json.loads(CORPUS.read_text(encoding="utf-8"))["cases"]
        texts = [c["text"] for c in cases]
        gold = {c["text"]: c["work_type"] for c in cases}
    else:
        texts = args.sentence or DEMO_SENTENCES
        gold = {}

    rows = [verdict(evaluator, t) for t in texts]

    if args.json:
        print(json.dumps(rows, indent=1))
        return 0

    print(
        f"{'utterance':<54} {'work_type':<10} {'conf':<5} "
        f"{'tier':<11} {'evidence':<9} {'action':<8}" + ("  gold" if gold else "")
    )
    print("─" * (108 + (8 if gold else 0)))
    dispatched = correct = 0
    for row in rows:
        text = str(row["text"])
        evidence = f"{row['winning_hits']}/{row['decisive_hits']}"
        action = "DISPATCH" if row["dispatch"] else "ask"
        line = (
            f"{text[:52]:<54} {row['work_type']:<10} {row['confidence']:<5} "
            f"{row['tier']:<11} {evidence:<9} {action:<8}"
        )
        if gold:
            want = gold.get(text, "")
            hit = want == row["work_type"]
            line += f"  {'✓' if hit else '✗'} {want}"
            correct += hit
        print(line)
        dispatched += bool(row["dispatch"])

    print(
        f"\n{len(rows)} turn(s) · {dispatched} dispatched · "
        f"{len(rows) - dispatched} sent back for disambiguation"
    )
    if gold:
        print(f"{correct}/{len(rows)} match the corpus label")
    print(
        "\nevidence W/T = W decisive words voted for the winner out of T found.\n"
        "0/0 on a grammar verdict = parsed from a generic verb alone, yet still\n"
        "scores 0.9 — the one-bit-confidence defect (REQ-003-US-001-069)."
    )
    return 0


if __name__ == "__main__":
    raise SystemExit(main())